How Boarding School Waitlists Work: Timing, Signals, and What Actually Moves the Needle

Roughly one in four applicants to selective boarding schools ends up on a waitlist rather than receiving a flat yes or no. That number should feel like a stay of execution, not a death sentence. Plenty of families treat the waitlist as a polite rejection and move on, and honestly, that's a mistake. The waitlist is a live process with its own calendar, its own etiquette, and its own quiet signals. If you understand how admissions offices actually manage that pool, you can position your kid far better than the families who just sit and wait.

Here's what I'm going to walk you through: the real timeline of a boarding school waitlist, what admissions officers are looking for when they pull from it, and the exact moves that improve your odds. You'll get a clear decision framework plus a blunt look at when to let go. By the end, you'll know exactly what to do this week, this month, and by midsummer.
A group of five students in school uniforms standing in front of a notice board outdoors.

What a Waitlist Decision Actually Means

First, decode the language. When a school waitlists your child, they are saying three things at once. They believe your kid can handle the academic load. They think your family would fit the community. And they ran out of seats before they ran out of qualified applicants. That's not a rejection. That's a capacity problem on their end.

Admissions offices build their incoming class expecting a certain yield, the percentage of accepted students who say yes. When that yield runs higher than projected, the class fills up and the waitlist grows. When it runs lower, they start making calls. According to baseline enrollment data tracked by the National Association of Independent Schools, yield rates at independent schools fluctuate noticeably from year to year based on economic conditions and family mobility. So the size of the waitlist movement in any given spring is partly a numbers game you can't control.

What you can control is how you respond. And the single biggest mistake I see? Families who go totally silent after the waitlist letter arrives. That silence reads as lukewarm interest. Schools want students who want them, not students who view them as a backup.

When Does the Waitlist Actually Move?

Set your calendar around three distinct waves of movement, because they operate on completely different logic.

  • The first wave hits in the two weeks after decision day, typically late March or early April. Accepted students are making their final choices, and every family that picks another school opens a seat. This wave is the largest and the most unpredictable. Schools scramble to fill gaps with waitlisted kids who already sent a strong letter of continued interest.
  • The second wave comes in May, right after the common reply date and the deposit deadlines that follow it. Some families pay deposits at two schools to buy thinking time, then withdraw from one. That churn creates another round of openings. Schools know this rhythm well, which is why they keep waitlists active through May rather than closing them early.
  • The third wave is the summer scrape. It's rare, but it happens. A family relocates for a job, a student decides on a different path, or a financial aid package falls through. Schools then reach deep into the waitlist, often into June and even July. The U.S. Department of Education notes that private school enrollment decisions routinely shift over the summer as family circumstances change, so schools keep their waitlist pools warm until the first day of class.

Here's the part nobody charts for you: the later the wave, the more your demonstrated interest matters. By June, the school wants certainty. They'd rather take a solid waitlisted kid who has been visibly engaged for three months than risk a seat on a student who might vanish.

The Continued Interest Letter: Your One Real Lever

One letter. That's your primary tool. Not an email chain, not a phone call campaign, not a barrage of updated resumes. A single, well-crafted letter of continued interest sent within ten days of the waitlist decision.

The letter should come from the student, not the parent. Admissions officers are blunt about this. They want to hear from the person who will actually attend. Your kid should write two or three paragraphs that do four things: reaffirm that the school is their first choice, reference something specific from their visit or interview, share a recent achievement that strengthens their file, and ask a genuine question that keeps the conversation open.

I call this the Wardrobe Timeline framework, because it treats the letter like tailoring a suit. First, you take measurements: what does the school actually value based on their mission statement and recent newsletters? Then you cut the fabric: which of your child's recent accomplishments align with those values?

Finally, you stitch it together: one concrete example of your child acting on those values since applying. A student who started a tutoring club after their interview, and who mentions it in the letter, gives the admissions team something new to advocate for in committee meetings.

Skip the generic praise. "I love your beautiful campus and strong community" tells them nothing. Instead, name the specific biology elective your child sat in on and the question their future teacher asked that stuck with them. That level of detail signals genuine engagement, and it gives an admissions officer a concrete hook when they argue for your child at the next committee meeting.

One letter. Then stop. A second letter reads as anxious, and a third reads as desperate. Channel that energy elsewhere.

What Else You Can Do While You Wait

Beyond the letter, schools differ on what they welcome. Some happily accept an updated transcript or a new award. Others explicitly ask for nothing beyond the letter. Read the instructions in your waitlist notification and follow them to the letter. Overstepping a stated boundary is the fastest way to look like you cannot follow directions.

If the school allows it, consider a spring visit. Not the formal interview circuit, just a quieter visit to observe a class or attend a school event. That physical presence matters more than you'd think. Admissions staff remember the family that showed up for the spring art show, the one that came to watch the robotics team compete. Boarding schools track demonstrated interest carefully, and Boarding School Review consistently highlights that student-initiated contact and campus visits are among the strongest predictors of eventual enrollment for waitlisted applicants.

You should also make sure your current school sends an updated transcript if your child's grades have improved meaningfully since the original application. A strong third trimester can tip a borderline decision. But only send it if there's real news. A transcript that looks identical to the first one just wastes everyone's time.

How to Decide Between Waitlists

Here's where families get stuck. Your child is waitlisted at two schools. What do you do?

Rank them honestly. Which one did your child connect with more during the visit? Which one offers the program that actually fits their goals? Send the continued interest letter to your true first choice only. If you send letters to both, you're asking both to wait while your child decides, and admissions teams talk to each other. A school that senses it's your backup will drop you fast.

Consider the math of each school's waitlist movement in past years. Schools that are heavily oversubscribed, think schools with yield rates above seventy percent, rarely touch their waitlists. Schools that are still building their brand or expanding enrollment pull from the waitlist far more often. Pick the school where the waitlist actually moves.

The hardest question: how long do you wait? Here's my blunt answer. If you have a solid acceptance at a good school and you're waiting on a dream school that historically pulls very few waitlist students, you accept the bird in hand by the May deposit deadline. You can always withdraw if the dream school calls in June. But you never give up a guaranteed seat for a maybe. That's a gamble no admissions advisor would recommend.

One family I tracked through this process waited on two schools. Their son was waitlisted at both a top-tier school and a solid mid-tier program. They sent one letter to the top-tier school and accepted the mid-tier offer by the deadline. In late June, the top-tier school called. Their son enrolled, and they withdrew from the mid-tier with plenty of time for another waitlisted family to take the spot. Everybody won, which is exactly how the system is designed to work.

So before you finalize any decision, read through real Institut auf dem Rosenberg Reviews and comparable first-hand accounts from other families. Those detailed parent and student perspectives often capture the day-to-day texture of a school, the dorm culture, the weekend activities, the way teachers actually treat students, in ways that official materials never will.

Your Week-by-Week Action Plan

Stop spinning and start moving. Here's your calendar.

  • Week one: Write and send the continued interest letter. Have your child draft it, then edit together for tone.
  • Week two: Request an updated transcript if grades warrant it. Book a spring visit if the school allows it.
  • Weeks three through six: Stay quiet. No emails, no calls. Respect the process.
  • Late April: If you've heard nothing, one polite check-in email from your child asking about the decision timeline is acceptable.
  • May 1: Deposit at your backup school. Protect your family's position.
  • June through August: Keep your phone on. If a seat opens, the school will call.

That's the whole playbook. One letter, one visit at most, one backup secured, and a lot of patience.

The Wait Is the Work

Waiting feels passive, but it isn't. Every week you stay engaged, every update you share, every visit you make, you're telling the school that your child will say yes if they call. That's the only message that matters. By early August, if no call has come, accept the outcome and pour your energy into the school that said yes. Your child will thrive wherever they land, and honestly, the best boarding school fit is rarely the most prestigious one. It's the one where your kid actually wants to wake up on a Tuesday morning.
Why Independent Agencies Are Ditching Legacy DSPs for an Agile Programmatic Platform

The days when giant network agencies and walled gardens could completely corner the media buying market are pretty much over. For years, independent agencies were stuck playing a rigged game, forced to use rigid legacy platforms built for massive brands with bottomless budgets. But that trade-off just doesn't make sense anymore. Today's indies can't afford to burn client money on hidden tech taxes, obscure algorithm black boxes, or absurd spend minimums that eat up margins. Clients are asking tough questions about where every dollar goes, and "trust the algorithm" isn't a valid answer anymore. To stay profitable and keep up with how fast digital culture actually moves, sharp media teams are quietly cutting ties with clunky enterprise software. They’re rebuilding their stacks around flexible, API-driven tools where they actually own their data and control their own strategy.

A stack of classic black and white photographs showcasing family memories and history.

The Legacy Trap: How Outdated Tech Throttles Agency Growth

Let’s be honest: those old-school DSPs promised to be all-in-one powerhouses, but they’ve turned into giant operational headaches. They operate as completely opaque black boxes. You often get limited visibility into bid shading logic, supply chain costs, and log-level data – unless, of course, you're willing to pay extra for access to your own campaign info. For an independent agency, that kind of opacity becomes a serious commercial risk when a client demands an audit. On top of that, basic campaign management feels stuck in 2012. Media traders still spend too much time adjusting pacing, checking performance across different dashboards, and pulling data into Excel. Throw in aggressive spend minimums – which force smaller agencies to take on significant financial risk just to keep the lights on – and the whole setup starts looking like a trap. When you want to test a niche contextual vendor or bring your own first-party data, these legacy tools can quickly become restrictive. Instead of serving your team, a rigid programmatic platform from the last decade ends up dictating how you run your entire agency business.

The Modern Stack: What Indies Demanded, Modern Tech Delivered

Today’s ad tech isn't built to lock you into a proprietary ecosystem. Instead, it’s modular by design – it pipes directly into your current tech stack without throwing your daily workflow into chaos.

  • Composable Architecture (API-First): The platform plugs into your existing CDP, attribution tools, and creative systems through APIs. You keep your existing stack instead of rebuilding your workflow around another closed platform.
  • Radical Transparency: You get the raw log-level data without extra fees or artificial delivery delays. That means you can see the bids, supply costs, and where the media budget is going.
  • Agentic AI & Direct Supply: AI-driven optimization can go beyond basic rules and optimize for CPA, ROAS, and incremental conversions to drive actual profit instead of just chasing CTR.

Winning on Agility: The Strategic Advantage for Independent Agencies

Ditching legacy platforms isn't just about getting better software – it is a direct growth strategy. Independent agencies don't try to beat big network holdings on headcount; they win because they move faster, adapt quicker, and build real relationships with their clients.

When you strip out the hidden fees buried deep in legacy supply chains, that money goes straight back into working media. Campaigns perform better, and your margins become easier to protect. Automated pacing and AI-assisted execution take care of the soul-crushing manual data-wrangling, freeing up your buyers to actually think about high-level media strategy. Above all, being upfront about costs keeps clients around. When you lay out raw spend logs and back up performance with clean numbers, you don't have to constantly pitch your value – the proof is right there.

A Buyer's Checklist: Evaluating Next-Gen Platforms

Switching ad tech hurts, but holding onto dying software costs way more and drains agency resources. Before you lock into a new deal and risk your margins, test vendors on these core points:

  • Open Integration: Does the platform connect natively to your existing stack through open APIs, or do you have to keep its data and reporting separate in yet another isolated silo?
  • True Data Ownership: Do you get free access to raw log files, or is the vendor charging you extra just to audit your own spend?
  • No Heavy Commitments: Does pricing scale cleanly with your volume, or are you locked into aggressive monthly minimums regardless of spend?
  • Actionable Automation: Does the platform’s AI actually handle complex, real-time optimization, or is it just a glorified rule script with a fancy marketing label?

The Shift Is Here

The exodus from legacy DSPs isn't a temporary trend; it's a permanent shift in how independent agencies operate. As the digital media ecosystem fragments even further and advertisers demand absolute financial accountability, relying on slow, closed-off tech is a quick path to losing your best accounts. Programmatic growth now belongs to small, fast teams backed by transparent tech and automation. Upgrading your stack does more than lower software bills – it gives you the speed needed to take market share from slow-moving giants.

How to Stop Hitting Your Claude Code Usage Limit: 5 Pile Clearing Habits for Continuous Use

In my company, we have a Claude Team Plan. We have five standard seats and one Premium seat – which is the same as Claud Max in the personal version. I use a standard seat. In my usage, I use Claude Code 6-8 hours – not just for coding but also for general conversations, web search, and learning. I like everything in one spot. My co-worker is a madman; vibe coding a dozen apps ranging from in-house tools to some real attention-getting phone apps. 

  • I run out my 5-hour-limit, maybe twice a month. I never get more than 40% of my weekly-limit.
  • My colleague has five times my limit – and runs the 5-hour limit out 3 times a day, and the weekly limit out after only 3 days.

Suddenly, this week, I ran out of my 5-hour-limit in twenty minutes! At 7:30 a.m., I was stopped, dead in the water – reset in 4 and a half hours.

So this article is for the me from yesterday – a better understanding of limits, what burns them, how to use them. My hope is the future-me will again attain the glowing status of 100% Claude Availability even on my 8-hour sessions.

Keywords in this article:

  • Conversation – One thread in Claude Code
  • Turn – One message sent with a reply from Claude
  • Pile – The active context size that gets sent to Claude-Cloud from the conversation
  • Token – AI Token – one word is about 1.4 tokens.

The goal of this article is to help you understand your own credit-burning habits and how to optimize Claude Code to optimize your token use. I hope that you can double your usage while completely avoiding the 5-hour-limit or the weekly-limit.

The Quick Fix: Reset Your 5-Hour Limit Right Now

Are you locked out right now? Start here.

Claude Code has a command called `/limit-reset`. It clears your 5-hour-limit immediately.

/limit-reset

You get one per week. Your usage after the reset still counts against your weekly-limit. So it borrows from the week ahead. It does not give you more.

Two warnings. The command is undocumented. It doesn’t appear in any official Anthropic changelog. It also declines sometimes, and no one has published the rules for who gets approved.

OpenAI Codex works differently. The command is `/usage`.

/usage

For OpenAI – at least they documented it. A “code reset” sits on your account until you spend it or it expires. It looks like Anthropic just copied it (hastily), and that is why theirs is undocumented and feels ad hoc.

It is also worth observing that both OpenAI and Anthropic generally do a “reset everyone” once or twice a month – usually coinciding with a new product rolling out. When OpenAI rolled out ChatGPT 5.6 and Anthropic rolled out Fable 5.1, everyone got a reset, regardless of whether you use that particular model.

What the Claude Usage Limit Actually Is

You have two limits, not one. The 5-hour-limit is a rolling window. It starts when you send your first message. Five hours later, that window closes. A new one opens on your next message.

The weekly-limit sits on top. It runs across all models. You can be fine on the 5-hour-limit and still be stopped by the weekly one.

Here is what a lockout looks like. Claude stops mid-conversation. You get a banner with a reset time. Nothing you type works until that clock runs out. Mine said noon. It was 7:30 in the morning.

One recent improvement helps. Claude Code now resumes a stopped conversation automatically once your limit resets. You no longer have to sit and watch.

How much you get depends on your seat:

  • Claude Pro is the baseline.
  • Claude Max gives 5x or 20x more per session than Pro.
  • Claud Team Standard seats give 1.25x Pro.
  • Claude Team Premium seats give 6.25x Pro.

A Premium seat is exactly five times a Standard seat. My colleague has five times more than I do, and he’s always running out.

This year, Anthropic offered a temporary 50% boost, which they ended and replaced with a permanent 25% increase. This isn’t really why you are running out, but it is a small factor.

The Real Culprit Is The Way You Use Chat

Claude Code logs your conversation locally. Every turn is recorded with its token count.

That day I used 23.8 million tokens. Four conversations were active. One of them accounted for 21.1 million of it. That is 89% of my entire day, from a single conversation.

You can ask Claude right now what your Turns and Tokens are for this conversation:

This conversation: 212 turns, 25.9 million tokens.
Avg per turn: 122,063
Current pile: 188,496 (was 82K when we started)
Output from me: 105,212
Span: yesterday 12:01 to now

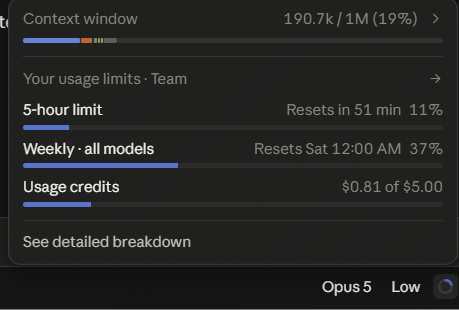
Now look at the little usage window. IT shows about 25% of the circle is filled. So here’s a new rule:

DO NOT EVER LET THE CIRCLE HIT 25% – Compact.

Claud told my my current pile is 188k. That’s too big. If I cut that to 60k – I can have 3 times more turns for the same usage.

Try this: 

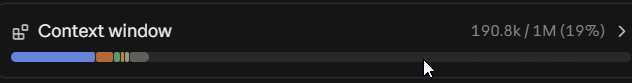
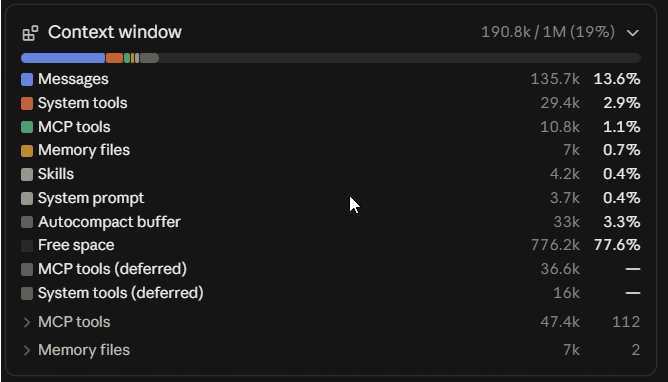
/context

Then hit the little right arrow on it.

Here is the part that stopped me. Each turn cost about 500k tokens. My other conversations that same morning cost 80k per turn. Same work. Same day. Six times the price.

The fallacy is that 75% free space is a technical limit. You can drive a dump truck to the grocery store, but it’s more practical to use a Honda.

For me, the next step is this:

/compact keep the article draft, the outline, and the token measurements; drop the tool-debugging and search results

The compact sends the whole pile (190.8K) as input, then writes ~4-5K of summary as output. The benefit is on the next turn.

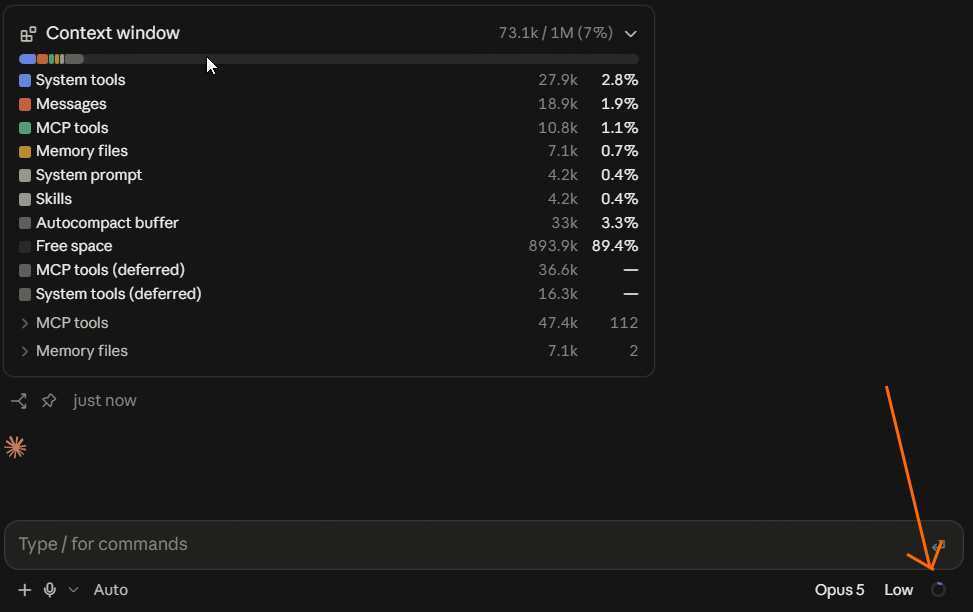
So this moved me from 19% to 7% in my context buffer. My conversation moved from 190.8k  per turn to 73k per turn. The conversation part went 135.7k to 18.9k – a 7x cut. 

Anthropic says that Pro level (individual plan) should get 45 turns per session. I have the Team Plan, Standard Seat, which should be 1.25x Pro. So far today, I have had 118 turns. But the compact moved me from 518 turns left to 1350 turns left. This is how you get nearly unlimited Claude Code usage. 

So the simple tool is – Keep that blue circle really small – use Compact Freely.

Use Autocompact as a Safety Net

Claude Code has a feature called autocompact. It summarizes your conversation when the pile nears the point you set.

Look at where the trigger sits. Run /context and you will see a line called “Autocompact buffer.” On my session it reserved 33k against a 1m context window. So autocompact would not fire until the pile reached roughly 967k.

Think about what that means. Every turn between here and there gets charged at whatever the pile weighs at that moment. A 900k pile costs 900k on every single turn. Autocompact arrives after you have already paid.

This is the trap. People watch the percentage free and feel safe. Mine said 89% free. That’s your technical buffer, while you are still driving a dump truck to the grocery store. You can move the trigger yourself:

/autocompact 200k

Now the summary happens at 200k instead of 967k. This will guarantee you 5 times more turns in your 5-hour-limit and weekly-limit.

 Ten  Habits That Keep the Pile Small

Habit 1 – Compact When the Circle is at 25%, not at 75%

We all know to watch the little circle, but we never knew the goal. The circle allows you to fall in the habit of using too much context. If you compact when it hits 25% – you will get multiples more turns than if you let it move past 75%. 

Habit 2 – Force Short Replies

Every word joins the pile forever. A chatty 180-word answer is about 250 tokens. GPT engines are self-serving in sending you blabby responses and then charging you to reply. 

Put a rule in your CLAUDE.md file:

 Be extremely concise. No filler. Answer directly. 
 Do not restate my question. Do not explain what you 
 are about to do before doing it. No hedging.

Claude says: Cheapest fix on the list. One line of setup. 

Claude lies. I have to remind Claude about every 10 turns to keep things concise. Claude training wants to fill my context with unnecessary blab. Claude training was done by Anthropic engineers with unlimited accounts. Do not ever forget that.

Habit 3 – Never Let Claude Code Sweep Your Drive

Ask a vague question. Claude goes looking. Claude’s training was done by AI Engineers with unlimited resources. So Claude uses Glob or LS paths that can return 8000 responses, and then sends to Cloud as tokens. A single drive search can cost you 30% of your 5-hour-limit in about 2 minutes.

 Never run an unscoped or recursive file search. This
 covers Glob with **, find without a tight starting
 directory, grep -r from a high directory, and ls -R.
 Scope every search to one directory with a narrow
 pattern. Prefer a date-sorted listing over a full
 enumeration. If the right directory is not obvious,
 ask me which one before searching.

 Name the directory. Ask for a narrow pattern. Prefer a date-sorted list. The newest file is almost always the answer.

Habit 4 – Retire Old Conversations

Resuming a conversation from three weeks ago feels efficient. It is the opposite. It’s far cheaper to start a new conversation with a memory, than to revive an old one.

I had one running since August. The transcript file had grown to 35MB. Every turn cost about 500k tokens. A healthy conversation runs 80k. Forty-two turns in that one conversation ate 21.1 million tokens – 89% of my entire day.

One of those turns produced a 69-token reply. It cost 485,961 tokens.

Start a new conversation instead. Anything worth keeping belongs in a memory file, not in scrollback.

Habit 5 – Audit Your Fixed Overhead

Claude Code writes a transcript for every conversation. JSONL, with a token count on each message. They live in your home folder under .claude/projects.

This prints every conversation, its turn count, and its average pile weight:

 cd "$USERPROFILE/.claude/projects" 
 python -c " 
 import json,glob,os 
 for f in glob.glob('*/*.jsonl'): 
     n=ctx=0 
     for line in open(f,encoding='utf-8',errors='replace'): 
         try: d=json.loads(line) 
         except: continue 
         u=(d.get('message') or {}).get('usage') 
         if not u: continue 
         n+=1 
         ctx+=u.get('input_tokens',0)+u.get('cache_read_input_tokens',0)+u.get('cache_creation_input_tokens',0) 
     if n: print('%9d tokens %4d turns %8d avg %s'%(ctx,n,ctx//n,os.path.basename(f)[:8]))  "

Sort by that last column. The worst offender will be obvious.

Habit 6 – Do NOT Thank Claude, Swear at Claude, or Tell Claude Your Opinion

It is human nature to converse. To say “It worked” or “You were stupid for deleting the only copy of our company payroll file.” 

Claude Code is a machine: it has no feelings and does not learn from your reaction. It will try to behave better next time. It is a machine. Keep that in mind. You don’t tell your car, “Thank you for letting me drive you to work.”

Every constructive comment, criticism, greeting and thank-you drains your context window. It uses “Gas”. It accomplishes nothing. Tell your co-worker how dumb Claude is, but don’t tell Claude because Claude will bill you for it.

Habit 7 – Batch your questions

Each turn costs a full pile, no matter how small the question. Five quick questions cost five full piles. Asked together, they cost one. Short questions cost the same as long questions. Or, to put it another way – In the world of AI, one virtual cucumber slice has the same calorie cost as the virtual steak and lobster dinner with the milkshake. Order the steak!

Habit 8 – One job per conversation.

My morning mixed tool debugging with article writing. The debugging output stayed in the pile for every writing turn after it. Separate conversations would have cost half.

Habit 9 – Do not make Claude re-read

“Show me that file again” re-sends the whole file. It already has it. Same for “are you sure?” – that re-runs everything to confirm what it already said.

Summary

The key to longer Claude sessions and an unbroken workflow is understanding the pile that flows from your workstation to Claude Cloud with every turn. Anthropic has given you tools, but we’ve all failed to appreciate how to structure our workflow to make the most of them. Claude engineers all have unlimited accounts, and didn’t know to tell the working public that has to use metered accounts.

Hopefully these tips helped you learn how to control your own pile and get more out of your work sessions.

What Evidence Helps Drivers Prove Fault in a Car Accident Claim

Proving responsibility after a collision requires more than an injured driver’s account. Insurers examine physical damage, roadway conditions, witness observations, medical timing, and vehicle information before accepting liability. Each record should help answer two questions: what happened, and how did another motorist’s conduct cause harm? Prompt documentation preserves details that may disappear with time. A clear evidence file also helps legal counsel challenge disputed statements, calculate losses, and present a consistent account of the crash.

A police officer writes a ticket as the driver looks on from inside the car.

Why Legal Guidance Can Help

A claim may involve conflicting accounts, missing footage, delayed symptoms, or disagreement about traffic rules. A car accident lawyer in Concord, CA, can examine available records, locate missing evidence, and protect materials before they disappear. Counsel may also handle insurer communications, compare testimony, consult medical or collision experts, and organize the facts into a coherent liability argument. That assistance lets an injured motorist focus on treatment without weakening the case through avoidable statements or missed deadlines.

Police Reports Establish Early Facts

A police report usually records the location, reported statements, vehicle positions, weather, roadway conditions, and officer observations. Citations, admissions, or descriptions of unsafe conduct may support a fault argument. Still, an officer’s report does not conclusively determine civil liability. The driver should obtain the document promptly and check it for omissions involving witnesses, signal phases, visible injuries, or damage patterns. Corrections should receive attention before inaccurate details influence later evaluations.

Photographs Preserve the Scene

Images may show crushed panels, broken glass, tire marks, scattered debris, lane placement, traffic signs, lighting, and surface defects. Photographs of wounds may document bruising, swelling, lacerations, or limited movement soon after impact. Wide-angle shots establish setting, while close images capture useful details. Original files should remain intact, including available timestamps and metadata. Short videos may show signal changes, blocked sightlines, standing water, or other conditions that still photographs cannot fully explain.

Witness Statements Add Independent Support

A person who observed the incident may clarify speed, direction, lane movement, braking, signaling, or driver attention. Contact details of eyewitnesses should be recorded immediately, along with a brief account in that observer’s own words. Memory becomes less precise after repeated conversations, so taking early notes matters. Even limited testimony, such as seeing a vehicle enter an intersection during a red phase, may challenge an inaccurate version given by another motorist.

Traffic and Security Footage

Intersection cameras, store recordings, apartment systems, transit equipment, and nearby dashboard cameras can capture events that participants cannot recall clearly. Many systems overwrite files within days or weeks. A preservation letter should identify the date, time range, location, and vehicles involved. Counsel may pursue a formal demand if an owner refuses cooperation. Footage can reveal speed, lane position, signal timing, impact sequence, and whether a driver looked down before moving.

Medical Records Help Connect Injuries to the Crash

Clinical notes, imaging results, prescriptions, therapy records, and billing statements can connect physical harm to the collision date. Prompt evaluation builds a stronger timeline, though delayed symptoms can still be legitimate. Concussions, spinal strain, and certain soft tissue injuries may develop gradually. The patient should accurately describe pain, numbness, weakness, dizziness, and activity limits. Following prescribed care also creates a record showing how symptoms affected daily tasks and employment.

Physical Damage Supports Causation

Repair estimates, inspection reports, towing invoices, and photographs may show impact direction and force. Damage patterns can challenge claims that a collision was too minor to cause reported injuries. An independent examiner may distinguish fresh damage from earlier defects or determine whether a mechanical failure contributed to the event. Insurer estimates deserve careful review when they rely on limited photographs, omit hidden damage, or use assumptions that conflict with the available record.

California Uses Comparative Fault

California allows an injured person to recover damages even if they bear responsibility. The final award decreases according to the assigned percentage of fault. For example, a claimant found 20% responsible may receive 80% of proven damages. Evidence should address every contested action, including speed, following distance, signaling, lane changes, visibility, road position, and reaction time. A strong case responds to opposing arguments instead of focusing on one favorable fact.

Organizing Evidence Strengthens the Claim

A well-organized evidence file may include the police report, scene photographs, witness contacts, medical records, repair documents, insurer letters, wage information, and a dated crash timeline. Each item should show its source and collection date. Separating liability records from injury and financial documents makes review easier. Proper organization helps counsel identify contradictions, request missing materials, and present responsibility, treatment, and monetary loss in a logical sequence.

Conclusion

Fault is usually established through several connected records, rather than one decisive document. Police findings may provide an initial account, while photographs, witnesses, footage, medical files, vehicle data, and repair records fill critical gaps. Early preservation matters because recordings can be erased, vehicles can change, and recollections can weaken. An organized claim gives an insurer fewer grounds to dispute responsibility. It also helps the injured driver seek payment supported by reliable, verifiable facts.

Why Short-Term Crypto Price Predictions Face More Noise Than Long-Term Models

Quick Answer

Short-term crypto price forecasts operate in an environment dominated by order flow, leverage, liquidations, breaking news, and sentiment swings, much of which carries little repeatable information. As the forecast horizon shrinks to hours or minutes, separating a genuine signal from noise gets harder. Over longer horizons, individual shocks matter less, and slower-moving variables such as liquidity cycles, adoption, network activity, and valuation have more room to show up in the data. Longer-term models can therefore sometimes capture structural signals more effectively, though they carry their own risks and are not inherently more accurate.

Smartphone showing bitcoin price with a physical coin and text representing cryptocurrency investment.

A Price Target Is Not the Same as a Reliable Forecast

"BTC will reach $X tomorrow" and "BTC has a higher probability of staying within a broad valuation range over the next 12 months if liquidity, adoption, and macro conditions persist" can look like similar claims. The second is easier to evaluate, because it states a range, a probability, and the conditions it depends on.

Three ideas run through this article: the forecast horizon (how far ahead a model looks), the signal-to-noise ratio (how much price movement reflects persistent information rather than randomness), and the difference between a point forecast and a probability or range forecast.

Recent history is a useful reminder of how fast conditions shift. CME analysis noted an approximately 50% Bitcoin correction between October 2025 and February 2026, with downside option implied volatility surging during the sharpest part of the move.

Read more: The Factors That Could Get Bitcoin's Bull Cycle in Full Swing

Why Are Short-Term Crypto Price Predictions So Difficult?

Market Noise Can Overwhelm the Underlying Signal

In a single hour, Bitcoin can trade thousands of times while almost nothing about its fundamentals changes. Prices over that window respond to individual large orders, temporary order-book imbalances, spreads and liquidity, arbitrage between venues, exchange-specific flows, and algorithmic trading. A model can correctly identify the underlying trend and still miss the next candle.

The problem is sharper for smaller altcoins with thinner order books, where one sizable order can move the price several percent. That is why any VLXX coin price prediction today is best read as a rough range rather than a precise number.

Leverage and Liquidations Create Nonlinear Moves

Perpetual futures and other derivatives let traders amplify positions, and that sets up a feedback loop. A price move triggers liquidations, liquidations generate forced orders, and those orders push the price further, which triggers more liquidations. Because cascades like this are nonlinear, relationships that held in calm markets tend to break down precisely when stress peaks.

News and Sentiment Arrive Faster Than Models Can Adapt

A regulatory announcement, unexpected ETF or institutional flow data, a macroeconomic release, an exchange or protocol incident, or a large whale transaction can reprice the market within minutes. Technical and machine-learning models react quickly to recent data, yet that same responsiveness invites overfitting and false signals. One Bitcoin forecasting study found hourly returns broadly difficult to predict, with forecastability depending heavily on the volatility regime.

Why Can Longer-Term Models Sometimes Capture Stronger Signals?

Extending the horizon does not automatically improve accuracy. What it changes is the kind of information a model can use, and the kind of mistakes it is exposed to.

Individual Shocks Carry Less Weight

A one-minute liquidation cascade can decide a one-hour forecast, but it may barely register in a thesis about a 12–24 month cycle unless it changes broader conditions. In that narrow sense, short-term noise matters less as the horizon lengthens.

That does not mean uncertainty shrinks. Long horizons bring their own problems: structural breaks, regulatory and monetary policy changes, correlations that shift between regimes (Bitcoin's relationship with equities, for instance, has not been stable), and the growing chance that the model's core assumptions stop holding. A long-term forecast trades one type of uncertainty for another.

Slow-Moving Variables Have Time to Matter

Longer horizons give weight to signals that are invisible on a five-minute chart: network adoption, active addresses and blockchain activity, holder behavior, liquidity and credit conditions, interest rates and dollar strength, institutional participation, supply structure, and market-cycle valuation. A 2026 machine-learning study examining macro and crypto-specific factors found MVRV, new addresses, and active addresses among the influential predictors, which shows how broader datasets can feed into return models.

Long-Term Models Can Forecast Regimes Instead of Individual Candles

An exact target says "BTC = $X on December 31." A regime model assigns probabilities to bullish, neutral, and bearish environments, each paired with a valuation range. The regime approach doesn't need to know the path price will take. It needs a reasonable estimate of the environment price is likely to operate in, and that is often a more tractable question.

Short-Term vs Long-Term Crypto Prediction Models: What Changes With the Time Horizon?

FactorIntraday / 1 DayWeeks / Months1+ Year
Dominant informationOrder flow, momentum, derivativesTrends, liquidity, sentiment, macro dataAdoption, valuation, macro regime, network fundamentals
Signal-to-noise ratioLowModeratePotentially higher for structural signals
Common modelsTA, order-book models, MLMomentum, macro + on-chain, MLFundamental, network, valuation, scenario models
Best outputProbabilitiesRanges + scenariosBroad scenarios / valuation bands
Main advantageFast reactionBalances recent and structural dataFilters much short-term noise
Main riskNoise and false signalsRegime changesStructural assumptions may fail
Exact-price usefulnessVery limitedLimitedStill highly uncertain

Reading down the table, the risks don't disappear as the horizon grows; they change character. Short-term forecasts struggle mainly with noise. Long-term forecasts struggle mainly with uncertainty about future regimes and whether their assumptions will hold. Anyone evaluating a prediction should first ask which of those two problems it is exposed to.

Scenario Analysis: How the Same Bitcoin Market Can Produce Three Very Different Forecasts

The example below is a hypothetical illustration. The $80,000 starting price and every range shown are invented to demonstrate how horizon changes a forecast's form. None of them is an actual price forecast.

Imagine Bitcoin trading at $80,000. Volatility is elevated, derivatives positioning is shifting, network activity is stable, and macro liquidity is neutral.

24-Hour Forecast

A short-term model in this setting might output an illustrative range of $77,000–$83,000. Even so, confidence should stay low. A single headline, liquidation cascade, or order-flow shift could invalidate that range within hours.

Three-Month Forecast

Over a quarter, the model would weigh trend structure, ETF and institutional flows, monetary conditions, and derivatives positioning. Instead of one range, a reasonable output would be bear, base, and bull cases, each with an assigned probability.

12-Month Model

A year out, the emphasis moves to conditions rather than timing: the liquidity regime, adoption, network valuation, capital flows, and cycle structure. What comes out is a set of broad valuation scenarios, along with the assumptions each depends on, rather than a claim that Bitcoin will reach a particular price.

Notice that the ranges widen as the horizon extends. A wider range can still be more informative if it is honest about the assumptions behind it.

How Should You Judge Whether a Crypto Prediction Model Is Actually Reliable?

Ask What the Model Is Predicting

Exact price, direction, return, volatility, price range, and scenario probability are different targets, and they shouldn't be judged by the same accuracy metric. CME's 2026 introduction of Bitcoin Volatility futures makes the point concrete: participants can trade expectations for 30-day volatility without taking any view on direction. Magnitude and direction are separate forecasting problems.

Check Out-of-Sample Performance

Give the most weight to models tested on data they weren't trained on. Impressive backtests often owe more to overfitting, data leakage, cherry-picked periods, or aggressive parameter tuning than to genuine predictive power. Research has shown that some predictors that look useful in-sample lose much of their forecasting power in out-of-sample crypto tests.

Look for Ranges, Probabilities, and Invalidating Conditions

Point forecasts are a legitimate output, and many serious models produce them. The trouble comes when a single number arrives with no confidence interval, probability range, validation record, or stated assumptions. Without that context, readers have no way to judge how much the number should be trusted. A credible forecast usually makes its base, upside, and downside cases visible, along with the evidence that would invalidate each.

When Are Short-Term Price Models Still Useful?

Short-term models have real applications. Traders and institutions use them for volatility estimation, market-making, execution timing, momentum detection, reading liquidity conditions, and managing short-duration risk. Research has found measurable short-horizon predictability in some model configurations, so the issue isn't that prediction is impossible. Results depend heavily on horizon, regime, inputs, costs, and design.

Speed of adaptation is what these models do well. Whether that speed translates into an edge is another matter, because transaction costs, slippage, sudden regime changes, false positives, and overfitting can erase apparent gains once real capital is deployed.

Conclusion: Think in Probabilities, Not Crypto Price Targets

Short-term forecasts contend with market forces that often drown out the available signal. Longer-horizon models have more room to incorporate persistent economic, blockchain, liquidity, and valuation information, but they face structural breaks and assumption risk in exchange, so a longer horizon is no guarantee of a better forecast.

For readers, the more productive question is usually not "What will Bitcoin be worth?" but "Which scenarios are plausible, how likely are they, and what would change that view?" In practice, the forecasts worth paying attention to tend to combine these elements: a probability attached to each scenario, a range rather than false precision, and clear assumptions you can check as conditions change. A price target can be part of that picture, as long as it isn't the whole of it.

Top 7 Back-Office Platforms for Scaling Businesses in 2026

Growth exposes weak points in a back office. A spreadsheet that works for a small team becomes harder to control as entities, employees, transactions, contracts, and approvals multiply. Shared drives and disconnected point solutions can also turn into sources of duplicate data, unclear ownership, and slow reporting.

The platforms below address different parts of that problem. DiliTrust focuses on legal and governance operations; NetSuite and SAP cover enterprise finance and operations; Workday and Rippling center on workforce processes; Ramp manages company spend; and monday.com coordinates work across teams. None replaces the others. The ranking shows where each belongs in a scaling back-office stack and where its boundaries are.

Back view of a female software engineer working at a multi-monitor setup in an office.

How We Picked the Platforms

We assessed each platform on the breadth it provides inside its own domain, support for growth across teams or entities, documented integrations, security, and administrative controls. We also considered implementation reality. A platform ranks higher when it solves a defined back-office problem without pretending to be a universal system of record.

DiliTrust leads because legal work often spans contracts, entity records, matters, board materials, email, and shared drives. That does not make it the first purchase for every company. Its position is strongest for organizations with an in-house legal or governance function and rising complexity.

1. DiliTrust Suite

DiliTrust Suite is an integrated legal and governance platform for in-house legal teams, Legal Operations, corporate secretaries, and boards. Its five modules are Contract Management, Entity Management, Matter Management, Board Portal, and Dataroom. Lini, DiliTrust's proprietary AI engine, is embedded across the Suite and supports functions including document summarization, data extraction, minutes generation, and contract risk detection.

The Matter Management module centralizes requests, tasks, deadlines, documents, activities, workload, and matter status. DiliTrust's legal matter management software also connects with its contract and entity modules, reducing the need to maintain related legal information in separate systems. The module supports API-based and configurable integrations, including Microsoft Dynamics 365, Outlook, Gmail, e-signature systems, and major ERPs.

The full Suite is ISO 27001 and ISO 27701 certified and SOC 2 Type II compliant. It offers sovereign and regional hosting options, granular access controls, 24/7 multilingual support, and unlimited training. The Suite is modular, so organizations can deploy a single module instead of all five.

Notable features:

  • Five connected modules for core legal and governance workflows.
  • Proprietary Lini AI embedded across the Suite.
  • Matter tracking, workflow, reporting, and legal-document management.
  • Sovereign hosting options and recognized security certifications.

Best for: companies with an established legal or governance function that need to consolidate contracts, entities, matters, and board processes.

Limitation: DiliTrust is not a general ERP, HRIS, or small-business administration suite. Organizations with limited legal complexity may only need one module, or no dedicated legal platform yet.

2. Oracle NetSuite

Oracle NetSuite is a cloud ERP platform covering financial management, order management, inventory, procurement, CRM, and related operations. NetSuite OneWorld supports multiple subsidiaries, tax jurisdictions, and currencies in one account and can consolidate subsidiary reporting into parent-company financial statements.

That makes it relevant when finance has moved beyond a single legal entity or simple accounting workflow. Its scope is broader than the general ledger because sales orders, purchasing, inventory, and financial records can sit in the same ERP environment. NetSuite also provides SuiteCloud tools for integrations and customization.

Notable features:

  • Multi-subsidiary and multi-currency management through OneWorld.
  • Consolidated reporting across subsidiary structures.
  • Native order, procurement, inventory, and finance capabilities.

Best for: growing companies that need multi-entity financial management alongside operational ERP functions.

Limitation: scope rises with modules, integrations, and customizations. Multi-entity deployments require careful implementation planning and ongoing administration.

3. Workday

Workday combines Human Capital Management with financial, planning, analytics, and workforce-management products. Its HCM suite covers core workforce data, recruiting, talent, compensation, benefits, time, absence, and workforce planning. Workday Global Payroll connects native and third-party payroll arrangements rather than providing identical payroll coverage in every country.

Workday Financial Management includes accounting, accounts payable and receivable, revenue and cash management, close and consolidation, expenses, planning, and reporting. This makes it relevant to organizations that want workforce and financial information in closely connected systems.

Notable features:

  • Broad HCM coverage across the employee lifecycle.
  • Financial management with multicompany and multicurrency support.
  • Workforce planning plus real-time analytics and reporting.

Best for: organizations where workforce management, planning, and service-centric finance are major priorities.

Limitation: payroll coverage varies between native Workday payroll and partner solutions, while manufacturing-heavy operations generally need a different operational ERP layer.

4. SAP S/4HANA Cloud Public Edition

SAP S/4HANA Cloud Public Edition, now positioned as a foundational application of SAP Cloud ERP, covers finance, sourcing and procurement, manufacturing, supply chain, sales, service, and asset management. SAP supplies preconfigured processes and industry content, while the HANA platform supports operational reporting and analytics.

Its breadth suits companies whose back-office requirements extend into physical operations. Manufacturing includes production planning, execution, and quality processes, while supply-chain functions cover inventory, product availability, shipping, warehousing, and transportation.

Notable features:

  • Finance, manufacturing, procurement, and supply-chain processes in one ERP.
  • Preconfigured best-practice content for multiple industries.
  • Central procurement and real-time operational data.

Best for: organizations with complex finance, procurement, manufacturing, or supply-chain processes.

Limitation: broad deployments involve significant implementation and change management. Businesses needing only accounting or a narrow workflow may prefer a more focused system.

5. Ramp

Ramp is a financial operations and spend-management platform covering corporate cards, expenses, accounts payable, procurement, travel, vendor management, and accounting automation. It also supports multi-entity administration, international payments, and global expense workflows.

Ramp is no longer mainly a U.S.-only product. It says its global spend platform is available across more than 190 countries, with local card issuing in 30-plus countries and vendor payments to 185-plus countries. Coverage still differs by product and region.

Notable features:

  • Corporate cards with configurable spending controls.
  • Bill Pay, procurement, reimbursements, and expense workflows.
  • Direct integrations with major accounting and ERP systems.

Best for: finance teams that want tighter control over purchasing, cards, expenses, and accounts payable.

Limitation: certain card, banking, payment, and funding capabilities depend on country, entity, and plan.

6. Rippling

Rippling is a workforce platform connecting HR, payroll, identity and access, device management, and spend products around employee data. Its Global HRIS supports international workforce records, while Global Payroll, Employer of Record, and contractor products extend hiring and pay into multiple markets.

The IT layer separates Rippling from a conventional HRIS. Identity and Access automates app permissions as worker attributes change, while Device Management supports Apple and Windows devices. Its contractor product supports workers in 185-plus countries and 50-plus currencies.

Notable features:

  • HRIS, payroll, onboarding, and workforce workflows in one ecosystem.
  • Identity, application access, and device-management products.
  • Global payroll, EOR, and contractor options.

Best for: companies that want HR processes connected closely with payroll, application access, and device administration.

Limitation: international coverage differs by product. Contractor or HRIS coverage in a country does not mean native payroll, benefits, and every IT feature are available there.

7. monday.com

monday.com is a work-management platform for projects, portfolios, resources, internal requests, and recurring workflows. Teams can configure boards, dashboards, forms, dependencies, integrations, and code-free automations without treating the platform as an ERP or HRIS.

For scaling operations teams, its role is coordination rather than ownership of core financial, employee, or legal records. Enterprise features include portfolio dashboards, resource management, cross-project dependencies, permissions, and administrative controls.

Notable features:

  • Configurable boards, forms, dashboards, and automations.
  • Portfolio and resource-management features.
  • Open API and integrations with common business applications.

Best for: operations and project teams that need visible ownership of cross-functional work.

Limitation: monday.com is a coordination layer, not a replacement for an ERP, HRIS, legal governance platform, or accounting system.

Platform Summary

PlatformPrimary Back-Office RoleStrongest FitMain Consideration
DiliTrust SuiteLegal and governanceEstablished legal teams with growing entity, contract, matter, and board complexityNot a general business administration platform
Oracle NetSuiteERP and financeMulti-entity financial and operational managementImplementation scope rises with complexity
WorkdayHCM and financeWorkforce-intensive and service-centric organizationsPayroll coverage varies by market
SAP S/4HANA CloudEnterprise ERPComplex manufacturing, procurement, and supply chainsBroad deployments require change management
RampSpend managementCards, AP, procurement, and expense controlProduct availability differs by country
RipplingWorkforce operationsHR, payroll, identity, and IT administrationGlobal coverage varies by product
monday.comWork managementCross-functional projects and operational workflowsNot a core system of record

How to Choose the Right Platform

Start with the process creating the most friction, then decide what data needs an authoritative home. Legal teams dealing with matters, entities, contracts, and board work need a different system from finance teams struggling with consolidation or HR teams coordinating payroll and access. Buying overlapping platforms before assigning clear ownership creates another integration problem.

Data control also becomes harder as more applications and users enter the stack. Our guide on how small businesses can scale operations without losing control of customer data makes a useful related point: centralized systems, access controls, and formal governance should grow alongside the business. The same principle applies to financial, employee, and legal data.

Finally, check the exact modules, countries, integrations, security controls, administrative workload, and migration requirements that apply to your organization. A broad marketing claim matters less than the configuration your team will actually deploy.

Build the Back Office Around Trusted Data

Scaling companies do not need one platform to run every back-office process. They need a small number of systems with responsibilities and reliable integration between them. DiliTrust, NetSuite, Workday, SAP, Ramp, Rippling, and monday.com address different operational layers, so the best sequence depends on where complexity is already creating risk or rework.

That becomes more important as AI moves deeper into enterprise software. Deloitte's August 2026 analysis of whether back-office data is ready to drive AI value argues that trusted core data, governance, and architecture become more important as AI is embedded in ERP and surrounding workflows. The same logic applies across the wider stack: automation is only as dependable as the records, permissions, and processes underneath it.

Professional in suit analyzing financial data on screens in a modern office setting.

Choose the platform whose domain matches the real bottleneck, verify the exact deployment rather than the headline feature list, and keep each system responsible for the data it is designed to govern.

Reduce Latency by Optimizing NVMe Clock Frequency for RTDB

Live database synchronization is one of the most challenging engineering problems of current IT architecture. In cases where on-premise CRM synchronization with cloud versions, distributed transactional logs or local application cache synchronization with central databases are involved, the margin of latency is counted in milliseconds. With any delay present, race conditions, merge conflicts, locks and stale data spread become the problem.

With a drop in performance, system administrators automatically tend to install additional memory and raise vCPU quotas. However, live synchronization pipeline does not generally suffer from memory shortages or lack of cores. The physical limits that determine the speed of real-time synchronization are the clock speed of CPU and NVMe storage subsystem performance.

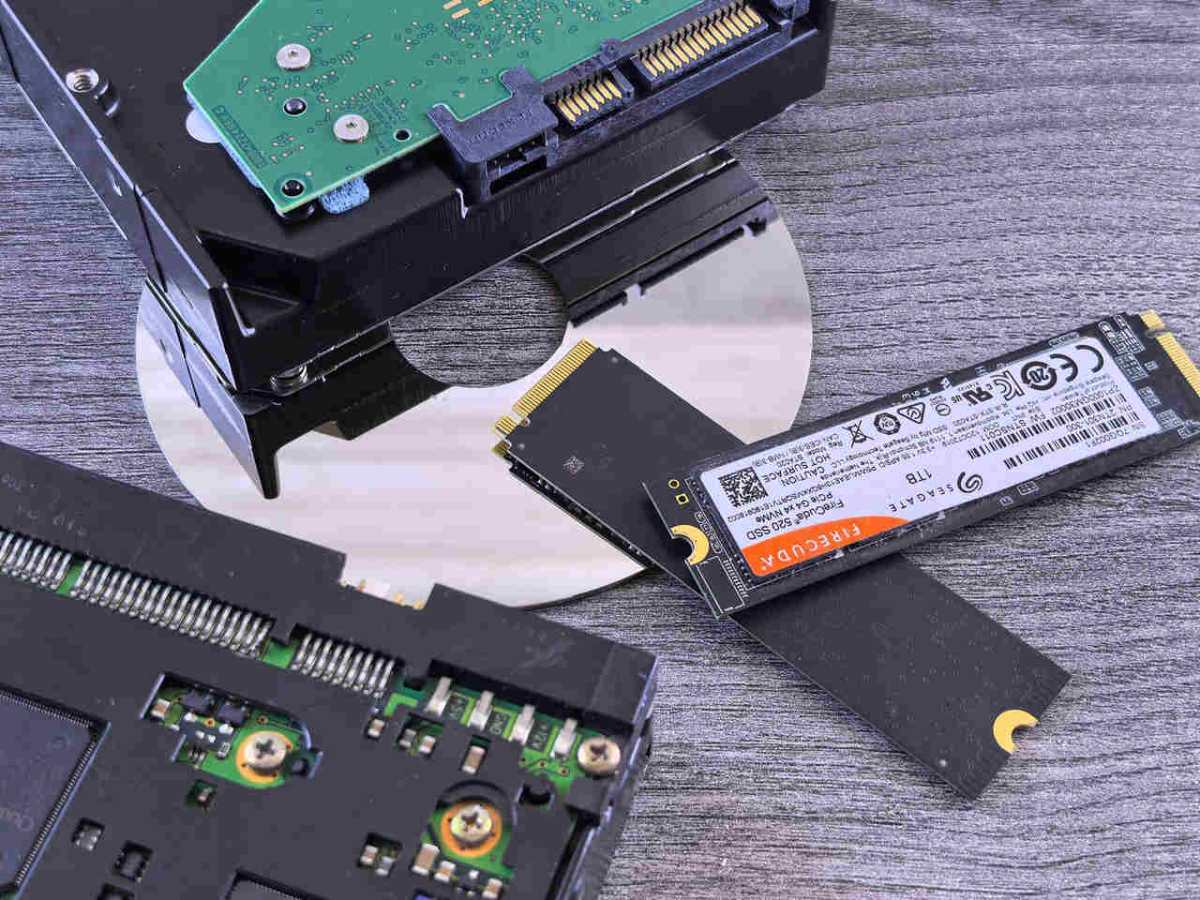
Contrasting data storage technologies: NVMe SSD, HDD, and CD.

Anatomy of a Synchronization Problem

To explore how hardware architecture defines synchronization efficiency, one should think about the process chain of the live two-way synchronization. In case when modification occurs on Node A and then it syncs with Node B, the database engine should perform the following actions:

  • Receiving payload via the network socket.
  • Processing delta and applying the rules of schema.
  • Obtaining appropriate row or table locks.
  • Processing conflict-resolution logic using local timestamps or version vectors.
  • Applying transaction to the Write-Ahead Log (WAL).
  • Committing the transaction to storage and releasing the lock.
  • Returning state message back over the network socket.

Although network transmission defines the base level of latency, the processing throughput defines whether the incoming transactions will be queued or immediately processed. Operations 2, 3, and 4 depend on the single-core CPU performance, while operations 5 and 6 are completely storage-dependent.

Why High-Core Count Doesn’t Work for Single-Threaded Processing

The most frequent mistake in the process of sizing the virtualization is the assumption that all the processing power is equal. Eight cores on a processor with the base clock speed of 2.0 GHz provide nearly identical theoretical aggregate processing power as a four-core processor with the clock speed of 4.0 GHz. Real-time database synchronization will favor the 4.0 GHz variant.

Pipeline PhasePrimary Hardware BottleneckOperational Impact Under Load
Delta IngestionNetwork Bandwidth & LatencySockets buffer incoming packets if downstream compute threads stall.
Logic & Row LocksCPU Clock Speed (GHz / IPC)Single-thread bound. Low clock speeds increase lock-hold duration, stalling other connections.
Journal PersistenceNVMe Latency ($QD \le 4$)Slower fsync() log flushes force the CPU into high %wa idle wait-states.
State CommitNVMe IOPS & BandwidthSaturated disk controllers cause write queues (await > 2ms) and replication drift.

Database engines ensure the replication process in the background in many worker threads. But particular processes involved in transaction processing, i.e., acquiring row locks, latching, and Write-Ahead Log serialization, happen sequentially. One worker thread should acquire a lock and determine the lack of conflicts before increasing the Log Sequence Number (LSN).

If there is not enough CPU clock frequency:

Lock hold time grows

The lower the clock rate, the longer it takes to calculate the algorithm for resolving conflicts. In case thread A holds the row lock for extra 400 microseconds, thread B should wait in an idle spinlock or sleep mode.

Instruction latency grows

High single-core instructions per cycle (IPC) and high clock rates prevent microcode execution time and guarantee that all deltas have been evaluated before buffer saturation.

More Than IOPS, Latency and Bandwidth Matter

As the CPU works on incoming data, storage write speed defines when the commit gets finalized. Conventional mechanical disks and old-school SATA SSDs face challenges in terms of real-time synchronization due to bandwidth/queuing limitations.

There are two types of physical storage requirements involved in database synchronization:

Low Queue Depth for Sequential Writes (WAL Commit)

In order to preserve the ACID principle, particularly the durability requirement, the database engine cannot acknowledge the transaction before flushing it to non-volatile storage using fsync() or fdatasync() function calls. Transactions are committed in series, and thus the disk queue depth is very low (QD = 1 – 4). The high-speed NVMe disk connected through PCI-E channels can provide microsecond write latency times which cannot be achieved by legacy SATA disks.

High Bandwidth Throughput for Bulk State Reconciliation

While live incremental sync depends on latency-reducing micro-writes, bulk seeding, snapshot creation, and disaster recovery reconciliation require massive sequential bandwidth. When dealing with millions of records, transmitting gigabytes of logs through the PCIe Gen 4 or Gen 5 links removes any limitations from the storage controller and ensures that the available network bandwidth is the sole bottleneck.

Using synchronization engines in multi-tenant cloud setups requires assessment of the hardware oversubscription. In case the hypervisor over-subscribes the storage I/O or limits the physical cores usage, write stalls become apparent instantly. Finding an optimal high-performance VPS ensures the isolated CPU clock ticks and unrestricted access to NVMe required to avoid CPU steal and storage queue saturation by the hypervisor.

Detecting Hardware Starvation

Prior to optimizing synchronization code or database parameters, perform diagnostics to determine whether there is any starvation in the hardware layer:

Diagnostic MetricCommand / UtilityHealthy BaselineBottleneck Indicator
I/O Wait Timetop / vmstat 1 (%wa)< 2.0%Persistently > 5.0%
CPU execution threads are stalled in an idle wait-state awaiting storage commit/flush completion.
CPU Steal Timetop (%st)0.0%> 1.0%
The host hypervisor is oversubscribed and starving virtual cores of scheduled clock cycles.
Disk Await Timeiostat -xz 1 (await)< 1.0 ms (NVMe)Spikes > 5.0 ms
The storage controller, PCIe bus, or drive write queues are saturated.
Lock Wait TimeDatabase Engine Stats
(e.g., pg_stat_activity, sys.innodb_lock_waits)
Workload-dependentSpikes during low total CPU usage
Serialization routines and row-level locks are waiting on single-thread execution speed (clock frequency).

Physical Infrastructure Requirements for Real-Time Synchronization

To ensure consistent and timely synchronization of production databases, ensure your server architecture meets these physical infrastructure requirements:

High Single-CPU Turbo is Better Than Many Cores

As far as the replication targets and synchronization points are concerned, hosting the workload on a dedicated High-Performance VPS that utilizes the contemporary CPU micro-architecture will ensure high single-CPU turbo frequencies of 3.5 GHz base with up to 4.5 GHz turbo, instead of going for budget solutions with many threads and lower frequency.

Use NVMe Partitions for Database Journals

Ensure you use a separate partition to store the Write-Ahead Log and the database tree structure. This ensures that you can isolate your journal write processes from general application disk I/O and avoid situations where your synchronous commits get queued up.

Assess Virtualization Overheads

In virtualized environments, confirm that the host guarantees consistent CPU scheduling. Where you find that your synchronization lags are caused by random bursts rather than sustained pressure, it means that CPU steal and storage noisy neighbor are to blame.

Close-up of hands pressing chess clock during an intense board game session.

When you synchronize the reality of real-time synchronization, serialized locking and disk flushes, with fast CPUs and efficient NVMe storage systems, your transaction backlog will be eliminated.

How Trench Drains Support Safer, Cleaner Gas Station Spaces

Taking family road trips or navigating daily city commutes requires frequent pit stops along busy highways and urban avenues. Stepping out onto a wet, oily parking lot can instantly ruin a clean pair of shoes or cause a sudden slip. Fuel stops handle heavy vehicle traffic, unpredictable weather, and chemical drips around the clock. Modern channel systems capture liquid runoff before standard puddles form across active walking paths.

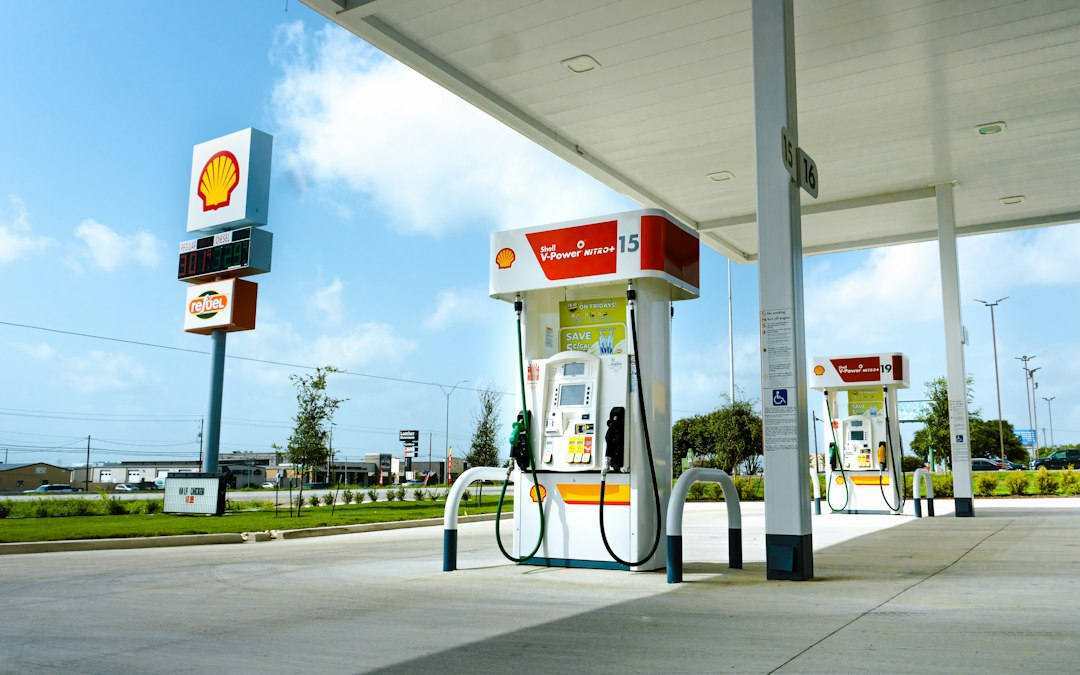
photo-1727483771218-c1cc488d020c

Stopping Slip Hazards Near the Pumps

Rain and spilled fluids quickly transform smooth concrete lots into slick hazards for parents unloading kids from SUV backseats. Upgrading to modern gas station drainage systems channels surface runoff away before footwear loses grip near the island. Clean walking paths give family drivers total peace of mind during late-night fueling stops.

Wet concrete combined with leaked engine fluids creates invisible slick spots around fuel dispensers. High-volume channels draw standing liquid off the pavement surface immediately. Fast water removal protects children wearing fresh sneakers and parents carrying heavy armfuls of road trip snacks.

Slick surfaces near pumps create liability issues for station owners and immediate dangers for busy parents. Channel grates create a dry barrier zone where foot traffic is heaviest. Families move comfortably between pump bays and retail store doors without dodging deep puddles.

Intercepting Runoff Before It Spreads

Water accumulation across active drive lanes creates messy splash zones for arriving motorists and pedestrians. Recent industry design guidelines note that linear surface channels catch liquid before water migrates into high-traffic drive lanes or customer walkways. Placing channels directly across access points forms a continuous barrier against migrating surface fluids.

Uncontrolled water movement spreads oil residues across wide concrete pads. Continuous surface drains trap surface wash before liquids reach high-density foot traffic areas. Keeping water isolated to defined collection channels prevents broad surface contamination across the lot.

Strategic placement near entry aprons stops off-site stormwater from washing across fueling bays. Perimeter channels direct heavy rainwater into storm lines rapidly. Clean lot perimeters reduce splash spray onto recently washed vehicles and family minivans.

Heavy Duty Protection for High Traffic Lanes

Fuel stops experience continuous stress from massive transport vehicles, delivery vans, and oversized rigs. Technical equipment specifications indicate that surface grates must maintain structural integrity against heavy fuel delivery trucks[cite: 1]. Standard residential grates crack under heavy commercial loads, creating dangerous jagged gaps.

Heavy commercial steel and cast grates absorb repeated heavy wheel impacts without bending or shifting. Sturdy grate locking mechanisms keep components firmly anchored in place as large dual-tire vehicles pass overhead. Reliable channel covers prevent deep tire rutting and maintain flat driving surfaces across the station footprint.

Engineered channels withstand constant thermal expansion caused by seasonal climate shifts. Solid surface support keeps heavy vehicle traffic moving safely without disrupting underlying trench channels.

Materials Built for Chemical Resistance

Gasoline, diesel fuel, and automotive solvents quickly degrade standard concrete channels over several years. System manufacturer documentation reveals linear drainage channels built with specialized polymer concrete resist harsh chemical elements present at fueling facilities. Corrosion-resistant channel materials preserve structural strength through decades of continuous fuel exposure.

Non-porous channels prevent petroleum liquids from soaking into underground soil layers or surrounding bases. Smooth internal channels accelerate liquid flow rates toward proper oil-water separation equipment. Long-lasting composite materials lower long-term maintenance costs for commercial property managers.

Resistant resin channels eliminate internal surface pitting that traps foul odors and stagnant runoff. Clean interior walls prevent sludge accumulation during dry summer spells.

Practical Upgrades for Urban Fuel Hubs

Urban gas stations require specialized design choices to keep dense city foot traffic moving smoothly. Modern surface grates offer multiple practical benefits for everyday city drivers:

  • Heel-proof grate slots prevent high heels and narrow shoe treads from catching.
  • ADA-compliant slot widths allow smooth passage for strollers and wheelchairs.
  • Skid-resistant textured top surfaces provide extra foot traction during winter rainstorms.
  • Integrated trash baskets catch fallen leaves and plastic wrappers before underground pipes clog.

Urban parents pushing strollers appreciate flat transition zones across fueling islands and store walkways. Clean channels mean less dirt tracked onto pristine car floor mats after fill-ups.

g08977102bb9b17655ad2828248d1337c87560ae043071923c93f65911837efc4e993b85ee50526df36e0802b91e711ad1c6da8ffdc821f156bbac1739637dccc_1280.jpg

Simple Maintenance for Station Operators

Maintaining clean channel drains requires minimal downtime for station employees during routine shifts. Removable grate panels allow quick cleanout access using standard high-pressure water hoses or shop vacuums. Clear flow paths prevent backed-up water from accumulating during sudden torrential summer downpours.

Routine seasonal inspections keep channel systems clear of road grit, autumn leaves, and winter salt residue. Clean collection points protect local stormwater systems from sudden fuel spill runoff. Station owners maintain safer, cleaner properties and provide a better customer experience for every visiting driver.

Safe fuel stops rely on durable surface management to handle daily commuter traffic. Proper channels collect hazardous liquids before puddles reach active foot traffic zones. Investing in heavy-duty channel drainage creates safer, cleaner spaces for every family on the road.

How Professionals Can Budget for Essential Technology and Productivity Upgrades

As professionals take on new responsibilities, their current tools and setup may no longer be enough to keep up with their workload. An older laptop or outdated software can make everyday tasks more difficult, prompting them to consider new technology or productivity upgrades. However, not everyone has the means to purchase these upgrades right away. This can be especially challenging for freelancers and self-employed workers, whose income may vary from month to month.

Instead of putting off an important upgrade or taking money away from essential expenses, it can help to explore ways to plan and pay for the purchase more strategically. Better budgeting can create room for technology expenses over time, while financing options such as buy-now, pay-later services from trusted providers like Kredivo Philippines may offer another way to manage the cost. The key is to make sure any purchase fits within your overall financial situation and doesn't interfere with your daily needs.

If you're a professional preparing for a new device or productivity upgrade, here are some tips to help you budget for it more efficiently.

African American man in a meeting reviewing a budget document with a microphone

1. Identify Which Upgrades You Actually Need

Before setting money aside or applying for a loan for a new device or productivity tool, determine whether the upgrade is genuinely necessary. Consider which tasks are becoming harder to complete with your current setup and what's causing the problem. A slow laptop, limited storage, or equipment that no longer supports your workload may justify an upgrade, while newer features that don't directly affect your work may not be worth the added expense.

Once you know what you need, prioritize purchases based on how much they can improve your day-to-day work. This can prevent you from spending your budget on upgrades that offer minimal returns or simply because they're newer or more advanced. Having a clear list of priorities also makes it easier to decide which purchases should happen now and which can wait until you have more room in your budget.

2. Set a Dedicated Technology Fund

Creating a separate fund for technology expenses can make future upgrades easier to manage. Rather than dipping into your general savings whenever a device needs replacing, set aside a specific amount for work upgrades regularly. Treat it like any other savings goal, and adjust your contributions based on your income and upcoming financial needs.

Having money reserved for technology also gives you more flexibility when an upgrade becomes necessary. Importantly, you won't have to take as much or at all from your budget for bills, food, transportation, or other daily expenses to cover the purchase. Even without a specific upgrade in mind, building this fund gradually can help you prepare for future technology expenses.

3. Compare the Full Cost Before Buying

The price shown on a product page isn't always the total amount you'll spend. A new laptop, for example, may also require accessories or software subscriptions. Account for these additional expenses when setting your budget so you're less likely to encounter unexpected costs after making the purchase.

It's also worth comparing different models, brands, and alternatives based on what you actually need. A less expensive option may provide everything required for your work, while a premium model could include fancy features you won't actually use. Looking at overall value instead of specifications alone can help you choose an upgrade that meets your professional needs without stretching your budget.

4. Consider Splitting Up Large Payments

Some technology purchases can take a significant portion of your available funds when paid for upfront. If an upgrade is necessary but paying the full amount at once would put pressure on your monthly budget, consider options like buy-now, pay-later services and installment plans that let you spread the cost over several payments. These can make a larger purchase easier to manage by dividing the expense into smaller scheduled payments.

However, spreading out a payment doesn't necessarily reduce the overall cost. Always check the interest, fees, payment schedule, and other terms before choosing an installment or buy-now, pay-later option. Most importantly, make sure the recurring payment fits comfortably within your budget and won't interfere with essential expenses or other financial commitments.

5. Time Your Purchases Carefully

You don't always have to buy an upgrade as soon as you decide you need one. If your current equipment can still handle your workload, giving yourself more time to save can make the eventual purchase easier to manage. Planning ahead also gives you more time to compare options instead of making a rushed decision when your current device eventually needs to be replaced.

Timing can also affect how much you spend. Watch for sales, promotional periods, or opportunities to purchase an older model at a lower price when a newer version is released. The goal isn't necessarily to wait for the absolute lowest price, but to choose a time when the purchase makes the most sense for both your work needs and your budget.

Make Upgrades Work for Your Budget

Essential technology upgrades can be easier to manage when you plan for them instead of letting them disrupt your everyday finances. By taking the tips above into account, investing in tools that support your work doesn't have to come at the expense of your daily needs. With a thoughtful approach to budgeting, you can prepare for the upgrades you need while keeping your finances on solid footing.

Managing Distributed Engineering Teams Across Multiple Time Zones

Managing an engineering team is a job. You have to balance a lot of things. Now add people working from parts of the world in different time zones and with different schedules. It can get really confusing.

Having a team that works from different locations is not just a temporary thing. It is becoming a way for companies to find the right people to keep projects going all the time and build teams in different areas.

If you look at the numbers you can see how common this is. 92% Of teams that work from home are in at least two different time zones. 58% Are in three or more time zones.. About 35% of teams that work from home full time are in five or more time zones. In companies with more than 500 employees teams can be in six or more time zones.

The problem is not about managing people who work from home.

It is about creating a system where every single person on the engineering team knows what they have to do when they have to do it and how to stay in touch with the rest of the engineering team even when they are not online, at the time.

Team members analyzing technical schematics on office workspace. Ideal for business and engineering concepts.

Why Time Zones Change the Way Engineering Teams Work

A distributed team is really different from a team that works in an office.

The people on a distributed team do not all work at the time.

One developer is just starting their day when another developer is finishing up.

A product manager may send a question at 10 AM. The developer who needs to answer the question may not see the question from the product manager until several hours later.

This is because the developer is on a schedule so they do not see the question from the product manager right away.

A distributed team has to deal with this kind of thing all the time, which's why the working rhythm of a distributed team is not the same as the working rhythm of an office-based team.

This creates a simple problem: waiting.

A small delay in one task can become a larger delay when it blocks another team member.At the same time, remote work remains highly attractive to developers. Stack Overflow Developer Survey data shows strong remote participation among hiring mobile app developers, including fully remote rates of roughly 32–45% in key markets such as the US. Overall, 79% of developers prefer either remote or hybrid work.

For businesses, this means the question is no longer whether remote engineering teams can work. The question is how to manage them effectively.

Start With an Async-First Culture

The largest error that businesses can make with eCommerce is to attempt to create an office-like setting online.

That typically results in too many meetings, too many messages sent and everyone expecting repays immediately.For distributed teams, there is a need for another strategy.

An async-first culture allows developers to make progress without waiting for everyone to be available.

The numbers support this approach. Most workers, eighty three percent think that doing things on their own schedule helps them get more work done. Only a small number of workers around ten to eleven percent say it makes them less productive. More than half of the workers around fifty two point eight percent want to be able to work on their schedule more often. Only a small number, 8.3%, want to work on a schedule with their team all the time.

Teams that are in three or more time zones can really benefit from this. Data from GitLab shows that when teams work on their schedule they can finish projects around twenty three percent faster. This is especially helpful, for teams that are spread out across different time zones.

What should be asynchronous?

Use written communication for information that does not require an immediate discussion.

  • Project updates
  • Technical decisions
  • Documentation
  • Code review comments
  • Task requirements
  • Meeting notes
  • Progress reports
  • Questions that can wait

The goal is simple: make information available when people need it, not only when everyone is online.

Define Clear Overlap Hours

Async communication does not mean we have to stop talking to each other in time. Some things are just easier to talk about when people can have a conversation.

The thing to do is make a window of time when everyone is available no matter where they are in the world.

For example a team might say that everyone has to be available for two hours every day.

During that time the team can have meetings to talk about the work they are doing make decisions about things, solve problems and have important conversations with the clients.

The rest of the day people can work at their schedule.

This way the developers can focus on their work without people interrupting them.

The developers can still talk to each other when they need to talk about something.

Async communication is still used. The team also has time to collaborate.

Keep Meetings for Decisions

A meeting should have a reason to exist. If information can be shared through a project management platform or written update, there may be no need for another video call.

Use meetings when the team needs to:

  • Make an important decision
  • Resolve a complex technical issue
  • Brainstorm
  • Discuss blockers
  • Align on priorities
  • Handle sensitive conversations

This can dramatically reduce meeting fatigue across distributed teams.

Make Documentation Part of the Engineering Process

Documentation is really important when team members are far apart.

Imagine this situation: a developer in Mexico is finishing up a feature. The technical lead in the US is not available. The technical lead in the US is offline so the developer in India has to wait. Without documentation the developer in India may have to wait until the next day to get the clarification they need from the technical lead, in the US about the feature.

With good documentation, work can continue. Create a single source of truth for:

  • Architecture decisions
  • Coding standards
  • API documentation
  • Deployment processes
  • Product requirements
  • Technical dependencies
  • Troubleshooting guides
  • Team responsibilities

Good documentation is not administrative overhead. It is a productivity tool for distributed teams.

Create Clear Ownership

Time zones can make accountability confusing. If three developers are involved in a feature, who owns the final decision?

If a production issue happens outside someone’s working hours, who handles it? Distributed teams need clearly defined ownership.

Every major task should have an owner. Every important system should have someone responsible for it. And every escalation path should be documented. This removes unnecessary back-and-forth. It also prevents the common situation where everyone assumes someone else is handling the problem.

Build a Follow-the-Sun Workflow Carefully

It's good to work across time zones. A job may carry on from one place to another when workers leave their work for the day. For example a programmer in Asia might finish a part of a project. Write clear instructions for someone in Europe. The European developer continues the work and passes it to someone in North America.In theory, development can continue for much of the day. But this only works when handoffs are structured.

Every handoff should answer three questions.

What was completed?

Clearly explain what has already been done.

What is still pending?

Mention unfinished work, known issues, or decisions that are still required.

What should happen next?

Give the next developer enough context to continue without another meeting. A poor handoff creates waiting. A good handoff creates momentum.

Use the Right Tools, But Keep Them Simple

A distributed engineering team does not need dozens of platforms. It needs a clear system. A typical setup might include:

  • Project management: Tasks, priorities, deadlines, and ownership.
  • Communication: Quick conversations and team announcements.
  • Documentation: Architecture, requirements, processes, and decisions.
  • Code collaboration: Source control, pull requests, reviews, and technical discussions.
  • Monitoring: Application health, incidents, logs, and alerts.

The important thing is not the number of tools.It is knowing where information belongs. When developers have to search through chat messages, emails, documents, and multiple dashboards to find one decision, productivity suffers.

Be Careful With Time Zone Inequality

Not every time zone should become a disadvantage. If every important meeting is scheduled around one region, the same employees may always have to attend calls early in the morning or late at night.

That eventually affects morale.

Rotate inconvenient meeting times when possible. Record important sessions. Share written summaries. Avoid making attendance at every live meeting a measure of commitment.

Remote work should provide flexibility, not simply move office hours into someone’s personal time.

Measure Outcomes, Not Online Presence

This is one of the most important rules for distributed engineering management.

A developer who is online for ten hours is not necessarily more productive than someone who works focused for seven. Measure outcomes instead.

Look at:

  • Delivery against agreed priorities
  • Code quality
  • Reliability
  • Review turnaround
  • Incident response
  • Product impact
  • Progress against milestones
  • Collaboration

Avoid judging developers by green status indicators, response speed, or how often they appear online. The goal is to build software successfully, not to create a digital attendance system.

Leadership Is Often the Missing Piece

Technology can connect distributed teams. It cannot solve poor leadership.

Only around 42% of employees at large organizations rate their distributed-work leaders as more than “somewhat” effective. That highlights a major challenge for companies moving toward distributed work.

Leaders need to make things clear for everyone.

They have to tell people what they expect from them when it comes to talking to each other, who's in charge of what time they have to work, how they make decisions, how they keep track of things and what to do when there is a problem.

Leaders also need to trust the people who work for them.

When leaders do not give their teams the freedom to do their work it can cause a lot of problems especially when the teams are not in the place and do not work at the same time. Leaders need to trust their teams and leaders need to create clarity for their teams.

When Hiring a Distributed Engineering Team Makes Sense

For companies, creating a team that works from different places is also a way to get expert engineering skills without only hiring people from one city or one country.

If you need engineering help a remote team model can give you access to developers who act like part of your own team.

Businesses that want to create or grow a team that works from locations can think about hiring dedicated remote developers when they need skilled workers without setting up a whole new system for hiring inside the company.

The key thing is to see developers as part of the engineering group not as a separate outside group.

They need to have access to documents, the same processes, the same ways to talk with each other and the same understanding of the product, as the rest of the team.

The Goal Is Not to Remove Time Zones

Time zones are not necessarily the problem. Poor coordination is.

With a properly managed distributed engineering team, different time zones can be a good thing. Projects can span multiple areas, developers have more uninterrupted time to dedicate to their projects, and companies can hire from a broader talent pool.

The foundation is straightforward:

  • Make communication async by default.
  • Keep a small window for real-time collaboration.
  • Document decisions.
  • Assign clear ownership.
  • Structure handoffs.
  • Respect local working hours.
  • Measure outcomes instead of online activity.
  • Give distributed leaders clear management practices.

Conclusion

Managing engineering teams that are in parts of the world is not easy. You need to do more than just have video calls and use tools that help people work together. You need to work in a different way.Companies that do things like send messages that do not need a response, make sure someone is in charge of each task, write down important information plans for when someone is not working and have some hours when everyone is working at the same time can actually benefit from being far apart.

The engineering teams get time to focus on their work and the companies can hire people from all over the world.The goal is not to make everyone work at the time. The goal is to make sure the engineering teams can keep working even when everyone's not online at the same time.

With the way of doing things and good leaders, engineering teams that are in different parts of the world can be a good way for companies to grow over a long period of time.


────────────────────────────────────────────────────────────

Two businessmen in an office with clocks showing different time zones, symbolizing global business.

AI Impression Rate

Why Your Marketing Pipeline Feels Broken and How Small Businesses Fix It

You ran the ad, the phone rang, and then… nothing. No booking, no follow-up, no sale. If that sequence sounds familiar, you are not dealing with a lead generation problem. You are dealing with a pipeline problem, and it is quietly costing you more than you think.

Let me show you what is actually happening between the moment a customer finds you and the moment they hand over money. Then I will walk you through the exact fixes that work for service businesses, retail shops, and consultants alike. None of this requires a fancy CRM or a marketing degree. It requires knowing where the leak is.

Where Most Businesses Lose Customers First

The biggest myth in small business marketing is that more leads equal more revenue. It does not. More leads equal more chances to lose people if your follow-up is slow.

Here is a number that should bother you: the U.S. Census Bureau reported in 2022 that about 4.4 million businesses were started that year, and the ones that grow are almost never the ones with the most advertising. They are the ones that answer fast. Speed is the cheapest marketing tool you own, and almost nobody uses it well.

Think about your own behavior. When your water heater dies, do you wait around for a callback? No. You call the next plumber on the list. Your customers behave exactly the same way, whether they are buying HVAC repair, booking a photographer, or ordering custom furniture.

The fix here is boring but brutal: set up instant acknowledgment. A text message autoresponder, an email confirmation, anything that tells the customer you heard them within five minutes. You can hire a service for this, or you can simply assign someone to watch the inbox during business hours. It is not glamorous. It works.

The Middle Stage Nobody Talks About

Here is where things get weird. Most business owners think the sale happens at the moment of purchase. It does not. It happens in the space between “I am interested” and “I am ready to buy,” and that space is full of doubt.

Your prospect is wondering if you are too expensive, if you will show up on time, if the quality will match the photos on your site. They will never tell you this. They will just ghost you.

The Bureau of Labor Statistics tracks how service businesses spend their marketing budgets, and the 2021 data shows most of that money goes to customer acquisition, not retention. Which is backwards, honestly. The customers you already have are the cheapest ones to win back, and they are the ones most likely to refer you to someone else.

So what do you do in that middle stage? You build proof. Send a follow-up email with a case study. Post a video of a recent job. Offer a free consultation call that has zero pressure attached. The goal is not to sell. The goal is to make the customer feel like choosing you is the safe choice.

I would personally skip the discount here. Discounts train customers to wait for the next discount. Instead, add value. A maintenance checklist, a quick tip, a genuine question about their project. That is what moves people forward.

When the Funnel Gets Stuck After the Sale

Most marketing advice stops at the sale, which is a shame, because the sale is where your real revenue starts. Repeat customers cost less to serve, they refer more, and they are less price sensitive. But you only get that if you actually ask for the next job.

Here is a concrete scenario. You finish a roofing job in June. The customer is thrilled. They tell you to call them if they need anything. You leave, feeling great. And then you never call. Nine months later, they have a leak, and they call someone else because your name is not in front of them.

That is a self-inflicted wound. And it is fixable with a calendar reminder, not a marketing campaign. Set a note to reach out in eight months. Send a seasonal check-in. A simple “thinking of you, hope the roof held up through the winter” text costs nothing and keeps you top of mind.

You can build an entire repeat business engine around this one habit. And if you want a structured way to think about all these stages, from first contact to repeat booking, the Home Services Marketing Funnel framework breaks down each phase with specific tactics for improvement. It is written for contractors but applies to any business with a local customer base.

Tracking What Actually Matters

Here is the uncomfortable truth: most small business owners have no idea which of their marketing efforts actually produce jobs. They know they spent money on Google ads, and they know they got some calls, but they cannot tell you which keyword produced which appointment.

That ignorance is expensive. Without tracking, you will keep pouring money into what feels right instead of what works. You do not need a complicated dashboard. You need one thing: a way to know where each customer came from.

Ask every caller how they found you. Put it on your intake form. Use separate phone numbers for different campaigns. This is not sophisticated. It is just honest data collection, and it will immediately show you which channels deserve more budget and which ones are burning cash.

Entrepreneur magazine published a piece in 2022 on customer acquisition costs across industries, and the takeaway was simple: businesses that track their sources closely spend less per customer over time because they stop wasting money on what does not convert. That is the whole game.

Five Steps You Can Implement This Week

You do not need a complete overhaul. You need five small fixes, done consistently, starting now.

  • Set up an instant response system. Text autoresponder, email template, or a live human refreshing the inbox. Speed beats polish every time.
  • Create one piece of proof you can send to hesitant prospects. A one page case study, a photo gallery, a short video walkthrough. One asset, ready to go.
  • Schedule follow-up touchpoints with past customers. Put reminders in your calendar for 6 to 9 months after each job. Keep it personal, not salesy.
  • Ask every new customer how they found you. Record the answer. Review it monthly and shift budget toward what works.

That is it. Four actions, none of them expensive, all of them within reach of a solo operator or a small team. The fifth step is the hardest one: actually doing them consistently. Marketing is not a one time effort. It is a rhythm.

Why Most Advice Misses the Point

Most marketing content tells you to be more visible, run better ads, optimize your website. All of that matters, sure. But visibility only helps if the rest of your pipeline can handle the traffic. A great ad that sends people to a phone that rings unanswered is a waste of money.

The businesses that win are the ones that treat the whole journey as one system, not a series of disconnected events. They answer fast, they build trust, they follow up, and they track the results. It sounds simple because it is. Simple does not mean easy. It means there is no hiding place.

And here is the thing I keep coming back to: most of your competitors are not doing any of this. They run an ad, wait for the phone to ring, and blame the market when it does not. That is your opportunity. You do not need to outspend them. You just need to out execute them on the basics.

Start with one change this week. Pick the stage where you lose the most customers and fix that one thing. Then move to the next. Six months from now, you will look back and wonder why you did not do this sooner. So what is the one stage you know is leaking? And what are you going to do about it tomorrow morning?

Why Virtual Workspaces Improve Technology Accessibility Across Different Geographic Locations

A designer in New York opens the same project that a developer in another country was editing ten minutes earlier. One is on a powerful workstation, the other on an older laptop, yet both need the same applications, files and speed to keep work moving.

That is where traditional workstation thinking starts to break down. When important tools live only on individual devices, geography becomes an IT problem. Virtual workspaces change that by keeping the working environment centralized while approved users reach it remotely.

The virtual workspaces benefits go beyond convenience. You get more consistent access to technology, simpler collaboration, easier management and greater flexibility when your team is spread across offices, homes, cities or countries.

So, let us study it in detail by reading the guide given below:

A man in an office environment using a virtual reality headset, engaging with VR content.

Geography Gets Expensive When the Computer Travels With the Employee

The more locations your team works from, the harder it becomes to keep every device equally capable. One office may use newer systems while another relies on older hardware and different software. That creates duplicated work. Instead of managing one environment, your IT team maintains several versions of the same workspace.

Virtual workspaces reduce that problem. Employees still need a device and stable internet, but important computing happens centrally rather than on each machine.

The Real Upgrade Is Separating the Workspace From the Device

Your laptop becomes the access point, not the place where every application and file has to live. Think of it as a window into the workspace rather than the workspace itself.

A virtual environment can hold:

  • Business software and internal tools
  • Files, configurations and user settings
  • Processing power and storage resources
  • Access permissions for different team members

It gives people a consistent setup across different devices and can simplify onboarding by avoiding a full workstation rebuild for every employee.

Accessibility Is Really About Making Location Less Important

Virtual workspaces reduce how much physical location controls what technology you can use. You may be working from a main office, home, another city or an international branch. If the workspace is centralized, you can reach the same applications and files without carrying the same physical computer everywhere.

That is especially useful for distributed teams that need one dependable setup across several locations. If you want to understand the remote-access side more closely, this guide explains how Windows RDP supports secure remote access and why the connection setup matters when accessing a remote workspace.

Access From Anywhere Means Little If the Environment Goes Offline

Remote access only helps when the systems behind it remain available. If your team depends on one workspace, you need a plan for hardware failure or service interruption.

A practical continuity plan should answer:

  • Where are backups stored?
  • How quickly can systems be restored?
  • Who handles recovery?
  • Can employees regain access another way?

You do not need an oversized recovery setup. You need to know how important it is for systems to return online before an outage happens.

The goal is continuity, so one infrastructure failure does not cut off your team.

Centralizing the Workspace Can Simplify Control

A virtual workspace gives your IT team one main environment to manage instead of relying on many separately configured devices. User permissions, updates, settings and access rules become easier to manage consistently. Employees still need strong passwords, trusted devices and safe login habits.

If someone leaves, you can remove workspace access without wondering what business files remain on a local machine. This centralized control is one of the practical virtual workspaces benefits for businesses managing people across several locations.

The Server Location Still Shapes the Experience

Virtual workspaces make employee location less restrictive, but the quality of the remote environment still matters. Your team needs enough processing power, memory, storage and network capacity to keep applications responsive. The operating system and level of administrative access should also fit the work being performed.

For businesses that need a Windows-based remote environment without building a separate physical workstation for every user, a cheap Windows RDP can provide another practical way to access applications and files remotely. The important part is matching the resources to your actual workload rather than choosing on price alone.

Virtual Does Not Mean Geography Disappears Completely

A virtual workspace cannot fix poor local internet, undersized servers, long network routes or weak security. Those issues can still affect remote work.

Geography still matters. The advantage is that it no longer decides which employee gets access to capable technology.

Technology Should Follow the Worker, Not the Other Way Around

Virtual workspaces improve technology accessibility because they separate the tools you need from the physical machine in front of you. Teams in different locations can reach a more consistent environment without every office or employee needing identical hardware.

The strongest virtual workspaces benefits appear when that accessibility is backed by reliable resources, secure access, responsive connectivity and an environment designed around the work your team actually performs.

The smartest approach is not simply moving everything online. It is centralizing the workloads that benefit from shared access and supporting them with infrastructure that matches where your people actually work.

A modern workspace featuring a laptop, books, and ambient lighting for a productive environment.

If you are building a reliable US-based virtual workspace, explore DashRDP’s dedicated server options and buy RDP online based on the resources you need for your real workload.