Live database synchronization is one of the most challenging engineering problems of current IT architecture. In cases where on-premise CRM synchronization with cloud versions, distributed transactional logs or local application cache synchronization with central databases are involved, the margin of latency is counted in milliseconds. With any delay present, race conditions, merge conflicts, locks and stale data spread become the problem.
With a drop in performance, system administrators automatically tend to install additional memory and raise vCPU quotas. However, live synchronization pipeline does not generally suffer from memory shortages or lack of cores. The physical limits that determine the speed of real-time synchronization are the clock speed of CPU and NVMe storage subsystem performance.
Anatomy of a Synchronization Problem
To explore how hardware architecture defines synchronization efficiency, one should think about the process chain of the live two-way synchronization. In case when modification occurs on Node A and then it syncs with Node B, the database engine should perform the following actions:
Receiving payload via the network socket.
Processing delta and applying the rules of schema.
Obtaining appropriate row or table locks.
Processing conflict-resolution logic using local timestamps or version vectors.
Applying transaction to the Write-Ahead Log (WAL).
Committing the transaction to storage and releasing the lock.
Returning state message back over the network socket.
Although network transmission defines the base level of latency, the processing throughput defines whether the incoming transactions will be queued or immediately processed. Operations 2, 3, and 4 depend on the single-core CPU performance, while operations 5 and 6 are completely storage-dependent.
Why High-Core Count Doesn’t Work for Single-Threaded Processing
The most frequent mistake in the process of sizing the virtualization is the assumption that all the processing power is equal. Eight cores on a processor with the base clock speed of 2.0 GHz provide nearly identical theoretical aggregate processing power as a four-core processor with the clock speed of 4.0 GHz. Real-time database synchronization will favor the 4.0 GHz variant.
Pipeline Phase
Primary Hardware Bottleneck
Operational Impact Under Load
Delta Ingestion
Network Bandwidth & Latency
Sockets buffer incoming packets if downstream compute threads stall.
Slower fsync() log flushes force the CPU into high %wa idle wait-states.
State Commit
NVMe IOPS & Bandwidth
Saturated disk controllers cause write queues (await > 2ms) and replication drift.
Database engines ensure the replication process in the background in many worker threads. But particular processes involved in transaction processing, i.e., acquiring row locks, latching, and Write-Ahead Log serialization, happen sequentially. One worker thread should acquire a lock and determine the lack of conflicts before increasing the Log Sequence Number (LSN).
If there is not enough CPU clock frequency:
Lock hold time grows
The lower the clock rate, the longer it takes to calculate the algorithm for resolving conflicts. In case thread A holds the row lock for extra 400 microseconds, thread B should wait in an idle spinlock or sleep mode.
Instruction latency grows
High single-core instructions per cycle (IPC) and high clock rates prevent microcode execution time and guarantee that all deltas have been evaluated before buffer saturation.
More Than IOPS, Latency and Bandwidth Matter
As the CPU works on incoming data, storage write speed defines when the commit gets finalized. Conventional mechanical disks and old-school SATA SSDs face challenges in terms of real-time synchronization due to bandwidth/queuing limitations.
There are two types of physical storage requirements involved in database synchronization:
Low Queue Depth for Sequential Writes (WAL Commit)
In order to preserve the ACID principle, particularly the durability requirement, the database engine cannot acknowledge the transaction before flushing it to non-volatile storage using fsync() or fdatasync() function calls. Transactions are committed in series, and thus the disk queue depth is very low (QD = 1 – 4). The high-speed NVMe disk connected through PCI-E channels can provide microsecond write latency times which cannot be achieved by legacy SATA disks.
High Bandwidth Throughput for Bulk State Reconciliation
While live incremental sync depends on latency-reducing micro-writes, bulk seeding, snapshot creation, and disaster recovery reconciliation require massive sequential bandwidth. When dealing with millions of records, transmitting gigabytes of logs through the PCIe Gen 4 or Gen 5 links removes any limitations from the storage controller and ensures that the available network bandwidth is the sole bottleneck.
Using synchronization engines in multi-tenant cloud setups requires assessment of the hardware oversubscription. In case the hypervisor over-subscribes the storage I/O or limits the physical cores usage, write stalls become apparent instantly. Finding an optimal high-performance VPS ensures the isolated CPU clock ticks and unrestricted access to NVMe required to avoid CPU steal and storage queue saturation by the hypervisor.
Detecting Hardware Starvation
Prior to optimizing synchronization code or database parameters, perform diagnostics to determine whether there is any starvation in the hardware layer:
Diagnostic Metric
Command / Utility
Healthy Baseline
Bottleneck Indicator
I/O Wait Time
top / vmstat 1 (%wa)
< 2.0%
Persistently > 5.0% CPU execution threads are stalled in an idle wait-state awaiting storage commit/flush completion.
CPU Steal Time
top (%st)
0.0%
> 1.0% The host hypervisor is oversubscribed and starving virtual cores of scheduled clock cycles.
Disk Await Time
iostat -xz 1 (await)
< 1.0 ms (NVMe)
Spikes > 5.0 ms The storage controller, PCIe bus, or drive write queues are saturated.
Spikes during low total CPU usage Serialization routines and row-level locks are waiting on single-thread execution speed (clock frequency).
Physical Infrastructure Requirements for Real-Time Synchronization
To ensure consistent and timely synchronization of production databases, ensure your server architecture meets these physical infrastructure requirements:
High Single-CPU Turbo is Better Than Many Cores
As far as the replication targets and synchronization points are concerned, hosting the workload on a dedicated High-Performance VPS that utilizes the contemporary CPU micro-architecture will ensure high single-CPU turbo frequencies of 3.5 GHz base with up to 4.5 GHz turbo, instead of going for budget solutions with many threads and lower frequency.
Use NVMe Partitions for Database Journals
Ensure you use a separate partition to store the Write-Ahead Log and the database tree structure. This ensures that you can isolate your journal write processes from general application disk I/O and avoid situations where your synchronous commits get queued up.
Assess Virtualization Overheads
In virtualized environments, confirm that the host guarantees consistent CPU scheduling. Where you find that your synchronization lags are caused by random bursts rather than sustained pressure, it means that CPU steal and storage noisy neighbor are to blame.
When you synchronize the reality of real-time synchronization, serialized locking and disk flushes, with fast CPUs and efficient NVMe storage systems, your transaction backlog will be eliminated.
Reduce Latency by Optimizing NVMe Clock Frequency for RTDB was last modified: September 15th, 2026 by Oliver Jonson
A designer in New York opens the same project that a developer in another country was editing ten minutes earlier. One is on a powerful workstation, the other on an older laptop, yet both need the same applications, files and speed to keep work moving.
That is where traditional workstation thinking starts to break down. When important tools live only on individual devices, geography becomes an IT problem. Virtual workspaces change that by keeping the working environment centralized while approved users reach it remotely.
The virtual workspaces benefits go beyond convenience. You get more consistent access to technology, simpler collaboration, easier management and greater flexibility when your team is spread across offices, homes, cities or countries.
So, let us study it in detail by reading the guide given below:
Geography Gets Expensive When the Computer Travels With the Employee
The more locations your team works from, the harder it becomes to keep every device equally capable. One office may use newer systems while another relies on older hardware and different software. That creates duplicated work. Instead of managing one environment, your IT team maintains several versions of the same workspace.
Virtual workspaces reduce that problem. Employees still need a device and stable internet, but important computing happens centrally rather than on each machine.
The Real Upgrade Is Separating the Workspace From the Device
Your laptop becomes the access point, not the place where every application and file has to live. Think of it as a window into the workspace rather than the workspace itself.
A virtual environment can hold:
Business software and internal tools
Files, configurations and user settings
Processing power and storage resources
Access permissions for different team members
It gives people a consistent setup across different devices and can simplify onboarding by avoiding a full workstation rebuild for every employee.
Accessibility Is Really About Making Location Less Important
Virtual workspaces reduce how much physical location controls what technology you can use. You may be working from a main office, home, another city or an international branch. If the workspace is centralized, you can reach the same applications and files without carrying the same physical computer everywhere.
That is especially useful for distributed teams that need one dependable setup across several locations. If you want to understand the remote-access side more closely, this guide explains how Windows RDP supports secure remote access and why the connection setup matters when accessing a remote workspace.
Access From Anywhere Means Little If the Environment Goes Offline
Remote access only helps when the systems behind it remain available. If your team depends on one workspace, you need a plan for hardware failure or service interruption.
A practical continuity plan should answer:
Where are backups stored?
How quickly can systems be restored?
Who handles recovery?
Can employees regain access another way?
You do not need an oversized recovery setup. You need to know how important it is for systems to return online before an outage happens.
The goal is continuity, so one infrastructure failure does not cut off your team.
Centralizing the Workspace Can Simplify Control
A virtual workspace gives your IT team one main environment to manage instead of relying on many separately configured devices. User permissions, updates, settings and access rules become easier to manage consistently. Employees still need strong passwords, trusted devices and safe login habits.
If someone leaves, you can remove workspace access without wondering what business files remain on a local machine. This centralized control is one of the practical virtual workspaces benefits for businesses managing people across several locations.
The Server Location Still Shapes the Experience
Virtual workspaces make employee location less restrictive, but the quality of the remote environment still matters. Your team needs enough processing power, memory, storage and network capacity to keep applications responsive. The operating system and level of administrative access should also fit the work being performed.
For businesses that need a Windows-based remote environment without building a separate physical workstation for every user, a cheap Windows RDP can provide another practical way to access applications and files remotely. The important part is matching the resources to your actual workload rather than choosing on price alone.
Virtual Does Not Mean Geography Disappears Completely
A virtual workspace cannot fix poor local internet, undersized servers, long network routes or weak security. Those issues can still affect remote work.
Geography still matters. The advantage is that it no longer decides which employee gets access to capable technology.
Technology Should Follow the Worker, Not the Other Way Around
Virtual workspaces improve technology accessibility because they separate the tools you need from the physical machine in front of you. Teams in different locations can reach a more consistent environment without every office or employee needing identical hardware.
The strongest virtual workspaces benefits appear when that accessibility is backed by reliable resources, secure access, responsive connectivity and an environment designed around the work your team actually performs.
The smartest approach is not simply moving everything online. It is centralizing the workloads that benefit from shared access and supporting them with infrastructure that matches where your people actually work.
If you are building a reliable US-based virtual workspace, explore DashRDP’s dedicated server options and buy RDP online based on the resources you need for your real workload.
Why Virtual Workspaces Improve Technology Accessibility Across Different Geographic Locations was last modified: September 15th, 2026 by Nancy Brown
When two companies merge or one acquires another, IT rarely gets a slow, careful timeline. Exchange environments need to be consolidated fast often across different Active Directory forests, mismatched Exchange versions, or entirely separate Microsoft 365 tenants while the business keeps running. Here's what makes these migrations different, and how to approach one without losing data or missing your deadline.
Why M&A Migrations Are Different
A standard Exchange migration moves mailboxes from one environment to another in a fairly linear way. A merger or acquisition adds several layers of complexity on top of that:
Two separate identity systems. You're usually reconciling two Active Directory forests, or two independent Microsoft 365 tenants not just moving mailboxes within one environment.
Compressed timelines. Migration schedules are often set by legal or deal terms, not by what's technically comfortable for IT.
Naming conflicts. Duplicate domains, overlapping user principal names (UPNs), and mailboxes with identical or near-identical display names are common when two organizations combine.
Immediate compliance obligations. Legal holds, data retention policies, and regulatory requirements frequently need to apply from day one post-close, not after migration wraps up.
These four factors are what separate an M&A migration from a routine one, and they're also why generic migration playbooks tend to fall short most weren't written with two colliding identity systems in mind.
Common Scenarios
Full absorption. The acquiring company's Exchange environment absorbs the target company's mailboxes, users, and data entirely. This is the most common pattern and usually the most straightforward, since there's a clear "source" and "destination" from the outset.
Tenant-to-tenant consolidation. Both companies already run Microsoft 365 and keep separate tenants for a transition period, then consolidate into one tenant once other integration work branding, licensing, security policy alignment is complete. This scenario is becoming more common simply because more organizations are cloud-first before a deal even happens.
Divestiture (the reverse case). A company splits into two, and one Exchange environment needs to be separated into two independent ones the mirror image of a merger migration, but with the same underlying complexity around identity, permissions, and data ownership.
The Core Challenge: Mailbox Mapping and Conflicts
Before transferring any data, both source and target should be inventoried, namely, mailboxes, Exchange versions, Active Directory forest/domain architecture, and any public folders or shared mailboxes at both sites. The following step, where M&A migrations fail in most cases, involves solving the problem of naming collisions and mapping the mailboxes correctly.
Duplicate UPNs or display names are common when two companies combine; a "J. Smith" on one side and another on the other, or overlapping domain naming conventions. Sorting this out with a spreadsheet and manual entry works for a handful of mailboxes, but it doesn't scale to hundreds or thousands, and errors here mean data lands in the wrong mailbox; a mistake that's far more consequential in an M&A context, where legal and compliance teams are often watching the process closely.
Manual PowerShell Migration vs. a Dedicated Tool
Native tools and PowerShell scripting can technically handle cross-forest migrations, but they weren't built with M&A-specific problems like resolving duplicate identities across two AD forests as a primary use case. Each script needs to be written and tested against the specific environment, which eats into a timeline that deal terms have already compressed.
This is where a dedicated Exchange migration tool becomes worth evaluating as an alternative. Stellar Migrator for Exchange, for example, is built specifically to handle cross-forest and cross-domain migrations without requiring custom scripts. Here's how the two approaches compare on the factors that matter most in an M&A timeline:
Factor
Manual / PowerShell
Stellar Migrator for Exchange
Cross-forest / cross-domain support
Requires custom scripting and testing
Built-in, automated
Mailbox matching after merger
Manual mapping, error-prone with duplicate names
Auto-match by name, or CSV import for bulk mapping
Downtime
Often requires cutover windows
Zero-downtime supported
Handling failed or partial migrations
Manual retry, risk of duplicating already-migrated data
Re-runs only failed or incomplete items
Timeline under deal pressure
Slow — heavy on script writing and testing
Faster to deploy, no scripting required
Migration types supported
Depends on scripts written
Cutover, staged, and hybrid, plus cross-domain
Direction flexibility
Custom-built per scenario
Handles on-prem-to-cloud, tenant-to-tenant, and reverse migrations
While the manual process is not entirely unattainable, many IT departments have performed cross-forest migrations using only built-in utilities before. However, it is unlikely that the M&A process will allow for the development and testing of custom PowerShell scripts based on the specifics of the new environment. The special tool automates the mailbox matching process by comparing names or allows loading the CSV file for assigning mailboxes, taking into account that in M&A situations everything does not always work smoothly on the first attempt and therefore only those mailboxes or items which were not processed during the initial migration cycle need to be retried.
All of this doesn't replace the need for initial planning, such as environment inventory and name conflict resolution, which must be done before scripting can proceed, but it eliminates the bottleneck involved in manually performing these steps.
Step-by-Step: Migrating Exchange Post-Acquisition
Inventory both environments. Document mailbox counts, Exchange versions, AD forest/domain structure, and any public folders or shared mailboxes on both sides. This step alone often surfaces the naming conflicts and version mismatches that will shape everything downstream.
Resolve naming conflicts and build the mailbox mapping. Identify duplicate UPNs or display names before migration starts, and build an explicit source-to-target mapping a CSV-based mapping keeps this accurate at scale and gives you an auditable record, which matters if compliance teams need to sign off.
Choose the right migration path. If both organizations are on-premises, this is typically a cross-forest, same-tenant migration. If both are already on Microsoft 365, this becomes a cross tenant migration instead. Getting this decision right early avoids rework later.
Migrate in batches with incremental sync. Relocate mailboxes in chunks that can be managed effectively instead of doing them all at once. Delta synchronization ensures that mailboxes remain synchronized with incoming mails until the last phase of migration. This way, the impact on users is reduced significantly.
Validate and decommission. Confirm mailbox data, folder structures, and permissions transferred correctly, then retire the redundant environment. This is also the point to close out any temporary coexistence configuration between the two environments.
Bottom Line
M&A migrations succeed or fail on the planning stage inventory, conflict resolution, and mapping more than on the tool used to execute them. But once that groundwork is done, the execution phase is where manual scripting tends to slow teams down against deal timelines. The real deciding factor on whether or not the move will go well is whether or not you resolve name conflicts prior to the actual migration process and incrementally synchronize data as opposed to synchronizing everything at one go. The bottom line of the comparison is that the amount of time you have as per your deal terms plays a decisive role here along with the level of risk you are comfortable taking on the scripting front.
Microsoft 365 Tenant to Tenant Migration After a Merger or Acquisition was last modified: September 10th, 2026 by Shelly Bhardwaj
The strongest case for staff augmentation isn’t any single benefit on this list. It’s how many of them stack on top of each other inside the same hiring decision.
Cost savings show up fastest, but they’re rarely the reason a team keeps using the model past the first engagement.
Most of the value depends on treating the engagement as an extension of the team rather than a transaction.
A handful of these benefits only appear after several months, well past the first placement.
Two realistic paths exist when a 10-person product team needs 3 specialized engineers inside 6 weeks: stretch a standard hiring process past its limits, or bring in help built for exactly that timeline. Most teams that have tried the first path once don’t try it again. Below are 10 concrete benefits, each traceable to a specific mechanic of how staff augmentation services work, rather than a single generic pitch.
An IT staff augmentation company earns its place in a hiring plan by solving problems a standard recruiting funnel structurally can’t solve, regardless of price. The 10 benefits below are ranked roughly in the order most teams notice them, starting with the one that shows up fastest.
None of these benefits require a company to abandon direct hiring altogether. Most engineering leaders who use this model well run it alongside a direct hiring pipeline rather than in place of one, reaching for each approach where it fits the problem in front of them.
1. Faster access to specialized engineers
Sourcing, screening, and reference checks happen against a pool a provider already knows, rather than starting a search from zero. A role that would take a standard funnel 8 to 10 weeks to fill often closes in 2 to 3 weeks instead, since the vetting work has already been done ahead of the request. Across the 500-plus engineers we’ve placed since 2017, that head start is consistently where most of the time savings comes from. Cutting a step of the vetting process short isn’t.
Staff augmentation services close this gap specifically because the sourcing overhead is already sunk before a client ever submits a request. That head start is the single biggest reason the model gets reached for first when a timeline is the binding constraint.
The speed advantage compounds when several roles need filling at once. A recruiting function sized to close 2 or 3 roles a quarter doesn’t suddenly handle 8 without either slowing every search down or lowering its bar, while a provider built for volume treats that same request as routine.
2. Spend that scales with the actual need
An IT staff augmentation company bills like a service rather than a payroll line, which means the cost tracks the engagement instead of sitting on the books as a fixed headcount commitment. A team that needs a burst of capacity for one quarter isn’t stuck carrying that cost once the quarter ends.
That flexibility runs in both directions. An IT staff augmentation provider that’s priced correctly makes it just as easy to scale a team down in a slow quarter as it is to scale one up in a busy one, without either move triggering a layoff or a hiring freeze. A finance team that understands this upfront tends to approve the spend faster than one that discovers the billing model halfway through a budget cycle.
3. A dedicated team built around one roadmap
Rather than splitting a contractor’s attention across several clients, good dedicated development team services work exclusively on one company’s roadmap, reporting into that company’s own leads the same way an internal hire would. The engineers show up to the same standups, work off the same backlog, and carry the same context week over week.
That exclusivity is what separates a true dedicated team from a shared contractor pool. A team split across 5 clients simply can’t build the same depth of product context as one working a single roadmap full time.
Product context is the part that’s easiest to underrate going in and hardest to replace once it’s built. An engineer who has spent a year on one codebase catches edge cases and history a brand-new hire, internal or external, simply hasn’t had the chance to learn yet.
4. Headcount that moves with the roadmap
A provider offering IT staff augmentation services that’s built for volume can add engineers to a growing initiative or wind a team back down once a project ships, without the client managing a hiring freeze or a layoff to get there. That flexibility matters most exactly when a roadmap shifts unexpectedly, which is most of the time.
Direct hiring rarely offers that same elasticity. A team that hires 5 engineers to cover a 6-month push either finds new permanent work for all 5 once the push ends or manages an awkward conversation about headcount it didn’t plan for at signing.
5. Less recruiting and HR overhead carried in-house
IT resource augmentation services fold sourcing, payroll, benefits administration, and local compliance into the engagement itself, which means an internal recruiting function isn’t stretched thin covering roles that a specialized partner already handles end to end. That freed-up capacity usually goes straight back into the searches only an internal team can run.
Legal and compliance work in particular is where IT resource augmentation services save the most invisible time, since payroll and employment law across multiple regions is rarely something an internal HR team wants to own directly.
That overhead doesn’t disappear when a company hires directly in a new region. It just moves onto someone’s plate internally, usually without anyone budgeting the hours it takes to stay current on a second or third country’s employment rules.
6. A team built without a local entity
A company expanding into a market where it has no legal entity yet can still hire a dedicated software development team there, since the provider handles the local employment relationship. Waiting on entity paperwork before hiring the first engineer in a new region can cost months a growing roadmap doesn’t have.
This benefit matters most for market-entry timelines specifically. A company testing demand in a new region rarely wants to commit to setting up a full legal entity before it even knows whether the market is worth the investment, and building a team there without that commitment keeps the option open either way.
7. Access to talent pools a local search can’t reach
Offshore recruiting opens a search up to markets with deep benches in a specific stack, rather than competing for the same narrow local pool every other company nearby is also hiring from. A team relying on offshore staffing services for a hard-to-fill specialty often finds candidates faster than a team searching locally for the same skill set, simply because the pool is larger to begin with.
8. Broader working-hours coverage
Offshore IT staffing services spread across 2 or 3 overlapping time zones can extend a team’s effective working hours well past a single office’s schedule, without anyone working an unreasonable shift. Teams built around that kind of overlap tend to produce smoother handoffs than teams assembled without any timezone planning at all.
The coverage benefit compounds during incidents specifically. Offshore staffing services structured around a second time zone mean a production issue that starts at 6pm local time doesn’t have to wait until the next morning for someone to look at it.
The same overlap that helps with incidents also helps with ordinary delivery cadence. A pull request opened at the end of one team’s day can pick up a review from a teammate just starting theirs, instead of sitting untouched for 12 hours until the original author is back online.
9. Lower total cost than building the same team from scratch
Choosing to hire a dedicated software development team through an established provider usually costs less than assembling the same software development dedicated team through direct hiring, once recruiting fees, benefits administration, equipment, and ramp time are counted alongside salary. The gap is largest for hard-to-fill specialties, where a direct search can drag on for months before a single offer goes out.
Companies that decide to hire dedicated software development team support specifically to avoid that drawn-out search usually recover the provider’s margin within the first quarter, once the cost of an empty seat is priced in honestly. An empty seat rarely shows up as a line item anywhere, which is exactly why it’s the easiest cost to underestimate when comparing the 2 paths on a spreadsheet.
10. A long-term partner, not a one-off vendor
A mature IT staff augmentation agency keeps the same engineers on an account across multiple projects, which means the second and third engagements start with people who already understand the codebase and the team’s working style. An established offshore staffing agency relationship also tends to come with better bench visibility, since the provider already knows what a client’s standards look like.
That continuity is worth more over time than any single placement, and it’s the main reason companies that hire dedicated development team support once tend to come back for the next one rather than shopping the search from scratch. A provider that already understands a client’s codebase, coding standards, and release process can staff a second project faster and with less onboarding friction than starting the search over with an unfamiliar partner.
Common mistakes when evaluating these benefits
Treating cost savings as the main benefit is the most common mistake. It’s the easiest one to point to in a budget meeting, but teams that stop there miss the continuity and delivery-speed benefits that compound over multiple engagements.
Evaluating an offshore provider purely on rate is a close second. A rate that looks attractive on paper often hides weak vetting, and the resulting rework can erase the entire savings within the first few months.
Assuming every benefit on this list shows up in the first engagement is a third gap. Continuity, cultural fit, and process maturity build up gradually over several placements, long after day one.
Skipping a real onboarding process because the engineers are external is a fourth. Dedicated development team services still need repo access, a clear first task, and a named point of contact to ramp at the speed the model is supposed to deliver.
Waiting until a role is urgent to start evaluating a provider is a fifth. The companies that get the most value out of this model typically build the relationship before the pressure hits, so the first placement isn’t also the first time anyone tested how the provider performs.
Getting the most out of the model
Most of these benefits depend less on the provider and more on how the engagement is set up internally. A company that names an owner, defines a clear first task, and treats the engineers as part of the team from day one gets a materially different result than a company that treats the arrangement as a black box to check on occasionally.
The size of a company changes which of these 10 benefits matters most, without changing the underlying list. An early-stage startup usually cares most about speed and access to specialized skills it can’t yet afford to hire full time. A growth-stage company leans harder on the cost-predictability and headcount-flexibility benefits, since its hiring needs shift with funding rounds and product bets rather than staying flat year over year. A mature company with an established engineering org tends to value the market-entry and coverage benefits most, since its core team is already built and the gaps it’s filling are narrower and more specific.
None of that changes the mechanics behind any individual benefit. It just changes which ones a given company notices first, and which ones only become obvious a few quarters into using the model.
Taken together, these 10 benefits explain why the model has become a standing part of how many engineering organizations plan headcount, rather than a fallback reserved for emergencies. The teams that get the most out of it treat it as a permanent tool in the hiring toolkit, used deliberately for the problems it’s built to solve.
The providers worth staying with are the ones who make that easy rather than the ones who make the biggest promises upfront, and that holds whether the engagement is framed as staff augmentation, an offshore staffing partnership, or dedicated development team support running alongside an internal team.
How to evaluate a provider before signing
A provider’s own marketing rarely tells a buyer much about whether it can deliver on these 10 benefits consistently. The more useful signal is what happens when the request gets specific: how many engineers can be onboarded in a given month without a drop in vetting quality, and whether the provider can point to a specific team it has scaled before rather than a general claim about bench depth.
Retention data matters more than almost anything else on a provider’s pitch deck. A provider with high turnover among its own engineers is a weak bet even at an attractive rate, since a hiring manager ends up managing a revolving door of onboarding rather than a stable extension of the team. Asking for that number directly, before signing, tends to separate serious providers from ones relying on a strong sales conversation to close the deal.
Communication overlap deserves the same scrutiny as technical skill. An engineer who’s a strong technical match but shares almost no working hours with the rest of the team turns every code review and every planning meeting into an asynchronous exchange, which slows down exactly the kind of fast iteration this model is usually brought in to support.
Contract flexibility is worth reading closely before signing rather than after. A rigid, one-size-fits-all agreement that makes it expensive or slow to convert an engineer to a direct hire, or to wind an engagement down early, can quietly erase several of the 10 benefits this piece covers, even when the rate and the talent quality both looked strong going in.
None of this evaluation work has to be exhaustive to be useful. A short structured conversation covering onboarding process, retention numbers, communication overlap, and contract terms usually surfaces the gaps that matter most, well before either side has committed to anything.
Finally, a provider worth signing with should be able to explain, in specific terms, what happens if a placement isn’t working out. Vague reassurance is a worse sign than an honest answer that includes both a replacement process and a realistic timeline for it.
References are worth requesting even when a provider’s public case studies look strong. A short call with a current client, focused on concrete questions about ramp time, communication, and how the provider handled a problem when one came up, tends to reveal more in 15 minutes than a polished pitch deck reveals in an hour.
What a typical engagement looks like
Most engagements start the same way regardless of which of these 10 benefits mattered most in the decision: a short discovery call to scope the role, a shortlist of pre-vetted candidates within days rather than weeks, and a final interview loop the client runs itself before anyone signs on. Offshore staffing services built around this sequence tend to move faster than a process that starts sourcing only after the request comes in.
Once an engineer is selected, dedicated development team services typically begin with a structured first week: repo access on day one, a scoped first ticket, and a standing check-in with whoever owns the account internally. Skipping any one of those 3 steps is the single most common reason a promising engagement starts slow.
Offshore IT staffing services add one more layer worth planning for upfront: confirming working-hours overlap before the first day rather than discovering the gap after it. A team that waits to discover a 4-hour gap in availability loses weeks it could have planned around from the start.
None of this requires a large team to matter. Even a single offshore hire, added deliberately to extend coverage into a second time zone, changes how quickly a team can respond to something that breaks outside normal working hours.
By the 30-day mark, the honest measure of how the engagement is going has less to do with how many commits an engineer has shipped and more to do with whether the surrounding team’s actual output moved. A team that adds capacity and ships the same amount it shipped before has an onboarding problem worth fixing that more headcount alone won’t solve.
By the 90-day mark, retention becomes the number worth watching most closely. A provider that loses engineers mid-engagement is usually telling a buyer something about its own internal process, whether or not it says so directly, and it’s worth asking about proactively rather than waiting to find out the hard way.
The teams that get the smoothest first ninety days tend to share one habit: they treat the ramp period as something to actively manage rather than something that happens on its own. A weekly 15-minute check-in during the first month, focused specifically on blockers rather than status, catches most onboarding problems long before they show up in a delivery metric.
Frequently asked questions
Is staff augmentation cheaper than direct hiring?
Usually, once recruiting costs, benefits, and ramp time are counted alongside salary, though the gap depends on role scarcity and how long a direct search would otherwise take. It’s largest for hard-to-fill specialties, where a dragging search carries its own hidden cost.
How fast can a provider fill a role?
Often 2 to 3 weeks for a role already close to the provider’s existing bench, though a highly specialized skill set can take longer regardless of provider.
Do these engineers work exclusively on one company’s project?
On a well-run engagement, yes. That’s what separates a dedicated team from a shared contractor pool splitting attention across several clients at once.
Does the model work for a company with no local entity in a new market?
Yes. The provider handles the local employment relationship, which lets a company start hiring in a new market well before any entity paperwork is filed.
Is an offshore staffing agency the same thing as a staff augmentation provider?
Functionally, most of the time. Both describe a provider that employs the engineer and hands day-to-day direction to the client, whichever label sits on the homepage.
How long does a typical engagement run?
It varies widely, from a few months covering a specific project to multi-year arrangements that function as an ongoing extension of the team. The length should follow the actual need rather than a fixed contract term.
Can an engineer placed this way convert to a direct hire later?
Usually, yes, though conversion terms vary by provider and are worth confirming before signing rather than assuming they’re standard.
Top 10 Benefits of Staff Augmentation Services was last modified: September 8th, 2026 by Adsy Collins
Managing safety compliance across distributed field operations requires precise coordination between mobile workers and office staff. Missing inspection forms, delayed incident logs, and paper checklists create information gaps that increase financial risk.
Automated data synchronization eliminates manual updates by linking field entries directly with central desktop databases. When field crews record daily checks on mobile devices, office managers gain immediate visibility into operational hazards.
Mitigating Legal and Financial Risks in Field Operations
Unsynchronized records create severe liabilities during workplace injury audits. Discrepancies between field activity logs and central management files often weaken legal defenses during formal disputes. Real-time background sync keeps legal teams and safety managers working with matching dataset versions across all departments.
Commercial construction and utility projects in Richmond require strict adherence to regional safety standards. When an injured technician requires medical coverage or legal assistance, working with a Richmond workers' compensation attorney helps clarify the complexities of state claims. Maintaining accurate digital records provides clear evidence of baseline compliance during formal administrative reviews.
Field managers who rely on outdated paper logs often face audit delays and lost documentation. Standardizing on digital field input forms ensures that every inspection record receives an instant timestamp. This disciplined documentation habit protects companies against unexpected regulatory challenges.
Moving From Manual Planning to Automated Performance
Industry research indicates that recent corporate compliance strategies represent a decisive pivot from basic planning to active performance. Organizations using integrated compliance systems experience measurable reductions in repeated risk items across all project sites. Automation removes the friction of manual spreadsheet uploads.
Field crews need simple mobile workflows that push inspection logs straight to core desktop software. Direct synchronization prevents lost paperwork and ensures safety metrics remain complete every single day. Teams spend less time organizing paper forms and more time rectifying hazards.
Desktop software systems function best when fed continuous real-time data from field devices. Eliminating manual data re-entry minimizes transcription errors and keeps administrative records accurate.
Uncovering Blind Spots Through Rapid Incident Reporting
Fast incident reporting uncovers hidden hazards, surfaces systemic operational issues, and establishes a reliable loop of continuous safety improvement. Industry data reveals that work-related injuries lead to 103 million annual days lost across modern industrial sectors. Digital sync platforms reduce reporting delays from days to seconds.
Connecting field devices to central servers provides clear operational benefits for growing field operations:
Automatic timestamping verifies exactly when safety inspections occur.
Offsite supervisors receive instant notifications for critical safety violations.
Central databases stay synchronized without tedious end-of-day manual entry.
Rapid incident logging allows safety coordinators to identify emerging risks before minor issues become major disruptions. Immediate data transfer allows teams to dispatch corrective support quickly.
Deploying Mobile-First Solutions for Field Usability
Modern mobile-first safety management software is engineered to suit field service businesses operating outside traditional offices. Industry statistics show around 72% of new platform installations support mobile reporting functions to maximize field usability. Technicians complete safety audits much faster when software mirrors their daily mobile routine.
User-friendly mobile screens encourage higher submission rates from active job sites. Automated sync engines handle data delivery behind the scenes so crews remain focused on their primary physical tasks.
Intuitive mobile interfaces let workers fill out forms in seconds using drop-down menus and simple touch inputs. A smooth user experience turns safety compliance into a seamless daily habit.
Maintaining Continuous Offline Sync in Remote Locations
Dedicated platforms capture annotated photos with automatic geo-tagging offline and sync all records when network connectivity returns. Standard regulatory penalties increased significantly in 2025, reaching up to $16,550 per serious violation. Remote teams cannot afford data drops caused by poor cellular signals.
Offline synchronization stores completed inspection forms securely on the handheld device. Once a signal is re-established, the sync background engine transfers all pending records directly to desktop software.
Field workers operating underground or in rural areas frequently lose cellular connection. Local caching protects collected data from disappearing mid-entry. Intelligent sync rules resolve database conflicts automatically upon reconnecting.
Reducing Direct Workplace Injury Costs
National safety statistics show employers pay more than $1 billion per week in direct workers' compensation costs for disabling nonfatal workplace injuries. Streamlining data flow between field staff and risk management teams lowers these heavy financial burdens. Unified data synchronization provides leadership with the precise evidence needed to optimize risk mitigation programs.
Preventing a single major injury can save an organization thousands of dollars in medical costs and insurance premiums. Direct data integration allows risk managers to analyze real-time site metrics and fix dangerous conditions quickly.
Syncing safety compliance data bridges the physical gap between field personnel and administrative management. Connecting mobile forms directly to central desktop software builds an accurate record of daily field activities. Organizations that implement reliable data synchronization lower regulatory liabilities, protect field workers, and maintain seamless administrative operations across every active job site.
Syncing Safety Compliance Data Across Field Teams was last modified: September 6th, 2026 by Charlene Brown
Data synchronization has become an essential part of modern work. Employees expect contacts, calendars, tasks, notes, and other business information to remain consistent across computers, phones, and workplace applications. When synchronization works well, teams can access current information without repeatedly entering the same data or checking several systems for updates.
This convenience also creates a security responsibility. Every application, operating system, device, and service involved in moving or displaying synchronized data becomes part of the organization’s technology environment. If one component contains an unresolved vulnerability, attackers may have an opportunity to access sensitive information, interrupt operations, or compromise connected systems.
Secure synchronization therefore depends on more than reliable data transfer. It also requires disciplined software maintenance, with patch management playing a central role.
A Connected Environment Has Many Moving Parts
A synchronization process rarely involves only one application. Business data may pass between desktop software, mobile devices, operating systems, cloud services, and local networks. Each component can have its own release cycle, security requirements, and update process.
This creates a larger surface for IT teams to manage. A fully updated synchronization application may still interact with an outdated operating system. A protected office computer may exchange data with a remote device that has missed an important security update. A third-party utility may also introduce exposure if the organization lacks visibility into its installed version.
Organizations must therefore consider the condition of the entire environment, not just the application that users see. Security depends on every connected layer receiving appropriate maintenance.
Why Outdated Software Creates Security Gaps
Software developers regularly identify defects after an application has been released. Some affect usability or performance, while others may create security weaknesses. Vendors can address many of these issues through patches, which modify the software to correct known problems.
Once a vulnerability becomes known, an outdated application may remain exposed until the organization applies the relevant update or introduces an appropriate workaround or compensating control. In some cases, a vendor patch may not yet be available. The longer a known weakness remains unresolved or insufficiently mitigated, the longer the organization may operate with avoidable risk.
This matters in environments that handle synchronized business data. Contacts can contain personal and professional information. Calendars may reveal meeting details and future plans. Tasks and notes can include references to customers, internal projects, or operational priorities. Protecting this information requires attention to the software that stores, processes, and transfers it.
Reliable Synchronization Is Also a Business Continuity Issue
Cybersecurity is not limited to preventing information theft. It also concerns the availability and integrity of important systems and data.
If a vulnerable application becomes compromised, synchronization may stop working or begin producing unexpected results. Employees could lose access to current records, encounter conflicting versions, or spend time checking which copy is accurate. IT personnel may need to isolate devices, investigate the incident, and restore affected systems.
Regular patching helps reduce avoidable exposure before it develops into a larger operational problem. It can also address software defects that cause crashes, compatibility issues, or poor performance. As a result, software maintenance supports both security and dependable day-to-day work.
Manual Updates Become Difficult at Scale
Updating a single personal device may be straightforward. Managing updates across a business environment is more complicated.
Organizations may use different operating systems, application versions, device types, and configurations. Some employees work from an office, while others connect from home or another location. Devices may not be online when an update becomes available. Certain applications may also require updates outside normal working hours to avoid interrupting users.
A manual approach can leave IT teams dependent on spreadsheets, reminders, and individual follow-ups. It may also be difficult to confirm whether every device completed an update successfully. As the number of endpoints and applications increases, so does the possibility that something will be missed.
Centralized processes give administrators a clearer way to identify outdated software, prioritize necessary fixes, and verify deployment results. Organizations with distributed technology environments may use a patch management tool to automate updates and manage supported operating systems and third-party applications through a more consistent workflow.
Prioritization Matters as Much as Speed
Installing every update immediately is not always practical. Some patches address urgent security weaknesses, while others introduce minor improvements. Business-critical applications may also require testing before a new version is deployed broadly across the organization.
An effective patch management process should classify updates according to risk and business importance. IT teams can consider the severity of the vulnerability, the systems affected, the sensitivity of the data involved, and whether a device is accessible from outside the organization.
Critical security fixes should receive prompt attention when suitable patches are available. If a patch cannot be installed immediately, the organization may need to assess available mitigations until deployment becomes possible. Lower-risk updates can follow a planned schedule. This approach helps teams direct limited resources toward the weaknesses that could have the greatest impact.
Updates Should Be Planned to Minimize Disruption
Employees may postpone updates when they expect interruptions, forced restarts, or lost work. That behavior is understandable, but it can leave devices in an inconsistent security state.
Clear scheduling can reduce this friction. Routine updates can be assigned to maintenance windows or quieter periods, while urgent patches can follow an accelerated process. Employees should receive concise notices when an update requires their involvement.
Organizations should also monitor whether deployments succeed. An update that was approved but failed to install does not remove the vulnerability. Reporting and verification help IT teams identify unsuccessful installations and take corrective action.
Visibility Supports Accountability
A company cannot manage software effectively if it does not know what is installed. An accurate inventory should show which devices exist, which applications they run, and which versions are present.
This visibility helps administrators find unsupported or outdated software before it becomes an overlooked risk. It also assists with investigations and audits by providing a record of system changes and patch activity.
The process does not need to produce unnecessary complexity. Its purpose is to answer practical questions: Which systems require attention? Which updates are most important? Were they deployed successfully? Which devices still need remediation?
Reliable answers make patch management measurable rather than dependent on assumptions.
Patching Works Best as Part of Layered Security
Patch management is important, but it is not a complete cybersecurity strategy. Organizations still need appropriate access controls, strong authentication, secure backups, endpoint protection, employee awareness, and incident response procedures.
These measures address different kinds of risk. Access controls limit who can reach sensitive information. Backups support recovery. Security monitoring can reveal suspicious activity. Patching reduces exposure to known software weaknesses, while compensating controls may provide interim protection when immediate patching is not possible.
Together, these controls provide stronger protection than any single measure could deliver alone. For synchronized data, this layered approach helps protect information throughout its journey across applications and devices.
Make Software Maintenance a Routine Security Practice
Secure data synchronization begins with dependable software but cannot end there. Organizations must maintain the broader environment in which synchronization occurs, including operating systems, endpoints, and connected applications.
A documented patching process gives IT teams a repeatable way to discover missing updates, prioritize security fixes, schedule deployments, and verify results. When a patch is unavailable or cannot yet be deployed safely, the process should also support the evaluation of temporary mitigations and compensating controls. Automation can further reduce repetitive work and make maintenance more consistent across distributed devices.
When patch management becomes a regular business practice rather than an occasional reaction, organizations can reduce preventable weaknesses while supporting reliable access to synchronized information. The result is a more resilient technology environment where productivity and cybersecurity reinforce each other.
Why Secure Data Synchronization Depends on Strong Patch Management was last modified: September 3rd, 2026 by Thomas Lore
A CMS for React has one job: let someone publish without opening a pull request. Pricing tier, editor polish, and plugin count are details you sort out later. Three harder questions come first. Does the app need a CMS at all? Self-hosted or managed? And how does new content actually reach a rendered page?
Most roundups skip straight to naming platforms. Storyblok, Sanity, Contentful, Payload, Strapi. React 19 hit 48.4% daily use within months of release, per the 2025 State of React survey. The CMS market serving that base keeps splitting into more options every year. More names on a list make “which one” louder as a question, not easier to answer.
Question One: Do You Even Need a CMS?
If the person editing content is a developer, you don’t. A Markdown file in the repo, reviewed through a pull request, ships faster and skips the API round trip entirely.
Reach for a CMS once a non-developer needs to publish without you. Or once content changes faster than your deploy cycle can keep up. A marketing team running weekly campaigns. A support team updating FAQ copy every day. That’s the real trigger, and it has nothing to do with tech stack. It’s about who’s allowed to hit publish.
Question Two: Self-Hosted or Managed?
This gets sold as a technical decision. It’s really a cost decision wearing a technical costume, and most comparison posts skip the math.
On raw dollars, self-hosted wins big. A self-hosted open-source CMS can run 600to600to15,000 over five years on a modest VPS. A managed plan can climb into six figures over that same stretch for a busy site.
The dollar figure isn’t the whole cost. Someone still has to run the thing. Even with solid automation, a self-hosted CMS eats roughly one to two hours a month in ops time: patches, backups, uptime checks. That’s a small tax for a team that already has spare engineering hours. It’s a real cost for a two-person team shipping features full time.
A working rule: count your editors and your spare engineering hours, not just the number on a pricing page. Small teams with no ops slack usually come out ahead on managed. Agencies running several client sites, or teams with room in the sprint, tend to earn that cost back within 12 to 18 months of self-hosting.
Question Three: How Does Content Reach the Page?
This is the part that’s actually specific to React, and the part generic CMS roundups skip.
A headless CMS is API-first. Content comes back as JSON or over GraphQL, decoupled from any one front end. That’s what makes it work equally well for a React site, a mobile app, or anything else reading from the same source. An old-style CMS welds its front end to its content store. Wiring that into a React app usually means fighting the platform rather than using it.
Once a CMS is API-first, a React or Next.js app has three real ways to pull from it:
Fetch at build time. Static generation reads content once, at build. Fast and cheap, stale until the next deploy. Fine for content that barely moves.
Fetch on every request. Server components hit the CMS on each page load. Always current, but every visitor pays the CMS’s response time.
Cache the response, clear it on demand. Pages serve from cache like static output. A webhook tells the app to drop specific entries the moment content actually changes.
The third option is the one worth the setup time, and almost nobody writes about it. Most teams either over-fetch on every request or under-fetch and serve stale pages for hours. A webhook closes that gap for free.
Wiring Up Webhook-Driven Cache Clearing
Next.js’s revalidateTag clears cache by tag instead of by page. Tag a fetch once, then clear that exact tag when the CMS tells you something changed:
return new Response(“Unauthorized”, { status: 401 });
}
const { slug } = await request.json();
revalidateTag(`post:${slug}`);
return Response.json({ ok: true });
}
The CMS calls this endpoint on publish, and only the matching tag clears. A site with thousands of pages doesn’t rebuild the whole thing because one entry changed. Draftbase’s own webhooks run this exact pattern. A publish event pushes to your app, so nothing has to poll for changes. Check the signature header before touching the payload. An open revalidation endpoint is a free invitation to hammer your cache.
Does the CMS Choice Change React SEO?
Only through rendering, not through the CMS itself. A React app that renders content purely client-side ships an empty shell to a crawler until the JavaScript finishes running. Google’s own guidance on JavaScript SEO describes a second rendering wave for JS-heavy pages, well behind text-first pages in the queue. Server components and static generation skip that wave entirely, since the HTML a crawler sees already has the content baked in.
What the CMS needs to get right is narrow. Clean, structured fields for title, description, and Open Graph image that map onto Next.js’s Metadata API. And a way to list published slugs for a sitemap. A CMS that lets raw HTML leak into a title field makes both jobs harder. So does hiding the slug behind a picker with no API access.
When an Old-Style CMS Still Wins
A fair comparison has to say this part too. A team with no front-end developer, and no plan to build a custom app, ships faster with a single bundled CMS and a theme than with any headless setup. If the actual requirement is “we need a whole website with an editor attached,” going headless solves a problem that team doesn’t have yet. The moment a real React front end enters the picture, that trade reverses.
The Schema Outlasts the Platform Pick
Whatever CMS wins, the content schema is the part that survives the tooling decision. A content type built around one loose rich-text blob turns every layout change into a migration project. Fields modeled as typed, reusable pieces survive a redesign, because only the component rendering the data has to change, not the data itself. Spend the modeling time up front. It costs less than fixing content after the fact.
Common Questions
Does a headless CMS work cleanly with the Next.js App Router? Yes, with one adjustment. Fetches inside Server Components run without client-side context, so pass any CMS config or client instance as props rather than through a provider.
Is a headless CMS overkill for a small React app? For a five-page site updated twice a year, yes. A Markdown file per page is simpler to maintain. The CMS earns its keep once publishing frequency or editor headcount climbs.
Can you swap CMS platforms later without a full rewrite? Only if the fetch logic lives behind your own data functions, not scattered across components. Worth doing regardless of which CMS gets picked first.
Does going headless hurt React SEO? No, as long as pages render server-side or statically. The SEO risk comes from client-only rendering, not from where the content is stored.
Making the Call
Skip the platform-name debate until the three real questions are answered. Does a non-developer need to publish? Does the team have spare hours to run its own CMS? Will the fetch pattern keep pages both fast and current? Get those right first. The specific platform, a hosted React CMS framework or otherwise, ends up a much smaller decision than the marketing pages make it look.
CMS for React: Three Questions Before You Pick a Platform was last modified: September 3rd, 2026 by Chris Umendeche
Most discussions about AI watermarking focus on detection methods or philosophical debates about transparency. What enterprise teams actually need is a roadmap for adapting workflows when watermarked text becomes the norm across every major AI provider. Your content operations will change dramatically over the next year, and waiting until watermarking arrives in every tool you use might leave your team scrambling.
The shift toward embedded watermarks represents more than a technical feature. Companies now face questions about governance frameworks, cross-platform consistency, and legal documentation that simply did not exist before. Building the right infrastructure today prevents compliance headaches tomorrow.
What AI Text Watermarking Means for Your Business (Not Just Claude)
AI text watermarking embeds invisible statistical patterns into generated content that specialized tools can later detect. Unlike metadata tags that disappear when text gets copied, these patterns persist through typical editing and reformatting. Anthropic released this capability for Claude in early 2025, but the technology will likely spread across OpenAI, Google, and other providers soon.
Your business probably uses several AI writing platforms already. Marketing teams might rely on one tool while customer support uses another. Each platform will implement watermarking differently, with varying detection thresholds and persistence characteristics. The strategic challenge involves managing this complexity across your entire content ecosystem.
Watermarking creates accountability. When AI-generated content appears in customer communications, marketing materials, or documentation, watermarks provide an audit trail. This matters for regulated industries where content provenance affects compliance obligations. Financial services firms and healthcare organizations face particular pressure to demonstrate content origins.
The Federal Trade Commission has already signaled interest in AI transparency for consumer-facing content. Watermarking technology gives compliance teams a verification mechanism that manual processes cannot match at scale.
Assessing Your Current AI Content Stack: Tools, Workflows, and Watermark Exposure
Start with an inventory. Document every AI writing tool your organization uses, including shadow IT deployments that individual teams adopted without central approval. Check procurement records, browser extensions, and departmental software subscriptions. Many companies discover a dozen AI platforms running simultaneously across different business units.
Map how content flows through your organization. Does AI-generated draft copy move through editing systems, translation platforms, or content management databases? Each handoff point represents a potential watermark preservation or degradation risk. Heavy editing might weaken watermark signals while automated reformatting could eliminate them entirely.
Evaluate your current content governance policies. Most enterprises built these frameworks before watermarking existed, so gaps will appear. Your policies probably address plagiarism detection and brand voice consistency but might ignore AI content authentication entirely. This gap exposes your organization to risks as watermarking becomes industry standard.
Calculate your watermark exposure percentage. What portion of your published content contains AI-generated text? Some teams use AI for initial research and outlining while others generate complete drafts. Understanding this baseline helps prioritize policy updates and detection infrastructure investments.
Setting Up Detection Infrastructure: Tools and Methods That Actually Work
Detection infrastructure requires both technical tools and human processes. Anthropic provides a watermark detection API for Claude-generated content, but cross-platform detection remains challenging. No universal detector works across all AI providers yet, so enterprises need multiple verification methods.
Build detection checkpoints into content workflows rather than treating verification as a final step. Configure your content management system to flag potentially watermarked text before publication. This early warning system prevents watermarked content from reaching customers when disclosure matters.
Consider implementing random sampling protocols. Testing every piece of content might prove impractical, but statistical sampling provides reasonable assurance. Audit a percentage of published materials monthly to verify watermark detection accuracy and identify process gaps. Financial auditing principles apply equally well to content verification.
Document detection accuracy rates for each tool in your stack. Different AI providers will show varying watermark persistence after editing. Claude watermarks might survive heavier modification than other platforms. Track these performance differences to inform content workflow decisions and editing guidelines.
Partner with vendors who prioritize watermarking capabilities. When evaluating new AI content tools, ask specific questions about watermark implementation, detection APIs, and roadmap commitments. Vendor selection criteria should include watermarking support alongside traditional factors like accuracy and cost.
Updating Content Governance Policies for Watermarked AI Text
Your governance framework needs explicit watermarking protocols. Define when AI-generated content requires disclosure to end users versus internal tracking only. Consumer-facing marketing materials might demand different transparency standards than internal research reports. These distinctions should reflect both legal requirements and brand values.
Establish editing thresholds that preserve watermark integrity. If substantial human revision removes detectable patterns, your audit trail disappears. Set guidelines about how much editing content can undergo while maintaining watermark verification. Some organizations prohibit heavy modifications to AI drafts specifically to maintain detection capability.
Create approval workflows that account for watermarked content. Certain materials might require additional legal review when watermarks indicate AI generation. Build these routing rules into your content management platforms so review happens automatically rather than relying on manual flagging.
Address the hybrid content challenge. Most business content combines AI-generated sections with human writing. Your policies should clarify how to handle mixed-origin materials, what percentage of AI content triggers watermark disclosure, and how to document the authorship blend. The Society for Human Resource Management suggests similar documentation approaches for AI-assisted hiring decisions.
Cross-Platform Watermarking Strategy: Handling Multiple AI Providers
Standardization becomes critical when managing multiple AI platforms. Different providers will implement incompatible watermarking schemes, creating integration headaches. Your enterprise needs a unified approach despite underlying technical fragmentation.
Designate primary AI tools for specific content types. Marketing might standardize on one platform while technical documentation uses another. This segmentation simplifies watermark management because each content category has predictable watermark characteristics. Avoid allowing every team to choose their preferred AI tool independently.
Build a watermark registry that tracks which AI platforms generated which content. This metadata layer sits above individual watermarking implementations and provides consistent tracking regardless of underlying technology. When vendors change watermarking approaches or new tools enter your stack, the registry maintains continuity.
Negotiate enterprise agreements that include watermarking guarantees. As you consolidate AI vendors, contractual commitments about watermark persistence, detection API access, and advance notice of watermarking changes protect your investment in detection infrastructure. Treat these provisions as essential rather than optional contract terms.
Legal and Compliance Considerations: Disclosure, Liability, and Documentation
Disclosure requirements vary by industry and jurisdiction. Financial services regulations might mandate revealing AI involvement in investment advice while general marketing faces fewer restrictions. Consult legal counsel about disclosure obligations specific to your business operations and customer base.
Liability questions remain unsettled. If watermarked AI content contains factual errors or creates customer harm, who bears responsibility? Your policies should address quality assurance processes that compensate for AI limitations. Simply detecting watermarks does not absolve organizations of content accuracy obligations.
Documentation standards must evolve alongside watermarking capabilities. Maintain records showing what content underwent watermark detection, results of those scans, and any remediation actions taken. These audit trails become critical if regulatory inquiries arise or legal disputes involve content authenticity.
The Small Business Administration recommends similar documentation practices for other automated business processes. Apply those same rigor standards to AI content governance. Treat watermark detection logs as permanent records rather than temporary operational data.
Future-Proofing Your Content Operations as Watermarking Becomes Standard
Industry-wide watermarking adoption will accelerate faster than most enterprises expect. Building flexible systems now prevents costly retrofitting later. Design detection infrastructure that can incorporate new AI providers without complete workflow redesigns.
Invest in team education about watermarking implications. Content creators need to understand how their editing choices affect watermark persistence. Legal teams require training on disclosure obligations. Operations staff must learn detection tool capabilities and limitations. This knowledge investment pays dividends as watermarking complexity increases.
Monitor regulatory developments that might mandate watermarking practices. Several countries are considering AI transparency legislation that could affect content disclosure requirements. Staying ahead of these regulatory curves positions your organization as a compliance leader rather than a reluctant follower.
Plan for interoperability improvements. Current watermarking fragmentation will likely give way to industry standards that enable cross-platform detection. Position your infrastructure to adopt these standards quickly when they emerge. Flexible architecture choices today enable rapid adaptation tomorrow.
Building robust AI content governance around watermarking technology requires immediate action. Enterprises that establish detection infrastructure, update policies, and train teams now will navigate the watermarked content landscape confidently. Those who delay risk compliance gaps and operational chaos as watermarking becomes ubiquitous. Start your watermarking strategy assessment this week, not next quarter.
AI Watermarked Text: The Enterprise Implementation Guide for Content Teams was last modified: September 1st, 2026 by Thomas M
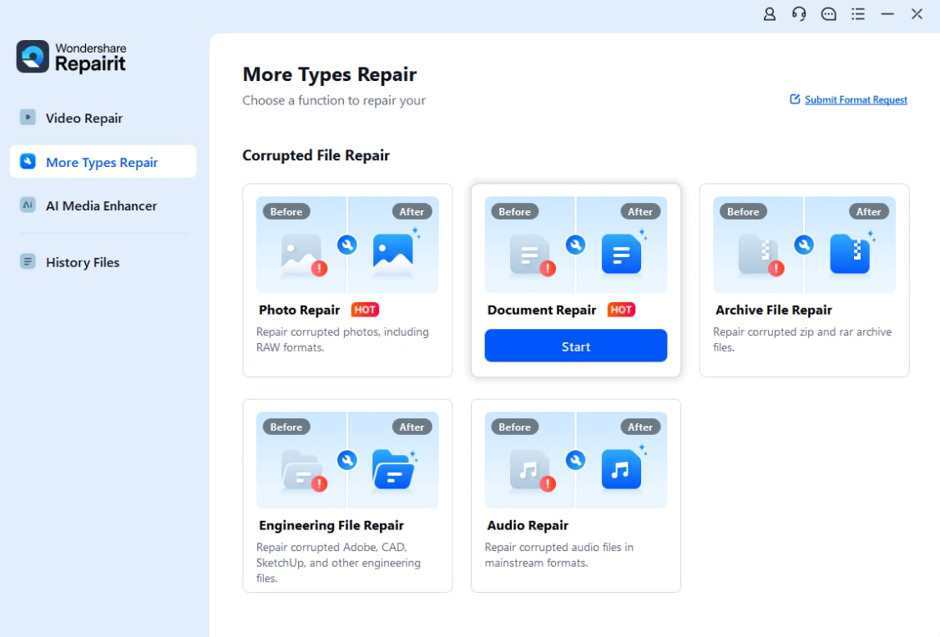
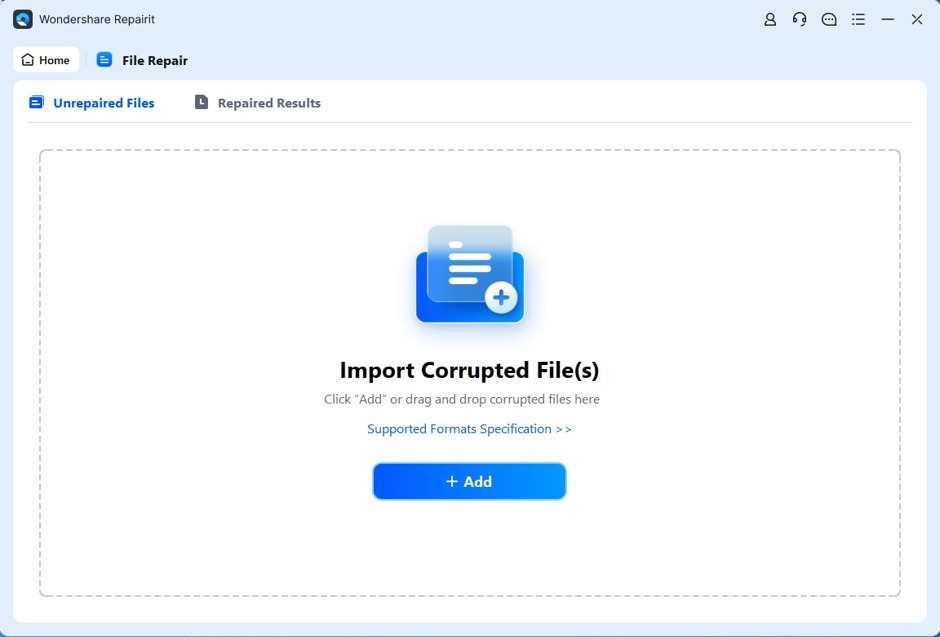
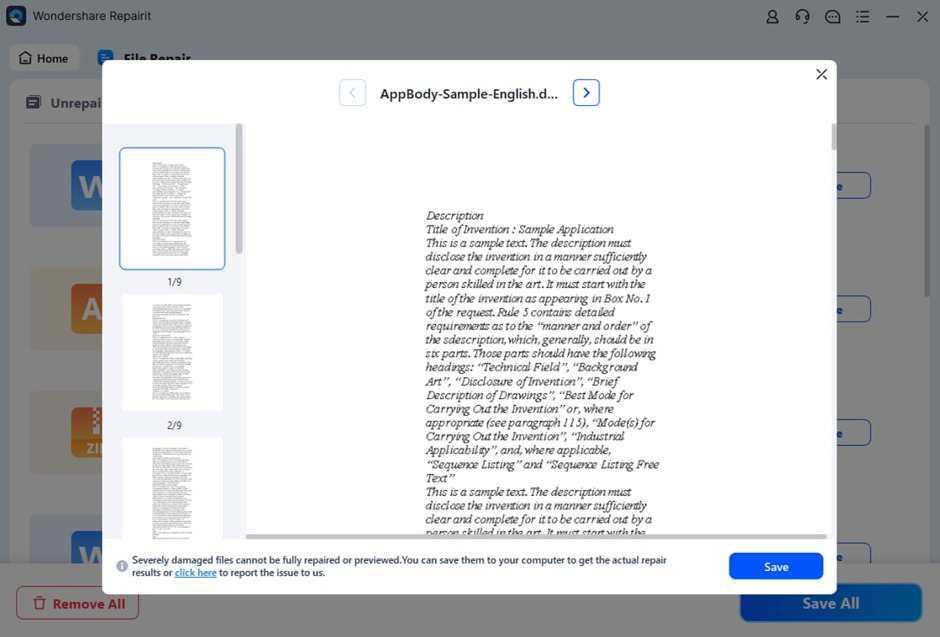
When a file refuses to open, the safest first move is to protect the original copy and test a repair corrupted file workflow before you try to rebuild anything from memory. That simple habit helps separate a bad save, a sync conflict, or a transfer error from deeper file damage.
Why files become corrupted in daily work
Files usually break during ordinary work moments rather than dramatic accidents. A laptop can lose power during a save, an app can crash while writing the final version, a cloud folder can sync two edits at once, or a USB transfer can stop halfway through. The file name may still look normal, but the underlying structure is no longer reliable. In many cases the document is not fully gone; it is only missing enough structure that the app can no longer read it cleanly.
That is why file corruption is so confusing. The content often still exists in part, but the program cannot read it cleanly. In practice, the first response should be simple: stop overwriting the original, make a duplicate, and check whether a backup or version history already contains a clean copy.
That is why the most common complaints are usually the same: the image looks faded, soft, torn, scratched, or simply too weak to print, share, or archive without more work.
What should you try before starting file repair
Before you repair anything, look for an easy recovery path. Check autosave, local drafts, cloud version history, and any earlier export you may have saved. If the file still fails to open everywhere, the problem is likely in the file structure rather than the app you are using.
For a browser-based first pass, Repairit Online can quickly show whether a smaller file still has a recoverable structure without forcing a full desktop setup.
When the file is larger, more complex, or tied to a deadline, a desktop workflow is usually the better next step. You can choose Wondershare Repairitdesktop version. It keeps the original file local, gives you more room to review the result, and fits better when the damaged document contains tables, attachments, or repeated revisions. That is especially useful for reports, project notes, and shared files that other people still need to edit.
Step-by-Step: Repair a Corrupted File
The process is intentionally direct: choose file repair, add the damaged file, and preview the repaired result before you trust it. That keeps the user focused on recovery instead of on technical file details.
This workflow is helpful because it reduces the risk of making the file worse. You work on a duplicate, let the tool inspect the damaged copy, and only then decide whether the recovered version is good enough to return to work. If the preview does not look right, you can stop there and try another version instead of burning time on repeated manual attempts.
For office files, the value is not only repair speed. It is also consistency. A clear sequence gives people a repeatable way to handle corrupted documents, spreadsheets, presentations, and PDFs without starting over from scratch. It also makes the handoff easier when a teammate needs to review the repaired copy after you are done.
Repair corrupted files step-by-step
Step 1: Add a copy of the damaged file
Always work on a duplicate. Keep the original untouched so you still have a fallback if the repair result is partial or if you later find a better version in backup. This single habit prevents most recovery mistakes.
Step 2: Let Repairit analyze the file
Open the repair workflow and add the damaged copy. The tool inspects the file structure for you, which is useful when the document still exists but behaves as if it were broken. The goal is to get back a readable version without guessing at the internal format.
Step 3: Preview and save the repaired result
Review the output carefully before replacing the working copy. Check text, layout, tables, and any embedded content. If the file opens normally and the important parts are still intact, save it as a new clean copy and keep the source archive unchanged.
Desktop vs Online File Repair
The right choice depends on urgency and file complexity. Online repair is good for a quick first check, while desktop repair is better when the file matters enough to justify a more controlled recovery process. The difference is less about technology and more about risk: smaller, simpler files can move fast, but larger working files deserve more care.
Online repair fits smaller files and short decision cycles. Desktop repair fits large, important, or repeatedly edited files because it gives you more control over the recovery workflow and keeps the local copy in your hands.
For teams, the practical rule is simple: use the browser path for speed, and use the desktop path when the file is too valuable to treat lightly.
Choose online restoration when the photo still has readable detail
Use case
Desktop repair
Repairit Online
Large thesis, client project, or business file
Better for heavier files, deeper preview, and local control
Less ideal if the file is large or needs more review
Need a fast browser check before a deadline
Works well, but requires desktop setup
Best fit for quick checks and short recovery cycles
Shared campus or office computer
May need permission, install time, or local storage
Convenient when software installation is restricted
Conclusion
A corrupted file does not always mean the work is gone. The safer approach is to protect the original, repair a copy, and confirm the result before you replace anything in circulation.
gives that process a practical starting point when the file matters more than the time you would spend rebuilding it.
The practical goal is simple: do not wait for a meaningful image to become unusable before treating it as worth preserving. If the memory still matters, the photo deserves a chance to be saved.
How to Repair Corrupted Files Without Losing Work was last modified: September 1st, 2026 by Shahmeer Sikandar
Modern enterprise artificial intelligence systems rely on massive volumes of meticulously labeled training data. Whether powering autonomous mobility, automated retail checkouts, or large language models, an algorithm’s real-world accuracy depends entirely on data quality. The global data annotation market continues its rapid expansion toward multi-billion-dollar valuations, driven by the demand for complex computer vision and multimodal training pipelines.
Choosing an experienced data labeling partner ensures strict quality assurance, scalable human-in-the-loop workflows, and rapid delivery timelines. Here is a curated evaluation of the leading data annotation companies serving the US market in 2026.
What Are Data Annotation Services?
Data annotation is the process of labeling raw assets—including images, video streams, audio, and text—into structured formats that machine learning models can interpret. This involves tasks such as drawing bounding boxes around vehicles, segmenting agricultural imagery, transcribing speech, or categorizing sentiment in conversational data.
High-performing enterprise teams partner with specialized data annotation companies to ensure their training sets maintain sub-pixel precision and strict statistical consistency.
Top Data Annotation Providers in 2026
1. Tinkogroup
Founded in 2016, Tinkogroup has built an established reputation as a precision-focused data preparation partner for enterprise AI initiatives across North America and Europe. Operating with dedicated in-house labeling teams, the company combines human expertise with flexible tooling integrations (including CVAT, Labelbox, and Datasaur). Tinkogroup maintains up to 99% annotation accuracy through structured multi-tier quality assurance.
Core Services: High-precision Computer Vision (polylines, keypoints, semantic segmentation), NLP and text categorization, data processing, and structured web research.
Key Strengths: Dedicated annotator pods, transparent pricing models (fixed-price and hourly), and a complimentary pilot testing program for enterprise validation.
2. Scale AI
Headquartered in San Francisco, Scale AI provides foundational data infrastructure for enterprise tech giants, research labs, and defense applications. Through its proprietary Scale Data Engine, the platform combines automated pre-labeling with large-scale human review networks.
Core Services: Multimodal annotation, 3D LiDAR labeling, LLM evaluation, and synthetic data generation.
Key Strengths: Massive enterprise scalability, advanced automation pipelines, and deep tooling ecosystems.
3. Label Your Data
Label Your Data offers comprehensive data labeling services for computer vision and NLP models, supported by multi-step QA workflows. The provider delivers secure data handling processes compliant with international security standards.
Core Services: Bounding boxes, video object tracking, named entity recognition (NER), and speech transcription.
Key Strengths: API integrations, clear per-object pricing tiers, and fast turnaround on standard annotation formats.
4. Keymakr
Specializing heavily in Computer Vision, Keymakr delivers full-cycle training data creation and annotation. Supported by their proprietary Keylabs workflow platform, they specialize in complex spatial datasets for autonomous systems and smart robotics.
Core Services: Polygon segmentation, 3D point cloud LiDAR labeling, video tracking, and custom dataset creation.
Key Strengths: Robust video tooling, specialized sensor labeling, and strong quality control frameworks.
5. Anolytics
Anolytics provides scalable, cost-effective data labeling for machine learning teams developing computer vision and text models. Their workflow models cater to high-volume image classification, e-commerce catalog structuring, and geospatial mapping.
Core Services: Image and video annotation, boundary labeling, satellite imagery processing, and content moderation.
Key Strengths: Competitive rates for large-scale routine data labeling and extensive offshore production capacity.
Key Criteria for Selecting a Data Annotation Partner
When evaluating external data labeling vendors, enterprise AI leaders focus on five essential operational factors:
Verification and QA Architecture: Look for multi-tiered review systems that implement consensus scoring, inter-annotator agreement tracking, and real-time accuracy benchmarks above 95%.
Domain Expertise: Ensure the provider has direct production experience handling your specific data modality, such as data annotation for path planning or complex NLP tokenization.
Data Security and Compliance: Verify strict adherence to international security frameworks such as ISO 27001, SOC 2, and GDPR.
Workforce Management: In-house or dedicated managed teams consistently provide higher labeling consistency and lower turnover than open crowdsourced labor pools.
Pilot Evaluation: Leading vendors offer free sample annotation runs to demonstrate accuracy, turnaround time, and guideline adherence before full contract deployment.
Emerging Trends in Training Data Operations
The data annotation sector continues to evolve alongside advances in foundational AI models:
Multimodal Pipelines: Modern models require unified labeling across multiple inputs—combining synchronized video, audio transcription, and sensor metadata within a single workflow.
Human-in-the-Loop Verification: AI-assisted pre-labeling accelerates production, but human domain experts remain essential for resolving complex visual ambiguities and edge-case exceptions.
Risk-Adjusted Quality Control: Enterprise teams are moving away from rigid sampling toward adaptive QA, automatically adjusting review rates based on task complexity and individual annotator reliability.
Top Data Annotation Companies in the USA: 2026 Industry Guide was last modified: August 26th, 2026 by Colleen Borator
Every founder has been there. You're two weeks into building something, and suddenly you've signed up for fourteen different apps. There's a project board you barely open, a note-taking tool nobody agreed on, and three overlapping ways to send messages. None of it talks to each other, and half of it's on a free trial that expires on Friday.
The temptation to over-tool is real, especially when every SaaS company on earth is targeting early-stage teams with slick onboarding flows. But when there are only two of you, the best tech stack is the one you'll actually use every day. Here's what that looks like in practice, broken down into the five slots that genuinely matter.
Email That Does More Than Send Messages
This sounds obvious, but your email provider is doing more heavy lifting than you think. Google Workspace or Microsoft 365 will give you a professional domain, shared inboxes, and enough storage to last your first year without thinking about it.
Pick one. Don't split it. If one founder lives in Gmail and the other in Outlook, you'll waste hours forwarding things back and forth. Agree early on a single provider and stick with it. The admin overhead of switching later is worse than compromising now.
A Shared Calendar You Both Trust
When your team is two people, missed meetings kill momentum fast. A shared calendar sounds basic, but it becomes the heartbeat of how you coordinate. Block time for deep work, flag investor calls, and mark deadlines where both of you can see them.
Google Calendar or Outlook Calendar will handle this fine. The key is making sure both founders actually put things in it. A calendar only works if it reflects reality, not just one person's version of the week.
One Place to Track Relationships
This is where most early teams get it wrong. You're emailing potential customers, talking to investors, following up with partners, and none of it lives in one place. Conversations fall through the cracks because they're scattered across inboxes, sticky notes, and half-remembered Slack messages.
You don't need a giant enterprise system for this. There are plenty of lightweight options among the best CRMs for early stage startups, and most of them do far more than a spreadsheet without the setup headache of an enterprise system. The point is to have a single source of truth for every relationship that matters to the business, whether that's a lead, a supplier, or a mentor you met at a conference last month.
Get this in place early. Rebuilding your contact history from scattered emails six months down the line is painful, and you'll lose things along the way.
Automation Glue to Connect the Gaps
Zapier, Make, or even basic built-in integrations will save you hours every week. The goal isn't to build some elaborate automation empire. It's to handle the small, repetitive tasks that eat into your day: logging form submissions, sending follow-up reminders, copying data between tools.
Start with one or two automations that solve an obvious pain point. A good first candidate is something like "when someone fills out our contact form, create a record in the CRM and ping us in our chat app." That alone removes a manual step you'd otherwise forget on a busy Tuesday.
A Single Home for Files
Dropbox, Google Drive, or OneDrive. Pick one. Share a folder structure. Done.
The mistake founders make is letting files live everywhere: some in email attachments, some on desktops, some in random Notion pages. When there are two of you, it takes about ten minutes to agree on a folder layout. Do it on day one and save yourself months of "where did that pitch deck go?"
Five Tools, Not Fifty
The pressure to adopt every new app is constant. Product Hunt will tempt you daily. But a two-person startup doesn't need a stack. It needs a spine: email, calendar, a CRM, automation glue, and shared files. Everything else is a distraction until you've outgrown these basics.
The founders who move fastest aren't the ones with the fanciest tools. They're the ones who picked five things, committed to them, and spent the rest of their time actually building.
The Tech Stack a Two-Person Startup Actually Needs was last modified: August 25th, 2026 by Shahid Shahzad
A recorded meeting usually feels useful right after it ends. Everyone remembers the discussion, the decisions, and the important points. The problem appears weeks later when someone needs to find one specific detail.
Maybe a product manager wants to confirm why a feature was postponed. Maybe a sales team needs the exact wording a customer used during an interview. Maybe someone remembers that an important decision was made, but nobody remembers which recording contained it.
The information still exists. It is just difficult to reach.
This is why many teams turn recordings into searchable text. A transcript does not replace the original video or audio. It creates another way to access the information inside those files.
A practical video and audio transcription workflow helps teams spend less time searching through recordings and more time using the information they already collected.
Why Recorded Information Becomes Difficult to Use
Most teams do not struggle because they lack information. They struggle because information is stored in formats that are difficult to search.
A one hour meeting recording may contain only a few sentences that matter. A customer interview may include one useful comment that influences a product decision. A training video may explain a process that someone needs months later.
Finding these moments by moving through a timeline is slow. People often remember the topic of a conversation but not the exact time when it happened.
Text changes this process. Once a recording becomes searchable, people can look for specific terms, review relevant sections, and return to the original file when they need more context.
The purpose of transcription is not to turn every recording into something people read from beginning to end. It is to make stored knowledge easier to find.
Turning Video Recordings Into Searchable Text
Video recordings often contain information that disappears after the first viewing. A meeting might be watched once, a product demonstration might be shared with one team, and an interview might stay untouched after it is completed.
The challenge comes later when someone needs to recover a specific detail.
A video to text converter can create a searchable version of the recording, allowing teams to locate important parts without manually watching the entire file again. A team can use a video to text converter to review long recordings, find relevant sections, and create notes based on the original conversation.
For example, a product team reviewing customer interviews may not need to watch every conversation again. They may first search the transcript to find repeated feedback, then return to the video to understand the speaker’s tone and the surrounding discussion.
The transcript helps people locate information. The original recording keeps the full context.
Working With Audio Recordings From Meetings and Interviews
Not every valuable conversation is captured as video.
Many teams collect information through audio files. These can come from customer interviews, podcasts, phone recordings, voice notes, or exported meeting recordings. The content may be useful, but finding a specific sentence inside a long audio file can be just as difficult as searching through video.
In these situations, teams often need to transcribe audio files and keep the written version connected to the original recording.
Audio transcription is especially useful when the main value is in the spoken conversation itself. A researcher may need to compare interview responses. A marketing team may want to review customer language. A manager may need to revisit a previous discussion before making a decision.
The transcript provides a practical reference, but unclear sections still need to be checked against the original audio. Names, numbers, and technical terms are easy places for mistakes to appear.
Keep the Original Transcript Separate From Team Notes
A transcript and a summary solve different problems.
The raw transcript keeps a record of the conversation. It allows people to check what was actually said when questions appear later. The working notes should focus on information that helps people move forward.
For example, after a product meeting, the transcript may contain the full discussion about different ideas, concerns, and possible solutions. The final team notes may only need the decision that was made, the person responsible for the next step, and the reason behind that decision.
Keeping these two documents separate prevents an important problem. Teams sometimes summarize a conversation too early and remove details that become useful later.
A customer interview is a good example. A short summary may mention that customers want a simpler workflow, but the original transcript may contain the exact words customers used and the situations that caused frustration. Those details can become valuable when creating product improvements or customer communication.
A useful habit is to keep the transcript, summary, and original recording connected. When someone needs more context, they can move from the written notes back to the source.
Review the Parts That Matter Before Sharing
Automatic transcription can save a large amount of time, but not every part of a recording has the same importance.
A small spelling mistake in a casual conversation may not matter. A wrong name, number, product term, or customer statement can create confusion if the transcript is later used for a decision or shared outside the team.
Most review work should focus on areas where accuracy affects the outcome.
For example, a sales team reviewing a customer call should pay attention to the customer’s requirements and specific feedback. A product team checking a meeting transcript should verify decisions and technical details. A researcher using interview transcripts should confirm quotations before publishing them.
The goal is not to manually correct every sentence. It is to make sure important information is reliable.
Common Problems Teams Face With Transcription
Transcription usually works well when the recording quality is clear, but real conversations are rarely perfect.
People speak at different speeds. Several speakers may talk at the same time. Some names, industry terms, or product names may not be recognized correctly. A poor microphone or background noise can also affect the result.
These issues do not make transcripts useless. They simply show where human review is needed.
When a sentence looks unclear, the safest approach is to check the original recording instead of guessing. A transcript should help people find information faster, not create false confidence about information that needs confirmation.
Speaker labels can also be useful for conversations with multiple people, but they should be reviewed before a transcript becomes an official record. Automated labels are helpful for navigation, but they are not always perfect.
Build a Simple Workflow Around Recorded Content
A transcription workflow does not need complicated systems or additional administrative work.
The most practical approach is usually simple. Keep the original recording, create a transcript, review the sections that will actually be used, and store the related files together.
The important part is consistency.
A team that records customer interviews every week will benefit from using the same naming style and storage method. A meeting from six months ago becomes much easier to find when the file name includes the project, date, and purpose instead of a name like Final Meeting Recording.
Over time, these small habits turn old recordings into a useful knowledge source instead of forgotten files.
When a Transcript Is Not Enough
Text makes recordings easier to search, but it cannot capture everything.
A video may show a product demonstration that requires visual explanation. An interview may include tone, hesitation, or reactions that change how a statement should be understood. A meeting may contain context that is difficult to represent in written form.
This is why the original recording should remain part of the workflow.
A transcript is most useful when people use it as a way to find information and then return to the source when accuracy matters.
Before publishing a quote, sharing customer information, or using a transcript for an important business decision, review the relevant section in the original recording.
Turn Existing Recordings Into Usable Knowledge
Many teams already have valuable information stored in recordings. The problem is that this information often stays hidden because finding it takes too much time.
A searchable transcript changes how people interact with recorded content. Instead of remembering when something happened, they can search for the topic and quickly return to the relevant moment.
This is useful for teams that regularly work with meetings, interviews, training materials, and customer conversations.
The value of transcription is not creating another file. It is making existing information easier to access when someone needs it.
Keep Human Judgment in the Workflow
A video and audio transcription process works best when automation handles the repetitive part and people handle the decisions.
A video to text converter online free can help create a searchable version of a recording quickly, while human review ensures that important information remains accurate.
The same principle applies to audio transcription. Tools can help teams process large amounts of spoken content, but the people who understand the conversation still decide what information matters.
The most reliable workflow is straightforward. Create a searchable transcript, check the sections that affect decisions, and keep the original recording available for reference.
Recorded conversations often contain knowledge that teams need later. A good transcription workflow simply makes that knowledge easier to find.
How Teams Turn Video and Audio Recordings Into Searchable Notes was last modified: August 25th, 2026 by Colleen Borator