How to Recover Deleted Photos From an SD Card: What to Try First

An SD card can hold hundreds of photos from a holiday, a family celebration or a photography project. Unfortunately, it only takes a moment to delete the wrong folder or format the card by mistake. Sometimes, photos may also disappear because of a card-reading error or an unexpected interruption while transferring files.

The good news is that deleted photos are not always permanently lost. In some cases, the data remains on the card until new information overwrites it. Acting quickly and avoiding unnecessary changes to the card can help preserve the possibility of recovery.

If you have lost important images, there are several things you can try before giving up. From checking backups to using recovery software, the right approach depends on what happened to the card and whether the missing files are still recoverable.
Can You Recover Deleted Photos From an SD Card?

Yes, it is sometimes possible to recover deleted photos from an SD card. When a file is deleted, the storage system may mark the space it occupied as available for new data rather than immediately removing every part of the file.

This means recovery software may be able to locate deleted images, provided the relevant data has not been overwritten or damaged.

However, recovery is not guaranteed. The chances depend on several factors, including how the photos were deleted, whether the card has been used since, and the condition of the storage device.

For example, accidentally deleting a few photographs and immediately removing the card may leave more recovery possibilities than continuing to take hundreds of new pictures on it.

The first step is therefore to stop using the affected card and work out which recovery method makes sense for your situation.

What to Do Before Recovering Deleted Photos

Before trying any recovery method, take a few simple precautions. They can help prevent an already frustrating situation from becoming more difficult to resolve.

1. Stop Using the SD Card

If you have accidentally deleted photos, stop taking new pictures or saving files to the card.

New data may overwrite the space occupied by deleted images, making them harder or impossible to recover. If the card is in a digital camera, switch the camera off and remove it carefully.

Avoid formatting the card again or attempting random fixes before checking whether recovery is possible.

2. Check Your Backups

Before installing recovery software, check whether another copy of the missing photos exists.

You might have transferred them to a laptop, uploaded them to a cloud storage service or copied them to an external drive. If the photos were imported into a photo management application, check there too.

Finding an existing copy is often simpler than recovering the original files from the card.

3. Check Whether the Files Are Actually Missing

Sometimes, photos appear to have disappeared because of a connection or reading problem rather than deletion.

Try connecting the SD card to another compatible card reader or computer. If the card is recognized, check its folders carefully.

If the computer asks you to format the card before it can be used, do not proceed if you need the data. Formatting can complicate recovery, so investigate other options first.

If the card is physically damaged or repeatedly disconnects, avoid repeated attempts to access it. Professional data recovery may be more appropriate when the images are particularly valuable.

How to Recover Deleted Photos From an SD Card

If you cannot find another copy of your images, you can try recovery software. The general process involves scanning the card, reviewing the results and saving any recoverable files to another location.

Step 1: Connect the SD Card to Your Computer

Use a compatible card reader to connect the SD card to your Windows PC or Mac.

Check whether the computer recognizes the card and whether it appears as a storage device. If it does, you can proceed to the recovery stage.

If the card is not recognized, try a different reader or USB port where appropriate. Do not repeatedly reconnect a card that appears physically damaged or behaves erratically.

Step 2: Choose a Photo Recovery Tool

Recovery software can scan storage devices for files that are no longer visible through the normal file browser.

One option to consider is Stellar Photo Recovery. Its software is designed for recovering lost or deleted media files, and its Free version lets users test the recovery process within defined limits.

You can explore Stellar’s Photo Recovery software to see whether it suits your recovery needs.

Before choosing a tool, check that it supports your operating system and the type of storage device involved. Also, review the free version’s limits so you know what to expect before starting.

Step 3: Select the SD Card and Scan It

Open the recovery software and select the connected SD card as the location to scan.

Follow the software’s instructions to begin searching for recoverable files. Depending on the card’s capacity and condition, the scan may take some time.

Avoid saving new files to the card while the process is underway. If the software offers different scanning options, consult its instructions to understand which one is appropriate for your situation.

Step 4: Review the Recoverable Photos

Once the scan is complete, examine the results and look for the missing images.

Some tools may allow you to preview detected files. Where that option is available, use it to check whether the images appear intact before attempting recovery.

Finding a file in the results does not always mean that the complete image can be restored successfully. The condition of the underlying data still matters.

Step 5: Save the Recovered Photos Somewhere Else

If the software finds the images you need, save them to your computer or another separate storage device.

Do not save recovered photos back to the same SD card during the recovery process. Using a different destination helps avoid overwriting data that may still be recoverable.

Once the files have been restored, open them to check that they work correctly. If the images are important, make an additional backup before reusing the original card.

What If You Accidentally Formatted the SD Card?

Formatting a memory card can make photos appear to have disappeared entirely, but recovery may still be possible in some circumstances.

The outcome depends on the type of formatting, what happened to the card afterwards and whether the underlying data remains intact.

If you formatted the card by mistake, stop using it immediately. Do not take new photographs or copy additional files onto it.

You can then try scanning the card with suitable recovery software. Depending on the circumstances, the scan may identify files that are no longer visible through the usual folder structure.

However, formatting does not guarantee that the data can be recovered. If the card has been reused extensively or the underlying data has been overwritten, some or all of the photos may be unrecoverable.

What If the Recovered Photos Will Not Open?

Sometimes, recovery software finds image files but the recovered photographs will not open correctly. This can happen when the file data is incomplete, corrupted or overwritten.

First, try opening the recovered copy with another compatible image viewer. If that does not work, check whether the recovery software provides additional scanning options or instructions for dealing with damaged files.

It is also worth checking whether another copy exists in a backup or on a different device.

If the recovered photos are corrupt or damaged and still will not open, you can also try photo repair software such as https://www.stellarinfo.com/photo-repair-software.php. It is designed to repair corrupt or damaged image files and can help restore photos that were successfully recovered but cannot be opened or displayed properly.

Can You Recover Photos From an SD Card for Free?

Free recovery options are available, although their capabilities vary.

Some tools allow users to scan a storage device and inspect the files they find, while others place restrictions on how much data can be recovered without a paid license.

Stellar Photo Recovery Free, for example, allows users to recover up to 10 photos, videos and audio files, with each file limited to 100 MB. This can be useful when you only need a few images and want to test the recovery process before purchasing a license.

However, the limit may not be sufficient if you are trying to restore an entire holiday’s worth of photographs or a large collection of camera images.

Before downloading any tool, check its current recovery limits and supported features. A free scan can help you understand what may be recoverable, but it does not guarantee that every missing photograph can be restored.

How to Prevent Photo Loss From Happening Again

Recovering deleted photographs can be possible, but prevention is less stressful than dealing with missing files in the first place.

A few simple habits can reduce the risk of losing important images.

  • Back up your photos regularly. Transfer important images to a computer, external drive or suitable cloud storage service.
  • Check before formatting. Make sure you have copied everything you need before formatting a memory card in your camera.
  • Use the camera’s deletion options carefully. Double-check the selected files before deleting images in bulk.
  • Transfer files before clearing the card. Open the copied images to make sure the transfer worked before removing the originals.
  • Handle memory cards carefully. Protect them from physical damage, moisture and extreme conditions.
  • Replace unreliable cards. If a card repeatedly produces errors or becomes unreadable, avoid trusting it with your only copy of important photographs.

For professional photographers or anyone taking lots of pictures, having more than one backup is particularly useful. A single memory card should not be the only place where irreplaceable images exist.

Is Recovering Deleted Photos From an SD Card Worth Trying?

If you have accidentally deleted important photographs, do not assume they are gone forever. Depending on what happened to the SD card, recovery software may be able to locate files that are no longer visible.

Start by stopping further use of the card, checking for backups and confirming whether the computer can recognise it. If the photos remain missing, a recovery scan is a reasonable next step.

Stellar Photo Recovery is one option to consider, particularly if you want to test recovery before committing to a paid licence. Its Free version has limits, so it is worth checking whether those fit the number and size of files you need to restore.

Ultimately, recovery depends on the condition of the card and whether the original data remains intact. Acting quickly, avoiding unnecessary changes and saving recovered files to a separate location can help you approach the process more carefully.

And once your photos are back, make a backup. It is a small step that can save you a great deal of trouble the next time a memory card decides to cause problems.
OpenOffice PDF Editor Alternative: What to Use Instead

I recently got a PDF contract with a few minor changes to two clauses. I needed to edit those before signing. I also didn’t want to pay to use Adobe Acrobat. So I used what I thought was the next best thing, OpenOffice.

Forty minutes later, I learned what the best thing to use OpenOffice is… Free Legal Advice.

After struggling to find a button to open the contract in OpenOffice, I found a plugin that allowed me to open the contract. However it opened in a different program. Again, I had to find a way to edit it to get the program to open the contract. After all that, the format was a disaster. The program obviously wasn’t meant to edit PDFs.

If you’re like me and thinking OpenOffice can do more with PDFs, it can’t.

Here are the things OpenOffice can do with PDFs. Then I’ll talk about more useful and powerful programs.

What OpenOffice Can (and Cannot) Do with PDFs

OpenOffice’s main applications are editor, Calc, and Impress. Editing PDFs isn’t part of the design.

What it can do:

  • After adding the PDF Import extension, you can use the OpenOffice application Draw to view PDFs.
  • You can edit things like spelling and repositioning text, but not delete text or change the font. You can’t make major changes.
  • You can export a PDF from each of the main applications. The export function works well.

What it cannot do:

  • Change the layout of a PDF.
  • It can’t merge PDF documents.
  • It can’t edit scanned documents, and for the same reason, it can’t edit most PDFs.
  • It can’t work with “tricky” PDF forms, and often crashes with PDFs that are not empty and have a single column.
  • Edit Hybrid PDFs. Apache has a case describing the feature as “practically unusable.”

Based on what the OpenOffice community and moderators say, you can’t really edit PDFs with OpenOffice. Moderators have said “OpenOffice cannot open PDF Files”, and other users have said “OpenOffice will not allow much reformatting”.

You can’t use OpenOffice to do what you want it to do. It will just cause more problems.

What People Are Actually Complaining About

I looked through the forums, bug reports, and posts to get a general consensus about the issues users are experiencing. The issues pertaining to PDF editing are as follows:

  • “Installing the extension opens the PDF in Draw and ruins the layout.”
  • “I can’t fill out the tax forms because the text keeps overlapping.”
  • “ Hybrid PDFs are no good because the edit mode is basically nonexistent.”
  • “I just want to be able to edit PDFs online without having to take a class on how to use your program.”

People are frustrated, and understandably so. However, people are frustrated for good reason. Users expect a word processing program to be able to perform word processing tasks. Therefore, users expect a program to be able to edit PDFs.

The Real Alternative: What a Dedicated PDF Editor Looks Like

If you’re tired of fighting with OpenOffice’s Draw workaround, it’s worth seeing what a purpose-built OpenOffice PDF editor alternative actually delivers.

I expected Draw to perform these functions after the fiasco I had with contracts.

After that experience, I expected Draw to be able to perform these functions. Instead, I received a negative experience and a lesson on the import/export function of word processing programs.

I decided to try UPDF after this experience. It is a superior program and performs native PDF editing functions. UPDF even performs OCR to make text in scanned PDFs editable.

Format conversion. The ability to convert PDFs to other formats is huge for remote workers. pdf files are highly universally used, but workflow can quickly become complicated when you don’t have the right file type.

AI features. The AI in UPDF lets you do things like take a snapshot of a long document to summarize it or translate PDFs. The AI lets you “chat” with a PDF to understand it, and it lets you interpret data visually. Remote workers usually don’t have the luxury of using cool, time-saving features like these.

Cross platform sync. Editing PDFs on your computer and then viewing the changes you made on your phone is convenient. CompanionLink users will find this feature particularly convenient.

If you want to see an example workflow of using a dedicated PDF editor over Open Office, you can see a detailed description here.

The Bottom Line

Editing PDFs in Open Office is very time consuming, and trying to do so will only lose you more time. Using Open Office for its native functions and a PDF Editor for PDF functions is the best way to ensure remote worker time is used efficiently. Using a PDF editor for remote work will almost always be a good use of your money.

How 3D Architectural Visualization Is Changing Real Estate Development in Dubai

Dubai’s property market is large enough that presentation quality can affect real commercial decisions. A 3d architectural visualization company in Dubai now works much earlier in the development cycle, often before a sales gallery, model apartment, or finished facade exists. The 3d rendering company in Dubai can help developers show kitchens, wardrobes, hospitality interiors, and branded residences before production begins. This shift matters because the market keeps expanding. Dubai Land Department reported more than 270,000 real estate transactions worth over AED 917 billion in 2025, a 20% year-on-year rise in value. At that scale, photorealistic visualization is no longer a decorative extra. It is a practical tool for explaining design intent, testing concepts, supporting sales teams, and giving buyers a clear picture of a property that may still be years from completion.

The Role of 3D Visualization in Off-Plan Sales and Investor Attraction

Off-plan property depends on trust because buyers commit to a home or investment before they can walk through the finished space. That makes photorealistic 3D renders, virtual tours, and interactive walkthroughs central to the sales process. Dubai Land Department recorded 132,500 off-plan project sales in 2025, showing how much of the market relies on pre-construction decision-making. International investors may compare several projects from another country, so they need visual material that explains scale, views, materials, layouts, and the relationship between private units and shared amenities. Some buyers start by comparing 3d visualization companies in Dubai to see how convincingly a project can be represented. Others look for a 3d visualizer company in Dubai that can produce consistent imagery across brochures, websites, sales galleries, and digital campaigns. Strong visuals do not replace due diligence, but they reduce uncertainty and make complex projects easier to understand remotely.

Modern Visualization Technologies Transforming Dubai Development

Property visualization technology has moved beyond static images. Developers now combine several formats so the same design data can support sales, planning, presentations, and stakeholder reviews. With 937 projects under construction in Dubai in 2025, according to the Dubai Land Department, scalable visualization workflows have practical value. A buyer may first see a still image, then explore a unit in real time, while the developer uses the same underlying model for internal coordination. Teams comparing 3d rendering services in Dubai increasingly expect this broader production range rather than a small set of hero images.

  • Immersive Virtual Reality (VR) and Augmented Reality (AR) walk-throughs let buyers explore rooms, terraces, amenities, and views at a human scale before construction is complete.
  • High-resolution 3D interior and exterior CGI rendering engines produce detailed materials, realistic daylight, landscaping, reflections, and furniture that can hold up across large-format marketing use.
  • Real-time digital twin technology can connect master-planned community models with live or simulated data, helping teams study assets, infrastructure, movement, and future operational scenarios.
  • Cinematic 3D animation reels and 360-degree interactive floor plans add movement and user control, making large developments easier to explain than a sequence of static plans.

This wider toolkit is one reason 3D rendering companies in Dubai are often involved across several stages of a project, rather than delivering only final marketing images.

Streamlining Design Approvals and Mitigating Construction Risks

Visualization also has a less visible role: it helps project teams find problems before they become expensive site issues. A detailed model can expose awkward sightlines, clashes between architectural elements, inconsistent facade modules, poor furniture clearances, or lighting choices that look different in context than they did on a material board. In complex developments, 3d rendering Dubai workflows can sit alongside BIM and technical coordination, giving non-technical stakeholders a clearer way to review proposed changes. The value is not that a render replaces engineering documentation. It does not. The value is that a realistic visual can make design consequences easier to spot and discuss. Firms working on 3d renderings for Dubai projects can also test alternative materials, daylight conditions, and landscape treatments before procurement. For municipal or client approvals, clearer visual evidence may reduce back-and-forth because the intended result is easier to understand before groundbreaking.

Marketing Luxury Lifestyles and Brand Identity in a Competitive Market

Luxury real estate is sold through atmosphere as much as area. Buyers want to understand how a penthouse feels at sunset, how a lobby frames arrival, or whether a villa’s interior language matches the promise of the brand. That is where 3D visualization Dubai work becomes visual storytelling. The strongest images control small details: the warmth of indirect lighting, the softness of fabrics, the density of landscaping, the view beyond the glazing, and the balance between architecture and furniture. This matters in a market where luxury investment remains substantial. Dubai Land Department reported AED 87.71 billion in luxury real estate investment in the first quarter of 2026, up 26% year on year. For developers assessing 3d architectural visualization companies in Dubai, consistent art direction is therefore as important as technical realism. Buyers are evaluating more than square meters. They are evaluating an expected lifestyle and the credibility of the brand presenting it.

Future Outlook of Architectural Visualization in the UAE

The next stage will be faster, more interactive, and more closely connected to property data. AI-assisted rendering workflows can already speed up concept variations, image cleanup, material exploration, and early-stage ideation, while real-time engines reduce the gap between a working 3D model and a client-ready experience. Firms competing under searches such as 3d rendering companies Dubai will need to combine visual craft with stronger data and automation skills. A 3d rendering company Dubai may increasingly deliver live configurators, dynamic unit views, and reusable digital assets rather than a fixed package of images. Even the awkward search phrase render dubai points to a broader demand for fast visual production across property, hospitality, retail, and infrastructure. This direction also aligns with Dubai’s Real Estate Sector Strategy 2033, which targets a 70% increase in transactions and a market value of AED 1 trillion while explicitly promoting AI, data centralization, and digital investor experiences.

Conclusion

3d architectural visualization in Dubai has moved from the edge of property marketing into the core development workflow. It helps buyers understand off-plan projects, gives international investors a more complete basis for comparison, and lets design teams communicate decisions before they reach the construction site. The same applies to architectural 3D visualization across Dubai for large master plans, where scale and complexity make clear visual communication especially useful. For sales teams, architectural rendering Dubai supports a consistent story across digital campaigns, brochures, sales centers, and investor presentations. For developers, it can reduce ambiguity around design intent and make revisions easier to evaluate. As Dubai continues to combine rapid development with a more digital real estate ecosystem, visualization will become more connected to live data, interactive tools, and AI-supported production.

Complete Guide to Outlook Errors: How to Diagnose and Fix Any Outlook Problem (2024)

Most Outlook troubleshooting guides throw random solutions at you without helping you understand what actually went wrong. You copy registry tweaks, rebuild profiles, and restart services—only to find the same outlook error messages appearing hours later. The problem? You never identified the root cause category.

Outlook errors fall into distinct families. Each family responds to specific fixes. Connection failures need different remedies than authentication blocks. Sync problems require separate approaches from display glitches. When you match the error type to the correct solution pathway, you solve outlook troubleshooting challenges in minutes rather than hours.

This framework-based approach saves businesses countless support hours annually. Instead of trial-and-error chaos, you will follow a diagnostic method that pinpoints exactly where Outlook is breaking down.

Understanding Outlook Error Types: How to Identify What’s Actually Wrong

Outlook errors announce themselves through several telltale patterns. Connection issues typically present timeout messages or “trying to connect” notifications that never resolve. Authentication problems display credential prompts that loop endlessly. Send/receive failures show specific error codes in the status bar. Display errors manifest as blank screens or garbled message formatting.

Start by observing when the problem occurs. Does Outlook fail immediately on launch? That probably signals an authentication or profile corruption issue. Does the application hang when you click “Send”? You might face a connection or server communication breakdown. Do certain folders refuse to populate? Synchronization mechanisms have likely failed.

Check the bottom-right status indicator. This small bar reveals critical diagnostic information most users overlook. “Disconnected” means network or server accessibility problems. “Send/Receive Error” points to mailbox communication failures. “Updating this folder” that never completes indicates sync conflicts.

The Microsoft Support site maintains an official error code reference. Numeric codes like 0x80040600 or 0x8004010F correspond to specific failure categories. Write down exact codes before attempting any fixes.

Connection and Network Errors: Symptoms, Causes, and Solutions

Connection failures account for roughly half of all outlook not working complaints. These errors stem from network interruptions, firewall blocks, or server communication breakdowns. Users see persistent “Trying to connect to server” messages or immediate disconnection warnings.

Begin with basic connectivity verification. Can you access other internet services? Test your browser and other cloud applications. If general internet access works fine, the issue lies specifically with Outlook’s server pathway.

Firewall configurations frequently block Outlook’s required ports. Corporate networks often implement aggressive security policies that prevent Exchange synchronization. Navigate to your firewall settings and verify that Outlook.exe has full network permissions. The application requires outbound access on specific ports depending on your mail server type.

VPN connections introduce additional complexity. Some virtual private networks route traffic through gateways that throttle or block email protocols. Try disconnecting your VPN temporarily. If Outlook immediately connects, your VPN configuration needs adjustment to whitelist Exchange traffic.

Cached Exchange Mode settings sometimes cause phantom connection errors. Navigate to File > Account Settings > Account Settings, select your email account, click Change, and verify that “Use Cached Exchange Mode” shows appropriate slider settings. Moving the slider to “All” ensures maximum offline capability but may trigger sync delays on slower connections.

Authentication and Login Errors: Fixing Credential and Access Issues

Authentication failures create frustrating loops where Outlook repeatedly requests passwords despite correct entries. These outlook authentication errors typically emerge after password changes, security policy updates, or credential store corruption.

Windows Credential Manager stores your Outlook passwords separately from the application itself. Corrupted credentials in this vault cause endless authentication loops. Press Windows Key + R, type “control /name Microsoft.CredentialManager” and examine stored credentials related to your email address. Delete any Outlook or Exchange entries, then restart Outlook to trigger a fresh authentication sequence.

Multi-factor authentication adds another failure layer. Organizations increasingly require MFA for email access. If you recently enabled MFA on your account, Outlook may need app-specific passwords rather than your regular credentials. Generate these through your email provider’s security settings portal.

Modern Authentication versus Basic Authentication creates compatibility conflicts. Microsoft has deprecated Basic Authentication for security reasons. If your organization still uses older Exchange servers, you might need registry modifications to force Modern Authentication protocols. Consult your IT department before making authentication method changes.

Resolving Repeated Password Prompts

Persistent credential requests often indicate profile corruption rather than actual authentication failures. Create a new Outlook profile through Control Panel > Mail > Show Profiles. Add your email account to this fresh profile. If authentication succeeds in the new profile but fails in the old one, profile corruption was the culprit.

Send/Receive Errors: Troubleshooting Email Delivery Problems

Outlook send receive error messages prevent critical business communication. These failures may affect outgoing messages, incoming mail, or both directions simultaneously. Error codes in this category often reference mailbox quota limits, attachment size restrictions, or server timeout issues.

Mailbox size limits trigger the most common send/receive failures. Organizations impose storage quotas on Exchange mailboxes. When you approach or exceed these limits, Outlook cannot receive new messages. Check your mailbox size by right-clicking your mailbox root folder and selecting Data File Properties. If you are near the quota, archive old messages or delete large attachments.

Attachment size restrictions cause outgoing message failures. Most mail servers limit individual message sizes to around 20–25 MB. Attempting to send larger files generates cryptic error messages. Use file-sharing services for large documents rather than direct email attachments.

Stuck messages in the Outbox folder create persistent send errors. Navigate to your Outbox and check for messages with large attachments or unusual formatting. Delete or move these stuck items. Sometimes a single corrupted outbound message blocks the entire send queue.

Display and Rendering Errors: Resolving Message and Interface Issues

Display problems range from blank message bodies to completely unresponsive interface elements. These outlook error codes often relate to add-in conflicts, graphics driver issues, or data file corruption.

Start Outlook in Safe Mode to bypass add-in loading. Hold the Ctrl key while launching Outlook, then confirm Safe Mode startup. If display problems vanish in Safe Mode, a problematic add-in causes the issue. Disable add-ins one by one through File > Options > Add-ins to identify the culprit.

Graphics acceleration features sometimes conflict with specific video drivers. Navigate to File > Options > Advanced and scroll to the Display section. Check the box for “Disable hardware graphics acceleration” and restart Outlook. This forces software rendering which resolves many display glitches.

Synchronization Errors: Fixing Calendar, Contacts, and Folder Sync Problems

Sync failures prevent calendar appointments, contact updates, and folder changes from propagating correctly. Users miss meetings because calendar invitations never appear. Contact modifications vanish mysteriously. Folder hierarchies show phantom items or missing subfolders.

Person sorting documents in folders outdoors, hands visible, neutral tone.

The Sync Issues folder holds diagnostic gold. Expand your mailbox folder list and look for the Sync Issues folder (you may need to enable it through Folder tab > Show All Folders). This hidden location contains Conflicts, Local Failures, and Server Failures subfolders. Review recent sync error logs to identify patterns.

Forcing manual synchronization often clears transient sync problems. Right-click your mailbox root folder and select “Update Folder.” For comprehensive resyncing, use the Send/Receive tab and click “Update Folder” for each problematic folder individually.

Calendar sync problems frequently stem from delegate permission conflicts. If multiple people manage a shared calendar, permission overlaps create sync loops. Review calendar sharing settings under Calendar Permissions and ensure clear ownership hierarchies exist.

Preventative Maintenance: Configuration Tips to Minimize Future Errors

Proactive configuration reduces common outlook errors dramatically. Regular PST file maintenance prevents data corruption. Schedule monthly archive operations to keep your primary mailbox lean. The IRS recommends retaining business email for specific periods, so balance archiving with compliance requirements.

Keep Outlook updated through Windows Update or Office Update mechanisms. Microsoft releases patches addressing known error conditions monthly. Enable automatic updates to receive fixes without manual intervention.

Monitor add-in accumulation. Each installed add-in increases crash probability and performance degradation. Audit your add-ins quarterly and remove anything you no longer actively use. Productivity tools you installed months ago may now cause more problems than they solve.

Create profile backups before major changes. Export your Outlook settings and autocomplete data periodically. When profile corruption strikes, restoration from backup takes minutes versus hours rebuilding from scratch.

Ready to eliminate outlook troubleshooting guesswork permanently? Bookmark this diagnostic framework and share it with colleagues who struggle with mysterious Outlook failures. The next time an error appears, you will know exactly which category to investigate and which solutions actually address root causes rather than symptoms.

Why Independent Agencies Are Ditching Legacy DSPs for an Agile Programmatic Platform

The days when giant network agencies and walled gardens could completely corner the media buying market are pretty much over. For years, independent agencies were stuck playing a rigged game, forced to use rigid legacy platforms built for massive brands with bottomless budgets. But that trade-off just doesn't make sense anymore. Today's indies can't afford to burn client money on hidden tech taxes, obscure algorithm black boxes, or absurd spend minimums that eat up margins. Clients are asking tough questions about where every dollar goes, and "trust the algorithm" isn't a valid answer anymore. To stay profitable and keep up with how fast digital culture actually moves, sharp media teams are quietly cutting ties with clunky enterprise software. They’re rebuilding their stacks around flexible, API-driven tools where they actually own their data and control their own strategy.

A stack of classic black and white photographs showcasing family memories and history.

The Legacy Trap: How Outdated Tech Throttles Agency Growth

Let’s be honest: those old-school DSPs promised to be all-in-one powerhouses, but they’ve turned into giant operational headaches. They operate as completely opaque black boxes. You often get limited visibility into bid shading logic, supply chain costs, and log-level data – unless, of course, you're willing to pay extra for access to your own campaign info. For an independent agency, that kind of opacity becomes a serious commercial risk when a client demands an audit. On top of that, basic campaign management feels stuck in 2012. Media traders still spend too much time adjusting pacing, checking performance across different dashboards, and pulling data into Excel. Throw in aggressive spend minimums – which force smaller agencies to take on significant financial risk just to keep the lights on – and the whole setup starts looking like a trap. When you want to test a niche contextual vendor or bring your own first-party data, these legacy tools can quickly become restrictive. Instead of serving your team, a rigid programmatic platform from the last decade ends up dictating how you run your entire agency business.

The Modern Stack: What Indies Demanded, Modern Tech Delivered

Today’s ad tech isn't built to lock you into a proprietary ecosystem. Instead, it’s modular by design – it pipes directly into your current tech stack without throwing your daily workflow into chaos.

  • Composable Architecture (API-First): The platform plugs into your existing CDP, attribution tools, and creative systems through APIs. You keep your existing stack instead of rebuilding your workflow around another closed platform.
  • Radical Transparency: You get the raw log-level data without extra fees or artificial delivery delays. That means you can see the bids, supply costs, and where the media budget is going.
  • Agentic AI & Direct Supply: AI-driven optimization can go beyond basic rules and optimize for CPA, ROAS, and incremental conversions to drive actual profit instead of just chasing CTR.

Winning on Agility: The Strategic Advantage for Independent Agencies

Ditching legacy platforms isn't just about getting better software – it is a direct growth strategy. Independent agencies don't try to beat big network holdings on headcount; they win because they move faster, adapt quicker, and build real relationships with their clients.

When you strip out the hidden fees buried deep in legacy supply chains, that money goes straight back into working media. Campaigns perform better, and your margins become easier to protect. Automated pacing and AI-assisted execution take care of the soul-crushing manual data-wrangling, freeing up your buyers to actually think about high-level media strategy. Above all, being upfront about costs keeps clients around. When you lay out raw spend logs and back up performance with clean numbers, you don't have to constantly pitch your value – the proof is right there.

A Buyer's Checklist: Evaluating Next-Gen Platforms

Switching ad tech hurts, but holding onto dying software costs way more and drains agency resources. Before you lock into a new deal and risk your margins, test vendors on these core points:

  • Open Integration: Does the platform connect natively to your existing stack through open APIs, or do you have to keep its data and reporting separate in yet another isolated silo?
  • True Data Ownership: Do you get free access to raw log files, or is the vendor charging you extra just to audit your own spend?
  • No Heavy Commitments: Does pricing scale cleanly with your volume, or are you locked into aggressive monthly minimums regardless of spend?
  • Actionable Automation: Does the platform’s AI actually handle complex, real-time optimization, or is it just a glorified rule script with a fancy marketing label?

The Shift Is Here

The exodus from legacy DSPs isn't a temporary trend; it's a permanent shift in how independent agencies operate. As the digital media ecosystem fragments even further and advertisers demand absolute financial accountability, relying on slow, closed-off tech is a quick path to losing your best accounts. Programmatic growth now belongs to small, fast teams backed by transparent tech and automation. Upgrading your stack does more than lower software bills – it gives you the speed needed to take market share from slow-moving giants.

Reduce Latency by Optimizing NVMe Clock Frequency for RTDB

Live database synchronization is one of the most challenging engineering problems of current IT architecture. In cases where on-premise CRM synchronization with cloud versions, distributed transactional logs or local application cache synchronization with central databases are involved, the margin of latency is counted in milliseconds. With any delay present, race conditions, merge conflicts, locks and stale data spread become the problem.

With a drop in performance, system administrators automatically tend to install additional memory and raise vCPU quotas. However, live synchronization pipeline does not generally suffer from memory shortages or lack of cores. The physical limits that determine the speed of real-time synchronization are the clock speed of CPU and NVMe storage subsystem performance.

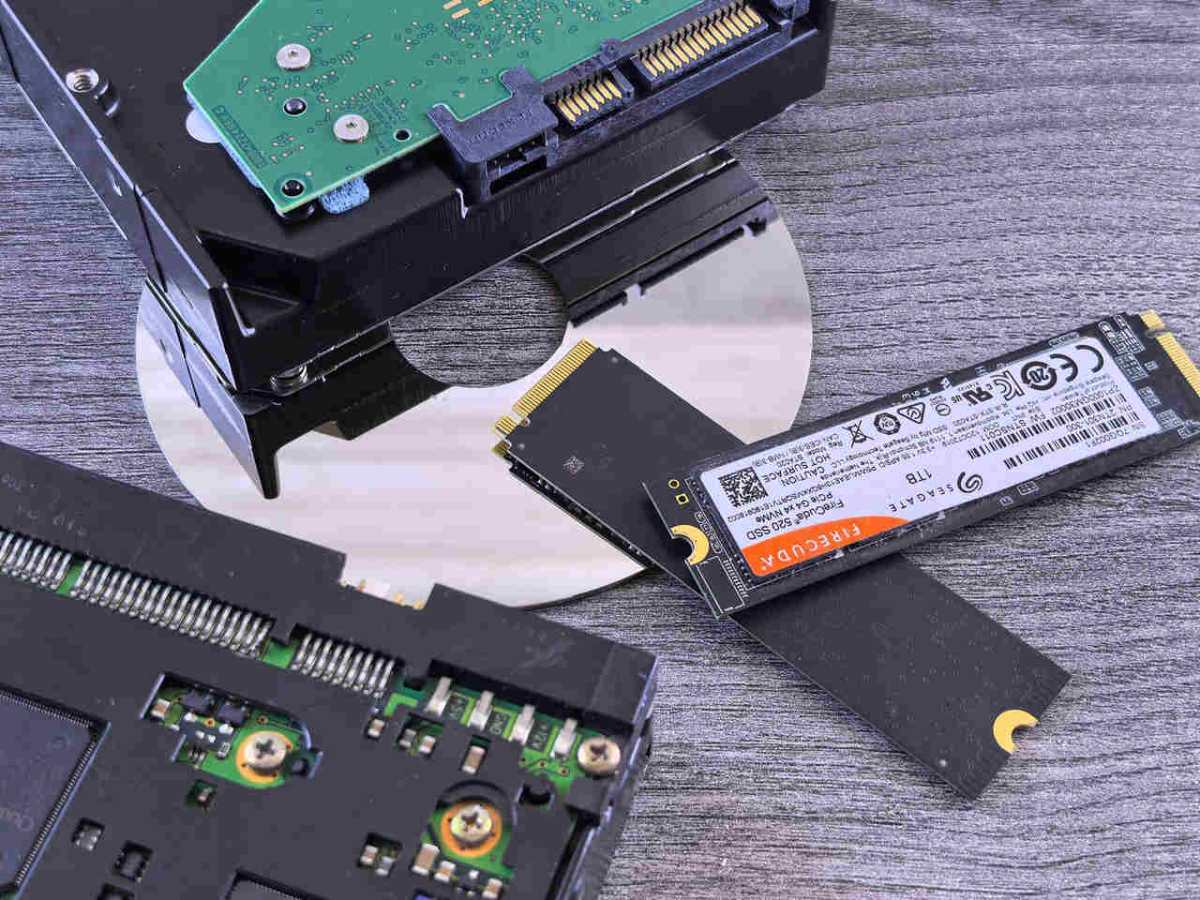
Contrasting data storage technologies: NVMe SSD, HDD, and CD.

Anatomy of a Synchronization Problem

To explore how hardware architecture defines synchronization efficiency, one should think about the process chain of the live two-way synchronization. In case when modification occurs on Node A and then it syncs with Node B, the database engine should perform the following actions:

  • Receiving payload via the network socket.
  • Processing delta and applying the rules of schema.
  • Obtaining appropriate row or table locks.
  • Processing conflict-resolution logic using local timestamps or version vectors.
  • Applying transaction to the Write-Ahead Log (WAL).
  • Committing the transaction to storage and releasing the lock.
  • Returning state message back over the network socket.

Although network transmission defines the base level of latency, the processing throughput defines whether the incoming transactions will be queued or immediately processed. Operations 2, 3, and 4 depend on the single-core CPU performance, while operations 5 and 6 are completely storage-dependent.

Why High-Core Count Doesn’t Work for Single-Threaded Processing

The most frequent mistake in the process of sizing the virtualization is the assumption that all the processing power is equal. Eight cores on a processor with the base clock speed of 2.0 GHz provide nearly identical theoretical aggregate processing power as a four-core processor with the clock speed of 4.0 GHz. Real-time database synchronization will favor the 4.0 GHz variant.

Pipeline PhasePrimary Hardware BottleneckOperational Impact Under Load
Delta IngestionNetwork Bandwidth & LatencySockets buffer incoming packets if downstream compute threads stall.
Logic & Row LocksCPU Clock Speed (GHz / IPC)Single-thread bound. Low clock speeds increase lock-hold duration, stalling other connections.
Journal PersistenceNVMe Latency ($QD \le 4$)Slower fsync() log flushes force the CPU into high %wa idle wait-states.
State CommitNVMe IOPS & BandwidthSaturated disk controllers cause write queues (await > 2ms) and replication drift.

Database engines ensure the replication process in the background in many worker threads. But particular processes involved in transaction processing, i.e., acquiring row locks, latching, and Write-Ahead Log serialization, happen sequentially. One worker thread should acquire a lock and determine the lack of conflicts before increasing the Log Sequence Number (LSN).

If there is not enough CPU clock frequency:

Lock hold time grows

The lower the clock rate, the longer it takes to calculate the algorithm for resolving conflicts. In case thread A holds the row lock for extra 400 microseconds, thread B should wait in an idle spinlock or sleep mode.

Instruction latency grows

High single-core instructions per cycle (IPC) and high clock rates prevent microcode execution time and guarantee that all deltas have been evaluated before buffer saturation.

More Than IOPS, Latency and Bandwidth Matter

As the CPU works on incoming data, storage write speed defines when the commit gets finalized. Conventional mechanical disks and old-school SATA SSDs face challenges in terms of real-time synchronization due to bandwidth/queuing limitations.

There are two types of physical storage requirements involved in database synchronization:

Low Queue Depth for Sequential Writes (WAL Commit)

In order to preserve the ACID principle, particularly the durability requirement, the database engine cannot acknowledge the transaction before flushing it to non-volatile storage using fsync() or fdatasync() function calls. Transactions are committed in series, and thus the disk queue depth is very low (QD = 1 – 4). The high-speed NVMe disk connected through PCI-E channels can provide microsecond write latency times which cannot be achieved by legacy SATA disks.

High Bandwidth Throughput for Bulk State Reconciliation

While live incremental sync depends on latency-reducing micro-writes, bulk seeding, snapshot creation, and disaster recovery reconciliation require massive sequential bandwidth. When dealing with millions of records, transmitting gigabytes of logs through the PCIe Gen 4 or Gen 5 links removes any limitations from the storage controller and ensures that the available network bandwidth is the sole bottleneck.

Using synchronization engines in multi-tenant cloud setups requires assessment of the hardware oversubscription. In case the hypervisor over-subscribes the storage I/O or limits the physical cores usage, write stalls become apparent instantly. Finding an optimal high-performance VPS ensures the isolated CPU clock ticks and unrestricted access to NVMe required to avoid CPU steal and storage queue saturation by the hypervisor.

Detecting Hardware Starvation

Prior to optimizing synchronization code or database parameters, perform diagnostics to determine whether there is any starvation in the hardware layer:

Diagnostic MetricCommand / UtilityHealthy BaselineBottleneck Indicator
I/O Wait Timetop / vmstat 1 (%wa)< 2.0%Persistently > 5.0%
CPU execution threads are stalled in an idle wait-state awaiting storage commit/flush completion.
CPU Steal Timetop (%st)0.0%> 1.0%
The host hypervisor is oversubscribed and starving virtual cores of scheduled clock cycles.
Disk Await Timeiostat -xz 1 (await)< 1.0 ms (NVMe)Spikes > 5.0 ms
The storage controller, PCIe bus, or drive write queues are saturated.
Lock Wait TimeDatabase Engine Stats
(e.g., pg_stat_activity, sys.innodb_lock_waits)
Workload-dependentSpikes during low total CPU usage
Serialization routines and row-level locks are waiting on single-thread execution speed (clock frequency).

Physical Infrastructure Requirements for Real-Time Synchronization

To ensure consistent and timely synchronization of production databases, ensure your server architecture meets these physical infrastructure requirements:

High Single-CPU Turbo is Better Than Many Cores

As far as the replication targets and synchronization points are concerned, hosting the workload on a dedicated High-Performance VPS that utilizes the contemporary CPU micro-architecture will ensure high single-CPU turbo frequencies of 3.5 GHz base with up to 4.5 GHz turbo, instead of going for budget solutions with many threads and lower frequency.

Use NVMe Partitions for Database Journals

Ensure you use a separate partition to store the Write-Ahead Log and the database tree structure. This ensures that you can isolate your journal write processes from general application disk I/O and avoid situations where your synchronous commits get queued up.

Assess Virtualization Overheads

In virtualized environments, confirm that the host guarantees consistent CPU scheduling. Where you find that your synchronization lags are caused by random bursts rather than sustained pressure, it means that CPU steal and storage noisy neighbor are to blame.

Close-up of hands pressing chess clock during an intense board game session.

When you synchronize the reality of real-time synchronization, serialized locking and disk flushes, with fast CPUs and efficient NVMe storage systems, your transaction backlog will be eliminated.

Why Virtual Workspaces Improve Technology Accessibility Across Different Geographic Locations

A designer in New York opens the same project that a developer in another country was editing ten minutes earlier. One is on a powerful workstation, the other on an older laptop, yet both need the same applications, files and speed to keep work moving.

That is where traditional workstation thinking starts to break down. When important tools live only on individual devices, geography becomes an IT problem. Virtual workspaces change that by keeping the working environment centralized while approved users reach it remotely.

The virtual workspaces benefits go beyond convenience. You get more consistent access to technology, simpler collaboration, easier management and greater flexibility when your team is spread across offices, homes, cities or countries.

So, let us study it in detail by reading the guide given below:

A man in an office environment using a virtual reality headset, engaging with VR content.

Geography Gets Expensive When the Computer Travels With the Employee

The more locations your team works from, the harder it becomes to keep every device equally capable. One office may use newer systems while another relies on older hardware and different software. That creates duplicated work. Instead of managing one environment, your IT team maintains several versions of the same workspace.

Virtual workspaces reduce that problem. Employees still need a device and stable internet, but important computing happens centrally rather than on each machine.

The Real Upgrade Is Separating the Workspace From the Device

Your laptop becomes the access point, not the place where every application and file has to live. Think of it as a window into the workspace rather than the workspace itself.

A virtual environment can hold:

  • Business software and internal tools
  • Files, configurations and user settings
  • Processing power and storage resources
  • Access permissions for different team members

It gives people a consistent setup across different devices and can simplify onboarding by avoiding a full workstation rebuild for every employee.

Accessibility Is Really About Making Location Less Important

Virtual workspaces reduce how much physical location controls what technology you can use. You may be working from a main office, home, another city or an international branch. If the workspace is centralized, you can reach the same applications and files without carrying the same physical computer everywhere.

That is especially useful for distributed teams that need one dependable setup across several locations. If you want to understand the remote-access side more closely, this guide explains how Windows RDP supports secure remote access and why the connection setup matters when accessing a remote workspace.

Access From Anywhere Means Little If the Environment Goes Offline

Remote access only helps when the systems behind it remain available. If your team depends on one workspace, you need a plan for hardware failure or service interruption.

A practical continuity plan should answer:

  • Where are backups stored?
  • How quickly can systems be restored?
  • Who handles recovery?
  • Can employees regain access another way?

You do not need an oversized recovery setup. You need to know how important it is for systems to return online before an outage happens.

The goal is continuity, so one infrastructure failure does not cut off your team.

Centralizing the Workspace Can Simplify Control

A virtual workspace gives your IT team one main environment to manage instead of relying on many separately configured devices. User permissions, updates, settings and access rules become easier to manage consistently. Employees still need strong passwords, trusted devices and safe login habits.

If someone leaves, you can remove workspace access without wondering what business files remain on a local machine. This centralized control is one of the practical virtual workspaces benefits for businesses managing people across several locations.

The Server Location Still Shapes the Experience

Virtual workspaces make employee location less restrictive, but the quality of the remote environment still matters. Your team needs enough processing power, memory, storage and network capacity to keep applications responsive. The operating system and level of administrative access should also fit the work being performed.

For businesses that need a Windows-based remote environment without building a separate physical workstation for every user, a cheap Windows RDP can provide another practical way to access applications and files remotely. The important part is matching the resources to your actual workload rather than choosing on price alone.

Virtual Does Not Mean Geography Disappears Completely

A virtual workspace cannot fix poor local internet, undersized servers, long network routes or weak security. Those issues can still affect remote work.

Geography still matters. The advantage is that it no longer decides which employee gets access to capable technology.

Technology Should Follow the Worker, Not the Other Way Around

Virtual workspaces improve technology accessibility because they separate the tools you need from the physical machine in front of you. Teams in different locations can reach a more consistent environment without every office or employee needing identical hardware.

The strongest virtual workspaces benefits appear when that accessibility is backed by reliable resources, secure access, responsive connectivity and an environment designed around the work your team actually performs.

The smartest approach is not simply moving everything online. It is centralizing the workloads that benefit from shared access and supporting them with infrastructure that matches where your people actually work.

A modern workspace featuring a laptop, books, and ambient lighting for a productive environment.

If you are building a reliable US-based virtual workspace, explore DashRDP’s dedicated server options and buy RDP online based on the resources you need for your real workload.

Microsoft 365 Tenant to Tenant Migration After a Merger or Acquisition

When two companies merge or one acquires another, IT rarely gets a slow, careful timeline. Exchange environments need to be consolidated fast often across different Active Directory forests, mismatched Exchange versions, or entirely separate Microsoft 365 tenants while the business keeps running. Here's what makes these migrations different, and how to approach one without losing data or missing your deadline.

Modern apartment building with balconies against clear blue sky. Urban architecture scene.

Why M&A Migrations Are Different

A standard Exchange migration moves mailboxes from one environment to another in a fairly linear way. A merger or acquisition adds several layers of complexity on top of that:

  • Two separate identity systems. You're usually reconciling two Active Directory forests, or two independent Microsoft 365 tenants not just moving mailboxes within one environment.
  • Compressed timelines. Migration schedules are often set by legal or deal terms, not by what's technically comfortable for IT.
  • Naming conflicts. Duplicate domains, overlapping user principal names (UPNs), and mailboxes with identical or near-identical display names are common when two organizations combine.
  • Immediate compliance obligations. Legal holds, data retention policies, and regulatory requirements frequently need to apply from day one post-close, not after migration wraps up.

These four factors are what separate an M&A migration from a routine one, and they're also why generic migration playbooks tend to fall short most weren't written with two colliding identity systems in mind.

Common Scenarios

Full absorption. The acquiring company's Exchange environment absorbs the target company's mailboxes, users, and data entirely. This is the most common pattern and usually the most straightforward, since there's a clear "source" and "destination" from the outset.

Tenant-to-tenant consolidation. Both companies already run Microsoft 365 and keep separate tenants for a transition period, then consolidate into one tenant once other integration work branding, licensing, security policy alignment is complete. This scenario is becoming more common simply because more organizations are cloud-first before a deal even happens.

Divestiture (the reverse case). A company splits into two, and one Exchange environment needs to be separated into two independent ones the mirror image of a merger migration, but with the same underlying complexity around identity, permissions, and data ownership.

The Core Challenge: Mailbox Mapping and Conflicts

Before transferring any data, both source and target should be inventoried, namely, mailboxes, Exchange versions, Active Directory forest/domain architecture, and any public folders or shared mailboxes at both sites. The following step, where M&A migrations fail in most cases, involves solving the problem of naming collisions and mapping the mailboxes correctly.

Duplicate UPNs or display names are common when two companies combine; a "J. Smith" on one side and another on the other, or overlapping domain naming conventions. Sorting this out with a spreadsheet and manual entry works for a handful of mailboxes, but it doesn't scale to hundreds or thousands, and errors here mean data lands in the wrong mailbox; a mistake that's far more consequential in an M&A context, where legal and compliance teams are often watching the process closely.

Manual PowerShell Migration vs. a Dedicated Tool

Native tools and PowerShell scripting can technically handle cross-forest migrations, but they weren't built with M&A-specific problems like resolving duplicate identities across two AD forests as a primary use case. Each script needs to be written and tested against the specific environment, which eats into a timeline that deal terms have already compressed.

This is where a dedicated Exchange migration tool becomes worth evaluating as an alternative. Stellar Migrator for Exchange, for example, is built specifically to handle cross-forest and cross-domain migrations without requiring custom scripts. Here's how the two approaches compare on the factors that matter most in an M&A timeline:

FactorManual / PowerShellStellar Migrator for Exchange
Cross-forest / cross-domain supportRequires custom scripting and testingBuilt-in, automated
Mailbox matching after mergerManual mapping, error-prone with duplicate namesAuto-match by name, or CSV import for bulk mapping
DowntimeOften requires cutover windowsZero-downtime supported
Handling failed or partial migrationsManual retry, risk of duplicating already-migrated dataRe-runs only failed or incomplete items
Timeline under deal pressureSlow — heavy on script writing and testingFaster to deploy, no scripting required
Migration types supportedDepends on scripts writtenCutover, staged, and hybrid, plus cross-domain
Direction flexibilityCustom-built per scenarioHandles on-prem-to-cloud, tenant-to-tenant, and reverse migrations

While the manual process is not entirely unattainable, many IT departments have performed cross-forest migrations using only built-in utilities before. However, it is unlikely that the M&A process will allow for the development and testing of custom PowerShell scripts based on the specifics of the new environment. The special tool automates the mailbox matching process by comparing names or allows loading the CSV file for assigning mailboxes, taking into account that in M&A situations everything does not always work smoothly on the first attempt and therefore only those mailboxes or items which were not processed during the initial migration cycle need to be retried.

All of this doesn't replace the need for initial planning, such as environment inventory and name conflict resolution, which must be done before scripting can proceed, but it eliminates the bottleneck involved in manually performing these steps.

Step-by-Step: Migrating Exchange Post-Acquisition

  • Inventory both environments. Document mailbox counts, Exchange versions, AD forest/domain structure, and any public folders or shared mailboxes on both sides. This step alone often surfaces the naming conflicts and version mismatches that will shape everything downstream.
  • Resolve naming conflicts and build the mailbox mapping. Identify duplicate UPNs or display names before migration starts, and build an explicit source-to-target mapping a CSV-based mapping keeps this accurate at scale and gives you an auditable record, which matters if compliance teams need to sign off.
  • Choose the right migration path. If both organizations are on-premises, this is typically a cross-forest, same-tenant migration. If both are already on Microsoft 365, this becomes a cross tenant migration instead. Getting this decision right early avoids rework later.
  • Migrate in batches with incremental sync. Relocate mailboxes in chunks that can be managed effectively instead of doing them all at once. Delta synchronization ensures that mailboxes remain synchronized with incoming mails until the last phase of migration. This way, the impact on users is reduced significantly.
  • Validate and decommission. Confirm mailbox data, folder structures, and permissions transferred correctly, then retire the redundant environment. This is also the point to close out any temporary coexistence configuration between the two environments.

Bottom Line

M&A migrations succeed or fail on the planning stage inventory, conflict resolution, and mapping more than on the tool used to execute them. But once that groundwork is done, the execution phase is where manual scripting tends to slow teams down against deal timelines. The real deciding factor on whether or not the move will go well is whether or not you resolve name conflicts prior to the actual migration process and incrementally synchronize data as opposed to synchronizing everything at one go. The bottom line of the comparison is that the amount of time you have as per your deal terms plays a decisive role here along with the level of risk you are comfortable taking on the scripting front.

Top 10 Benefits of Staff Augmentation Services

Key takeaways

  • The strongest case for staff augmentation isn’t any single benefit on this list. It’s how many of them stack on top of each other inside the same hiring decision.
  • Cost savings show up fastest, but they’re rarely the reason a team keeps using the model past the first engagement.
  • Most of the value depends on treating the engagement as an extension of the team rather than a transaction.
  • A handful of these benefits only appear after several months, well past the first placement.

Two realistic paths exist when a 10-person product team needs 3 specialized engineers inside 6 weeks: stretch a standard hiring process past its limits, or bring in help built for exactly that timeline. Most teams that have tried the first path once don’t try it again. Below are 10 concrete benefits, each traceable to a specific mechanic of how staff augmentation services work, rather than a single generic pitch.

An IT staff augmentation company earns its place in a hiring plan by solving problems a standard recruiting funnel structurally can’t solve, regardless of price. The 10 benefits below are ranked roughly in the order most teams notice them, starting with the one that shows up fastest.

None of these benefits require a company to abandon direct hiring altogether. Most engineering leaders who use this model well run it alongside a direct hiring pipeline rather than in place of one, reaching for each approach where it fits the problem in front of them.

1. Faster access to specialized engineers

Sourcing, screening, and reference checks happen against a pool a provider already knows, rather than starting a search from zero. A role that would take a standard funnel 8 to 10 weeks to fill often closes in 2 to 3 weeks instead, since the vetting work has already been done ahead of the request. Across the 500-plus engineers we’ve placed since 2017, that head start is consistently where most of the time savings comes from. Cutting a step of the vetting process short isn’t.

Staff augmentation services close this gap specifically because the sourcing overhead is already sunk before a client ever submits a request. That head start is the single biggest reason the model gets reached for first when a timeline is the binding constraint.

The speed advantage compounds when several roles need filling at once. A recruiting function sized to close 2 or 3 roles a quarter doesn’t suddenly handle 8 without either slowing every search down or lowering its bar, while a provider built for volume treats that same request as routine.

2. Spend that scales with the actual need

An IT staff augmentation company bills like a service rather than a payroll line, which means the cost tracks the engagement instead of sitting on the books as a fixed headcount commitment. A team that needs a burst of capacity for one quarter isn’t stuck carrying that cost once the quarter ends.

That flexibility runs in both directions. An IT staff augmentation provider that’s priced correctly makes it just as easy to scale a team down in a slow quarter as it is to scale one up in a busy one, without either move triggering a layoff or a hiring freeze. A finance team that understands this upfront tends to approve the spend faster than one that discovers the billing model halfway through a budget cycle.

3. A dedicated team built around one roadmap

Rather than splitting a contractor’s attention across several clients, good dedicated development team services work exclusively on one company’s roadmap, reporting into that company’s own leads the same way an internal hire would. The engineers show up to the same standups, work off the same backlog, and carry the same context week over week.

That exclusivity is what separates a true dedicated team from a shared contractor pool. A team split across 5 clients simply can’t build the same depth of product context as one working a single roadmap full time.

Product context is the part that’s easiest to underrate going in and hardest to replace once it’s built. An engineer who has spent a year on one codebase catches edge cases and history a brand-new hire, internal or external, simply hasn’t had the chance to learn yet.

4. Headcount that moves with the roadmap

A provider offering IT staff augmentation services that’s built for volume can add engineers to a growing initiative or wind a team back down once a project ships, without the client managing a hiring freeze or a layoff to get there. That flexibility matters most exactly when a roadmap shifts unexpectedly, which is most of the time.

Direct hiring rarely offers that same elasticity. A team that hires 5 engineers to cover a 6-month push either finds new permanent work for all 5 once the push ends or manages an awkward conversation about headcount it didn’t plan for at signing.

5. Less recruiting and HR overhead carried in-house

IT resource augmentation services fold sourcing, payroll, benefits administration, and local compliance into the engagement itself, which means an internal recruiting function isn’t stretched thin covering roles that a specialized partner already handles end to end. That freed-up capacity usually goes straight back into the searches only an internal team can run.

Legal and compliance work in particular is where IT resource augmentation services save the most invisible time, since payroll and employment law across multiple regions is rarely something an internal HR team wants to own directly.

That overhead doesn’t disappear when a company hires directly in a new region. It just moves onto someone’s plate internally, usually without anyone budgeting the hours it takes to stay current on a second or third country’s employment rules.

6. A team built without a local entity

A company expanding into a market where it has no legal entity yet can still hire a dedicated software development team there, since the provider handles the local employment relationship. Waiting on entity paperwork before hiring the first engineer in a new region can cost months a growing roadmap doesn’t have.

This benefit matters most for market-entry timelines specifically. A company testing demand in a new region rarely wants to commit to setting up a full legal entity before it even knows whether the market is worth the investment, and building a team there without that commitment keeps the option open either way.

7. Access to talent pools a local search can’t reach

Offshore recruiting opens a search up to markets with deep benches in a specific stack, rather than competing for the same narrow local pool every other company nearby is also hiring from. A team relying on offshore staffing services for a hard-to-fill specialty often finds candidates faster than a team searching locally for the same skill set, simply because the pool is larger to begin with.

8. Broader working-hours coverage

Offshore IT staffing services spread across 2 or 3 overlapping time zones can extend a team’s effective working hours well past a single office’s schedule, without anyone working an unreasonable shift. Teams built around that kind of overlap tend to produce smoother handoffs than teams assembled without any timezone planning at all.

The coverage benefit compounds during incidents specifically. Offshore staffing services structured around a second time zone mean a production issue that starts at 6pm local time doesn’t have to wait until the next morning for someone to look at it.

The same overlap that helps with incidents also helps with ordinary delivery cadence. A pull request opened at the end of one team’s day can pick up a review from a teammate just starting theirs, instead of sitting untouched for 12 hours until the original author is back online.

9. Lower total cost than building the same team from scratch

Choosing to hire a dedicated software development team through an established provider usually costs less than assembling the same software development dedicated team through direct hiring, once recruiting fees, benefits administration, equipment, and ramp time are counted alongside salary. The gap is largest for hard-to-fill specialties, where a direct search can drag on for months before a single offer goes out.

Companies that decide to hire dedicated software development team support specifically to avoid that drawn-out search usually recover the provider’s margin within the first quarter, once the cost of an empty seat is priced in honestly. An empty seat rarely shows up as a line item anywhere, which is exactly why it’s the easiest cost to underestimate when comparing the 2 paths on a spreadsheet.

10. A long-term partner, not a one-off vendor

A mature IT staff augmentation agency keeps the same engineers on an account across multiple projects, which means the second and third engagements start with people who already understand the codebase and the team’s working style. An established offshore staffing agency relationship also tends to come with better bench visibility, since the provider already knows what a client’s standards look like.

That continuity is worth more over time than any single placement, and it’s the main reason companies that hire dedicated development team support once tend to come back for the next one rather than shopping the search from scratch. A provider that already understands a client’s codebase, coding standards, and release process can staff a second project faster and with less onboarding friction than starting the search over with an unfamiliar partner.

Common mistakes when evaluating these benefits

Treating cost savings as the main benefit is the most common mistake. It’s the easiest one to point to in a budget meeting, but teams that stop there miss the continuity and delivery-speed benefits that compound over multiple engagements.

Evaluating an offshore provider purely on rate is a close second. A rate that looks attractive on paper often hides weak vetting, and the resulting rework can erase the entire savings within the first few months.

Assuming every benefit on this list shows up in the first engagement is a third gap. Continuity, cultural fit, and process maturity build up gradually over several placements, long after day one.

Skipping a real onboarding process because the engineers are external is a fourth. Dedicated development team services still need repo access, a clear first task, and a named point of contact to ramp at the speed the model is supposed to deliver.

Waiting until a role is urgent to start evaluating a provider is a fifth. The companies that get the most value out of this model typically build the relationship before the pressure hits, so the first placement isn’t also the first time anyone tested how the provider performs.

Getting the most out of the model

Most of these benefits depend less on the provider and more on how the engagement is set up internally. A company that names an owner, defines a clear first task, and treats the engineers as part of the team from day one gets a materially different result than a company that treats the arrangement as a black box to check on occasionally.

The size of a company changes which of these 10 benefits matters most, without changing the underlying list. An early-stage startup usually cares most about speed and access to specialized skills it can’t yet afford to hire full time. A growth-stage company leans harder on the cost-predictability and headcount-flexibility benefits, since its hiring needs shift with funding rounds and product bets rather than staying flat year over year. A mature company with an established engineering org tends to value the market-entry and coverage benefits most, since its core team is already built and the gaps it’s filling are narrower and more specific.

None of that changes the mechanics behind any individual benefit. It just changes which ones a given company notices first, and which ones only become obvious a few quarters into using the model.

Taken together, these 10 benefits explain why the model has become a standing part of how many engineering organizations plan headcount, rather than a fallback reserved for emergencies. The teams that get the most out of it treat it as a permanent tool in the hiring toolkit, used deliberately for the problems it’s built to solve.

The providers worth staying with are the ones who make that easy rather than the ones who make the biggest promises upfront, and that holds whether the engagement is framed as staff augmentation, an offshore staffing partnership, or dedicated development team support running alongside an internal team.

How to evaluate a provider before signing

A provider’s own marketing rarely tells a buyer much about whether it can deliver on these 10 benefits consistently. The more useful signal is what happens when the request gets specific: how many engineers can be onboarded in a given month without a drop in vetting quality, and whether the provider can point to a specific team it has scaled before rather than a general claim about bench depth.

Retention data matters more than almost anything else on a provider’s pitch deck. A provider with high turnover among its own engineers is a weak bet even at an attractive rate, since a hiring manager ends up managing a revolving door of onboarding rather than a stable extension of the team. Asking for that number directly, before signing, tends to separate serious providers from ones relying on a strong sales conversation to close the deal.

Communication overlap deserves the same scrutiny as technical skill. An engineer who’s a strong technical match but shares almost no working hours with the rest of the team turns every code review and every planning meeting into an asynchronous exchange, which slows down exactly the kind of fast iteration this model is usually brought in to support.

Contract flexibility is worth reading closely before signing rather than after. A rigid, one-size-fits-all agreement that makes it expensive or slow to convert an engineer to a direct hire, or to wind an engagement down early, can quietly erase several of the 10 benefits this piece covers, even when the rate and the talent quality both looked strong going in.

None of this evaluation work has to be exhaustive to be useful. A short structured conversation covering onboarding process, retention numbers, communication overlap, and contract terms usually surfaces the gaps that matter most, well before either side has committed to anything.

Finally, a provider worth signing with should be able to explain, in specific terms, what happens if a placement isn’t working out. Vague reassurance is a worse sign than an honest answer that includes both a replacement process and a realistic timeline for it.

References are worth requesting even when a provider’s public case studies look strong. A short call with a current client, focused on concrete questions about ramp time, communication, and how the provider handled a problem when one came up, tends to reveal more in 15 minutes than a polished pitch deck reveals in an hour.

What a typical engagement looks like

Most engagements start the same way regardless of which of these 10 benefits mattered most in the decision: a short discovery call to scope the role, a shortlist of pre-vetted candidates within days rather than weeks, and a final interview loop the client runs itself before anyone signs on. Offshore staffing services built around this sequence tend to move faster than a process that starts sourcing only after the request comes in.

Once an engineer is selected, dedicated development team services typically begin with a structured first week: repo access on day one, a scoped first ticket, and a standing check-in with whoever owns the account internally. Skipping any one of those 3 steps is the single most common reason a promising engagement starts slow.

Offshore IT staffing services add one more layer worth planning for upfront: confirming working-hours overlap before the first day rather than discovering the gap after it. A team that waits to discover a 4-hour gap in availability loses weeks it could have planned around from the start.

None of this requires a large team to matter. Even a single offshore hire, added deliberately to extend coverage into a second time zone, changes how quickly a team can respond to something that breaks outside normal working hours.

By the 30-day mark, the honest measure of how the engagement is going has less to do with how many commits an engineer has shipped and more to do with whether the surrounding team’s actual output moved. A team that adds capacity and ships the same amount it shipped before has an onboarding problem worth fixing that more headcount alone won’t solve.

By the 90-day mark, retention becomes the number worth watching most closely. A provider that loses engineers mid-engagement is usually telling a buyer something about its own internal process, whether or not it says so directly, and it’s worth asking about proactively rather than waiting to find out the hard way.

The teams that get the smoothest first ninety days tend to share one habit: they treat the ramp period as something to actively manage rather than something that happens on its own. A weekly 15-minute check-in during the first month, focused specifically on blockers rather than status, catches most onboarding problems long before they show up in a delivery metric.

Frequently asked questions

Is staff augmentation cheaper than direct hiring?

Usually, once recruiting costs, benefits, and ramp time are counted alongside salary, though the gap depends on role scarcity and how long a direct search would otherwise take. It’s largest for hard-to-fill specialties, where a dragging search carries its own hidden cost.

How fast can a provider fill a role?

Often 2 to 3 weeks for a role already close to the provider’s existing bench, though a highly specialized skill set can take longer regardless of provider.

Do these engineers work exclusively on one company’s project?

On a well-run engagement, yes. That’s what separates a dedicated team from a shared contractor pool splitting attention across several clients at once.

Does the model work for a company with no local entity in a new market?

Yes. The provider handles the local employment relationship, which lets a company start hiring in a new market well before any entity paperwork is filed.

Is an offshore staffing agency the same thing as a staff augmentation provider?

Functionally, most of the time. Both describe a provider that employs the engineer and hands day-to-day direction to the client, whichever label sits on the homepage.

How long does a typical engagement run?

It varies widely, from a few months covering a specific project to multi-year arrangements that function as an ongoing extension of the team. The length should follow the actual need rather than a fixed contract term.

Can an engineer placed this way convert to a direct hire later?

Usually, yes, though conversion terms vary by provider and are worth confirming before signing rather than assuming they’re standard.

Syncing Safety Compliance Data Across Field Teams

Managing safety compliance across distributed field operations requires precise coordination between mobile workers and office staff. Missing inspection forms, delayed incident logs, and paper checklists create information gaps that increase financial risk.

Automated data synchronization eliminates manual updates by linking field entries directly with central desktop databases. When field crews record daily checks on mobile devices, office managers gain immediate visibility into operational hazards.

photo-1742112125567-3e8967bad60f

Mitigating Legal and Financial Risks in Field Operations

Unsynchronized records create severe liabilities during workplace injury audits. Discrepancies between field activity logs and central management files often weaken legal defenses during formal disputes. Real-time background sync keeps legal teams and safety managers working with matching dataset versions across all departments.

Commercial construction and utility projects in Richmond require strict adherence to regional safety standards. When an injured technician requires medical coverage or legal assistance, working with a Richmond workers' compensation attorney helps clarify the complexities of state claims. Maintaining accurate digital records provides clear evidence of baseline compliance during formal administrative reviews.

Field managers who rely on outdated paper logs often face audit delays and lost documentation. Standardizing on digital field input forms ensures that every inspection record receives an instant timestamp. This disciplined documentation habit protects companies against unexpected regulatory challenges.

Moving From Manual Planning to Automated Performance

Industry research indicates that recent corporate compliance strategies represent a decisive pivot from basic planning to active performance. Organizations using integrated compliance systems experience measurable reductions in repeated risk items across all project sites. Automation removes the friction of manual spreadsheet uploads.

Field crews need simple mobile workflows that push inspection logs straight to core desktop software. Direct synchronization prevents lost paperwork and ensures safety metrics remain complete every single day. Teams spend less time organizing paper forms and more time rectifying hazards.

Desktop software systems function best when fed continuous real-time data from field devices. Eliminating manual data re-entry minimizes transcription errors and keeps administrative records accurate.

Uncovering Blind Spots Through Rapid Incident Reporting

Fast incident reporting uncovers hidden hazards, surfaces systemic operational issues, and establishes a reliable loop of continuous safety improvement. Industry data reveals that work-related injuries lead to 103 million annual days lost across modern industrial sectors. Digital sync platforms reduce reporting delays from days to seconds.

Connecting field devices to central servers provides clear operational benefits for growing field operations:

  • Automatic timestamping verifies exactly when safety inspections occur.
  • Offsite supervisors receive instant notifications for critical safety violations.
  • Central databases stay synchronized without tedious end-of-day manual entry.

Rapid incident logging allows safety coordinators to identify emerging risks before minor issues become major disruptions. Immediate data transfer allows teams to dispatch corrective support quickly.

Deploying Mobile-First Solutions for Field Usability

Modern mobile-first safety management software is engineered to suit field service businesses operating outside traditional offices. Industry statistics show around 72% of new platform installations support mobile reporting functions to maximize field usability. Technicians complete safety audits much faster when software mirrors their daily mobile routine.

User-friendly mobile screens encourage higher submission rates from active job sites. Automated sync engines handle data delivery behind the scenes so crews remain focused on their primary physical tasks.

Intuitive mobile interfaces let workers fill out forms in seconds using drop-down menus and simple touch inputs. A smooth user experience turns safety compliance into a seamless daily habit.

Maintaining Continuous Offline Sync in Remote Locations

Dedicated platforms capture annotated photos with automatic geo-tagging offline and sync all records when network connectivity returns. Standard regulatory penalties increased significantly in 2025, reaching up to $16,550 per serious violation. Remote teams cannot afford data drops caused by poor cellular signals.

Offline synchronization stores completed inspection forms securely on the handheld device. Once a signal is re-established, the sync background engine transfers all pending records directly to desktop software.

Field workers operating underground or in rural areas frequently lose cellular connection. Local caching protects collected data from disappearing mid-entry. Intelligent sync rules resolve database conflicts automatically upon reconnecting.

Reducing Direct Workplace Injury Costs

National safety statistics show employers pay more than $1 billion per week in direct workers' compensation costs for disabling nonfatal workplace injuries. Streamlining data flow between field staff and risk management teams lowers these heavy financial burdens. Unified data synchronization provides leadership with the precise evidence needed to optimize risk mitigation programs.

Preventing a single major injury can save an organization thousands of dollars in medical costs and insurance premiums. Direct data integration allows risk managers to analyze real-time site metrics and fix dangerous conditions quickly.

g13116a910a43f043a92bbe3b8d72268366c7efa2e816aeb939a189c96315a7d808134fcb2c53dcc7d477b02bb1d8ac14076ad36a7e8b57da21aabce3388d14e1_1280.jpg

Syncing safety compliance data bridges the physical gap between field personnel and administrative management. Connecting mobile forms directly to central desktop software builds an accurate record of daily field activities. Organizations that implement reliable data synchronization lower regulatory liabilities, protect field workers, and maintain seamless administrative operations across every active job site.

Why Secure Data Synchronization Depends on Strong Patch Management

Data synchronization has become an essential part of modern work. Employees expect contacts, calendars, tasks, notes, and other business information to remain consistent across computers, phones, and workplace applications. When synchronization works well, teams can access current information without repeatedly entering the same data or checking several systems for updates.

This convenience also creates a security responsibility. Every application, operating system, device, and service involved in moving or displaying synchronized data becomes part of the organization’s technology environment. If one component contains an unresolved vulnerability, attackers may have an opportunity to access sensitive information, interrupt operations, or compromise connected systems.

Secure synchronization therefore depends on more than reliable data transfer. It also requires disciplined software maintenance, with patch management playing a central role.

High-tech server rack in a secure data center with network cables and hardware components.

A Connected Environment Has Many Moving Parts

A synchronization process rarely involves only one application. Business data may pass between desktop software, mobile devices, operating systems, cloud services, and local networks. Each component can have its own release cycle, security requirements, and update process.

This creates a larger surface for IT teams to manage. A fully updated synchronization application may still interact with an outdated operating system. A protected office computer may exchange data with a remote device that has missed an important security update. A third-party utility may also introduce exposure if the organization lacks visibility into its installed version.

Organizations must therefore consider the condition of the entire environment, not just the application that users see. Security depends on every connected layer receiving appropriate maintenance.

Why Outdated Software Creates Security Gaps

Software developers regularly identify defects after an application has been released. Some affect usability or performance, while others may create security weaknesses. Vendors can address many of these issues through patches, which modify the software to correct known problems.

Once a vulnerability becomes known, an outdated application may remain exposed until the organization applies the relevant update or introduces an appropriate workaround or compensating control. In some cases, a vendor patch may not yet be available. The longer a known weakness remains unresolved or insufficiently mitigated, the longer the organization may operate with avoidable risk.

This matters in environments that handle synchronized business data. Contacts can contain personal and professional information. Calendars may reveal meeting details and future plans. Tasks and notes can include references to customers, internal projects, or operational priorities. Protecting this information requires attention to the software that stores, processes, and transfers it.

Reliable Synchronization Is Also a Business Continuity Issue

Cybersecurity is not limited to preventing information theft. It also concerns the availability and integrity of important systems and data.

If a vulnerable application becomes compromised, synchronization may stop working or begin producing unexpected results. Employees could lose access to current records, encounter conflicting versions, or spend time checking which copy is accurate. IT personnel may need to isolate devices, investigate the incident, and restore affected systems.

Regular patching helps reduce avoidable exposure before it develops into a larger operational problem. It can also address software defects that cause crashes, compatibility issues, or poor performance. As a result, software maintenance supports both security and dependable day-to-day work.

Manual Updates Become Difficult at Scale

Updating a single personal device may be straightforward. Managing updates across a business environment is more complicated.

Organizations may use different operating systems, application versions, device types, and configurations. Some employees work from an office, while others connect from home or another location. Devices may not be online when an update becomes available. Certain applications may also require updates outside normal working hours to avoid interrupting users.

A manual approach can leave IT teams dependent on spreadsheets, reminders, and individual follow-ups. It may also be difficult to confirm whether every device completed an update successfully. As the number of endpoints and applications increases, so does the possibility that something will be missed.

Centralized processes give administrators a clearer way to identify outdated software, prioritize necessary fixes, and verify deployment results. Organizations with distributed technology environments may use a patch management tool to automate updates and manage supported operating systems and third-party applications through a more consistent workflow.

Prioritization Matters as Much as Speed

Installing every update immediately is not always practical. Some patches address urgent security weaknesses, while others introduce minor improvements. Business-critical applications may also require testing before a new version is deployed broadly across the organization.

An effective patch management process should classify updates according to risk and business importance. IT teams can consider the severity of the vulnerability, the systems affected, the sensitivity of the data involved, and whether a device is accessible from outside the organization.

Critical security fixes should receive prompt attention when suitable patches are available. If a patch cannot be installed immediately, the organization may need to assess available mitigations until deployment becomes possible. Lower-risk updates can follow a planned schedule. This approach helps teams direct limited resources toward the weaknesses that could have the greatest impact.

Updates Should Be Planned to Minimize Disruption

Employees may postpone updates when they expect interruptions, forced restarts, or lost work. That behavior is understandable, but it can leave devices in an inconsistent security state.

Clear scheduling can reduce this friction. Routine updates can be assigned to maintenance windows or quieter periods, while urgent patches can follow an accelerated process. Employees should receive concise notices when an update requires their involvement.

Organizations should also monitor whether deployments succeed. An update that was approved but failed to install does not remove the vulnerability. Reporting and verification help IT teams identify unsuccessful installations and take corrective action.

Visibility Supports Accountability

A company cannot manage software effectively if it does not know what is installed. An accurate inventory should show which devices exist, which applications they run, and which versions are present.

This visibility helps administrators find unsupported or outdated software before it becomes an overlooked risk. It also assists with investigations and audits by providing a record of system changes and patch activity.

The process does not need to produce unnecessary complexity. Its purpose is to answer practical questions: Which systems require attention? Which updates are most important? Were they deployed successfully? Which devices still need remediation?

Reliable answers make patch management measurable rather than dependent on assumptions.

Patching Works Best as Part of Layered Security

Patch management is important, but it is not a complete cybersecurity strategy. Organizations still need appropriate access controls, strong authentication, secure backups, endpoint protection, employee awareness, and incident response procedures.

These measures address different kinds of risk. Access controls limit who can reach sensitive information. Backups support recovery. Security monitoring can reveal suspicious activity. Patching reduces exposure to known software weaknesses, while compensating controls may provide interim protection when immediate patching is not possible.

Together, these controls provide stronger protection than any single measure could deliver alone. For synchronized data, this layered approach helps protect information throughout its journey across applications and devices.

Make Software Maintenance a Routine Security Practice

Secure data synchronization begins with dependable software but cannot end there. Organizations must maintain the broader environment in which synchronization occurs, including operating systems, endpoints, and connected applications.

A documented patching process gives IT teams a repeatable way to discover missing updates, prioritize security fixes, schedule deployments, and verify results. When a patch is unavailable or cannot yet be deployed safely, the process should also support the evaluation of temporary mitigations and compensating controls. Automation can further reduce repetitive work and make maintenance more consistent across distributed devices.

When patch management becomes a regular business practice rather than an occasional reaction, organizations can reduce preventable weaknesses while supporting reliable access to synchronized information. The result is a more resilient technology environment where productivity and cybersecurity reinforce each other.

CMS for React: Three Questions Before You Pick a Platform

A CMS for React has one job: let someone publish without opening a pull request. Pricing tier, editor polish, and plugin count are details you sort out later. Three harder questions come first. Does the app need a CMS at all? Self-hosted or managed? And how does new content actually reach a rendered page?


Most roundups skip straight to naming platforms. Storyblok, Sanity, Contentful, Payload, Strapi. React 19 hit 48.4% daily use within months of release, per the 2025 State of React survey. The CMS market serving that base keeps splitting into more options every year. More names on a list make “which one” louder as a question, not easier to answer.

Question One: Do You Even Need a CMS?

A person holds a sticker featuring the React logo, commonly used in web development.

If the person editing content is a developer, you don’t. A Markdown file in the repo, reviewed through a pull request, ships faster and skips the API round trip entirely.

Reach for a CMS once a non-developer needs to publish without you. Or once content changes faster than your deploy cycle can keep up. A marketing team running weekly campaigns. A support team updating FAQ copy every day. That’s the real trigger, and it has nothing to do with tech stack. It’s about who’s allowed to hit publish.

Question Two: Self-Hosted or Managed?

This gets sold as a technical decision. It’s really a cost decision wearing a technical costume, and most comparison posts skip the math.

On raw dollars, self-hosted wins big. A self-hosted open-source CMS can run 600to600to15,000 over five years on a modest VPS. A managed plan can climb into six figures over that same stretch for a busy site.

The dollar figure isn’t the whole cost. Someone still has to run the thing. Even with solid automation, a self-hosted CMS eats roughly one to two hours a month in ops time: patches, backups, uptime checks. That’s a small tax for a team that already has spare engineering hours. It’s a real cost for a two-person team shipping features full time.

A working rule: count your editors and your spare engineering hours, not just the number on a pricing page. Small teams with no ops slack usually come out ahead on managed. Agencies running several client sites, or teams with room in the sprint, tend to earn that cost back within 12 to 18 months of self-hosting.

Question Three: How Does Content Reach the Page?

This is the part that’s actually specific to React, and the part generic CMS roundups skip.

A headless CMS is API-first. Content comes back as JSON or over GraphQL, decoupled from any one front end. That’s what makes it work equally well for a React site, a mobile app, or anything else reading from the same source. An old-style CMS welds its front end to its content store. Wiring that into a React app usually means fighting the platform rather than using it.

Once a CMS is API-first, a React or Next.js app has three real ways to pull from it:

  • Fetch at build time. Static generation reads content once, at build. Fast and cheap, stale until the next deploy. Fine for content that barely moves.
  • Fetch on every request. Server components hit the CMS on each page load. Always current, but every visitor pays the CMS’s response time.
  • Cache the response, clear it on demand. Pages serve from cache like static output. A webhook tells the app to drop specific entries the moment content actually changes.

The third option is the one worth the setup time, and almost nobody writes about it. Most teams either over-fetch on every request or under-fetch and serve stale pages for hours. A webhook closes that gap for free.

Wiring Up Webhook-Driven Cache Clearing

Next.js’s revalidateTag clears cache by tag instead of by page. Tag a fetch once, then clear that exact tag when the CMS tells you something changed:

// app/posts/[slug]/page.tsx
async function loadPost(slug: string) {
  const response = await fetch(`https://cms.example.com/api/posts/${slug}`, {
    next: { tags: [`post:${slug}`] },
  });
  return response.json();
}

// app/api/cms-webhook/route.ts
import { revalidateTag } from "next/cache";
export async function POST(request: Request) {
  const token = request.headers.get("x-cms-signature");
  if (token !== process.env.CMS_WEBHOOK_SECRET) {
    return new Response("Unauthorized", { status: 401 });
  }
  const { slug } = await request.json();
  revalidateTag(`post:${slug}`);
  return Response.json({ ok: true });
}

The CMS calls this endpoint on publish, and only the matching tag clears. A site with thousands of pages doesn’t rebuild the whole thing because one entry changed. A publish event pushes to your app, so nothing has to poll for changes. Check the signature header before touching the payload. An open revalidation endpoint is a free invitation to hammer your cache.

Does the CMS Choice Change React SEO?

Only through rendering, not through the CMS itself. A React app that renders content purely client-side ships an empty shell to a crawler until the JavaScript finishes running. Google’s own guidance on JavaScript SEO describes a second rendering wave for JS-heavy pages, well behind text-first pages in the queue. Server components and static generation skip that wave entirely, since the HTML a crawler sees already has the content baked in.

What the CMS needs to get right is narrow. Clean, structured fields for title, description, and Open Graph image that map onto Next.js’s Metadata API. And a way to list published slugs for a sitemap. A CMS that lets raw HTML leak into a title field makes both jobs harder. So does hiding the slug behind a picker with no API access.

When an Old-Style CMS Still Wins

A fair comparison has to say this part too. A team with no front-end developer, and no plan to build a custom app, ships faster with a single bundled CMS and a theme than with any headless setup. If the actual requirement is “we need a whole website with an editor attached,” going headless solves a problem that team doesn’t have yet. The moment a real React front end enters the picture, that trade reverses.

The Schema Outlasts the Platform Pick

Whatever CMS wins, the content schema is the part that survives the tooling decision. A content type built around one loose rich-text blob turns every layout change into a migration project. Fields modeled as typed, reusable pieces survive a redesign, because only the component rendering the data has to change, not the data itself. Spend the modeling time up front. It costs less than fixing content after the fact.

Common Questions

Does a headless CMS work cleanly with the Next.js App Router?
Yes, with one adjustment. Fetches inside Server Components run without client-side context, so pass any CMS config or client instance as props rather than through a provider.

Is a headless CMS overkill for a small React app?
For a five-page site updated twice a year, yes. A Markdown file per page is simpler to maintain. The CMS earns its keep once publishing frequency or editor headcount climbs.

Can you swap CMS platforms later without a full rewrite?
Only if the fetch logic lives behind your own data functions, not scattered across components. Worth doing regardless of which CMS gets picked first.

Does going headless hurt React SEO?
No, as long as
pages render server-side or statically. The SEO risk comes from client-only rendering, not from where the content is stored.

Making the Call

Skip the platform-name debate until the three real questions are answered. Does a non-developer need to publish? Does the team have spare hours to run its own CMS? Will the fetch pattern keep pages both fast and current? Get those right first. The specific platform, a hosted React CMS framework or otherwise, ends up a much smaller decision than the marketing pages make it look.