AI Watermarked Text: The Enterprise Implementation Guide for Content Teams

Most discussions about AI watermarking focus on detection methods or philosophical debates about transparency. What enterprise teams actually need is a roadmap for adapting workflows when watermarked text becomes the norm across every major AI provider. Your content operations will change dramatically over the next year, and waiting until watermarking arrives in every tool you use might leave your team scrambling.

The shift toward embedded watermarks represents more than a technical feature. Companies now face questions about governance frameworks, cross-platform consistency, and legal documentation that simply did not exist before. Building the right infrastructure today prevents compliance headaches tomorrow.
Close-up of a hand pointing at stock market graphs on a monitor in a workspace.

What AI Text Watermarking Means for Your Business (Not Just Claude)

AI text watermarking embeds invisible statistical patterns into generated content that specialized tools can later detect. Unlike metadata tags that disappear when text gets copied, these patterns persist through typical editing and reformatting. Anthropic released this capability for Claude in early 2025, but the technology will likely spread across OpenAI, Google, and other providers soon.

Your business probably uses several AI writing platforms already. Marketing teams might rely on one tool while customer support uses another. Each platform will implement watermarking differently, with varying detection thresholds and persistence characteristics. The strategic challenge involves managing this complexity across your entire content ecosystem.

Watermarking creates accountability. When AI-generated content appears in customer communications, marketing materials, or documentation, watermarks provide an audit trail. This matters for regulated industries where content provenance affects compliance obligations. Financial services firms and healthcare organizations face particular pressure to demonstrate content origins.

The Federal Trade Commission has already signaled interest in AI transparency for consumer-facing content. Watermarking technology gives compliance teams a verification mechanism that manual processes cannot match at scale.

Assessing Your Current AI Content Stack: Tools, Workflows, and Watermark Exposure

Start with an inventory. Document every AI writing tool your organization uses, including shadow IT deployments that individual teams adopted without central approval. Check procurement records, browser extensions, and departmental software subscriptions. Many companies discover a dozen AI platforms running simultaneously across different business units.

Map how content flows through your organization. Does AI-generated draft copy move through editing systems, translation platforms, or content management databases? Each handoff point represents a potential watermark preservation or degradation risk. Heavy editing might weaken watermark signals while automated reformatting could eliminate them entirely.

Evaluate your current content governance policies. Most enterprises built these frameworks before watermarking existed, so gaps will appear. Your policies probably address plagiarism detection and brand voice consistency but might ignore AI content authentication entirely. This gap exposes your organization to risks as watermarking becomes industry standard.

Calculate your watermark exposure percentage. What portion of your published content contains AI-generated text? Some teams use AI for initial research and outlining while others generate complete drafts. Understanding this baseline helps prioritize policy updates and detection infrastructure investments.

Setting Up Detection Infrastructure: Tools and Methods That Actually Work

Detection infrastructure requires both technical tools and human processes. Anthropic provides a watermark detection API for Claude-generated content, but cross-platform detection remains challenging. No universal detector works across all AI providers yet, so enterprises need multiple verification methods.

Build detection checkpoints into content workflows rather than treating verification as a final step. Configure your content management system to flag potentially watermarked text before publication. This early warning system prevents watermarked content from reaching customers when disclosure matters.

Consider implementing random sampling protocols. Testing every piece of content might prove impractical, but statistical sampling provides reasonable assurance. Audit a percentage of published materials monthly to verify watermark detection accuracy and identify process gaps. Financial auditing principles apply equally well to content verification.

Document detection accuracy rates for each tool in your stack. Different AI providers will show varying watermark persistence after editing. Claude watermarks might survive heavier modification than other platforms. Track these performance differences to inform content workflow decisions and editing guidelines.

Partner with vendors who prioritize watermarking capabilities. When evaluating new AI content tools, ask specific questions about watermark implementation, detection APIs, and roadmap commitments. Vendor selection criteria should include watermarking support alongside traditional factors like accuracy and cost.

Updating Content Governance Policies for Watermarked AI Text

Your governance framework needs explicit watermarking protocols. Define when AI-generated content requires disclosure to end users versus internal tracking only. Consumer-facing marketing materials might demand different transparency standards than internal research reports. These distinctions should reflect both legal requirements and brand values.

Establish editing thresholds that preserve watermark integrity. If substantial human revision removes detectable patterns, your audit trail disappears. Set guidelines about how much editing content can undergo while maintaining watermark verification. Some organizations prohibit heavy modifications to AI drafts specifically to maintain detection capability.

Create approval workflows that account for watermarked content. Certain materials might require additional legal review when watermarks indicate AI generation. Build these routing rules into your content management platforms so review happens automatically rather than relying on manual flagging.

Address the hybrid content challenge. Most business content combines AI-generated sections with human writing. Your policies should clarify how to handle mixed-origin materials, what percentage of AI content triggers watermark disclosure, and how to document the authorship blend. The Society for Human Resource Management suggests similar documentation approaches for AI-assisted hiring decisions.

Cross-Platform Watermarking Strategy: Handling Multiple AI Providers

Standardization becomes critical when managing multiple AI platforms. Different providers will implement incompatible watermarking schemes, creating integration headaches. Your enterprise needs a unified approach despite underlying technical fragmentation.

Designate primary AI tools for specific content types. Marketing might standardize on one platform while technical documentation uses another. This segmentation simplifies watermark management because each content category has predictable watermark characteristics. Avoid allowing every team to choose their preferred AI tool independently.

Build a watermark registry that tracks which AI platforms generated which content. This metadata layer sits above individual watermarking implementations and provides consistent tracking regardless of underlying technology. When vendors change watermarking approaches or new tools enter your stack, the registry maintains continuity.

Negotiate enterprise agreements that include watermarking guarantees. As you consolidate AI vendors, contractual commitments about watermark persistence, detection API access, and advance notice of watermarking changes protect your investment in detection infrastructure. Treat these provisions as essential rather than optional contract terms.

Legal and Compliance Considerations: Disclosure, Liability, and Documentation

Disclosure requirements vary by industry and jurisdiction. Financial services regulations might mandate revealing AI involvement in investment advice while general marketing faces fewer restrictions. Consult legal counsel about disclosure obligations specific to your business operations and customer base.

Liability questions remain unsettled. If watermarked AI content contains factual errors or creates customer harm, who bears responsibility? Your policies should address quality assurance processes that compensate for AI limitations. Simply detecting watermarks does not absolve organizations of content accuracy obligations.

Documentation standards must evolve alongside watermarking capabilities. Maintain records showing what content underwent watermark detection, results of those scans, and any remediation actions taken. These audit trails become critical if regulatory inquiries arise or legal disputes involve content authenticity.

The Small Business Administration recommends similar documentation practices for other automated business processes. Apply those same rigor standards to AI content governance. Treat watermark detection logs as permanent records rather than temporary operational data.

Future-Proofing Your Content Operations as Watermarking Becomes Standard

Industry-wide watermarking adoption will accelerate faster than most enterprises expect. Building flexible systems now prevents costly retrofitting later. Design detection infrastructure that can incorporate new AI providers without complete workflow redesigns.

Invest in team education about watermarking implications. Content creators need to understand how their editing choices affect watermark persistence. Legal teams require training on disclosure obligations. Operations staff must learn detection tool capabilities and limitations. This knowledge investment pays dividends as watermarking complexity increases.

Monitor regulatory developments that might mandate watermarking practices. Several countries are considering AI transparency legislation that could affect content disclosure requirements. Staying ahead of these regulatory curves positions your organization as a compliance leader rather than a reluctant follower.

Plan for interoperability improvements. Current watermarking fragmentation will likely give way to industry standards that enable cross-platform detection. Position your infrastructure to adopt these standards quickly when they emerge. Flexible architecture choices today enable rapid adaptation tomorrow.

Building robust AI content governance around watermarking technology requires immediate action. Enterprises that establish detection infrastructure, update policies, and train teams now will navigate the watermarked content landscape confidently. Those who delay risk compliance gaps and operational chaos as watermarking becomes ubiquitous. Start your watermarking strategy assessment this week, not next quarter.
How to Repair Corrupted Files Without Losing Work

When a file refuses to open, the safest first move is to protect the original copy and test a repair corrupted file workflow before you try to rebuild anything from memory. That simple habit helps separate a bad save, a sync conflict, or a transfer error from deeper file damage.

Why files become corrupted in daily work

Files usually break during ordinary work moments rather than dramatic accidents. A laptop can lose power during a save, an app can crash while writing the final version, a cloud folder can sync two edits at once, or a USB transfer can stop halfway through. The file name may still look normal, but the underlying structure is no longer reliable. In many cases the document is not fully gone; it is only missing enough structure that the app can no longer read it cleanly.

That is why file corruption is so confusing. The content often still exists in part, but the program cannot read it cleanly. In practice, the first response should be simple: stop overwriting the original, make a duplicate, and check whether a backup or version history already contains a clean copy.

That is why the most common complaints are usually the same: the image looks faded, soft, torn, scratched, or simply too weak to print, share, or archive without more work.

What should you try before starting file repair

Before you repair anything, look for an easy recovery path. Check autosave, local drafts, cloud version history, and any earlier export you may have saved. If the file still fails to open everywhere, the problem is likely in the file structure rather than the app you are using.

For a browser-based first pass, Repairit Online can quickly show whether a smaller file still has a recoverable structure without forcing a full desktop setup.

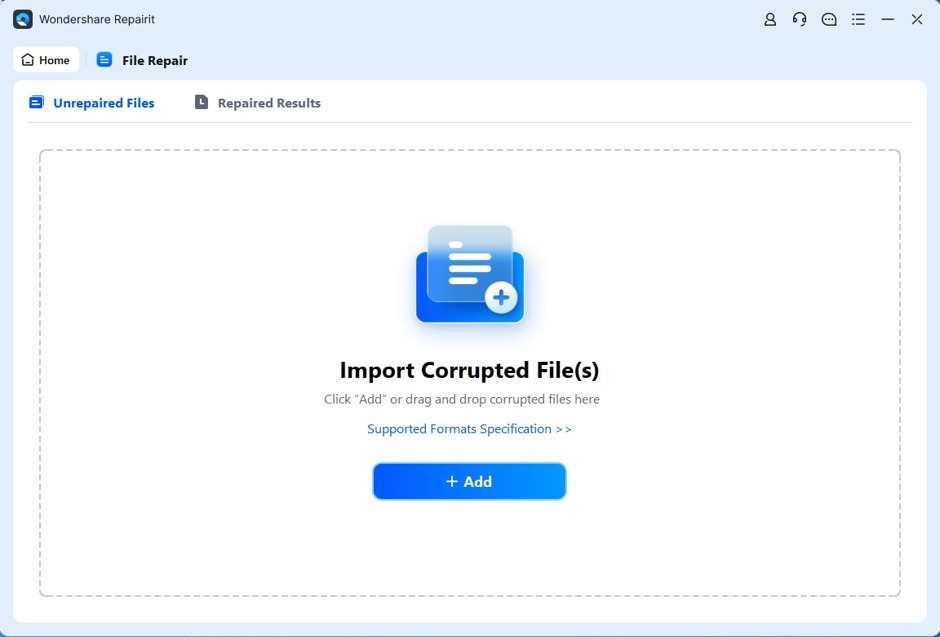
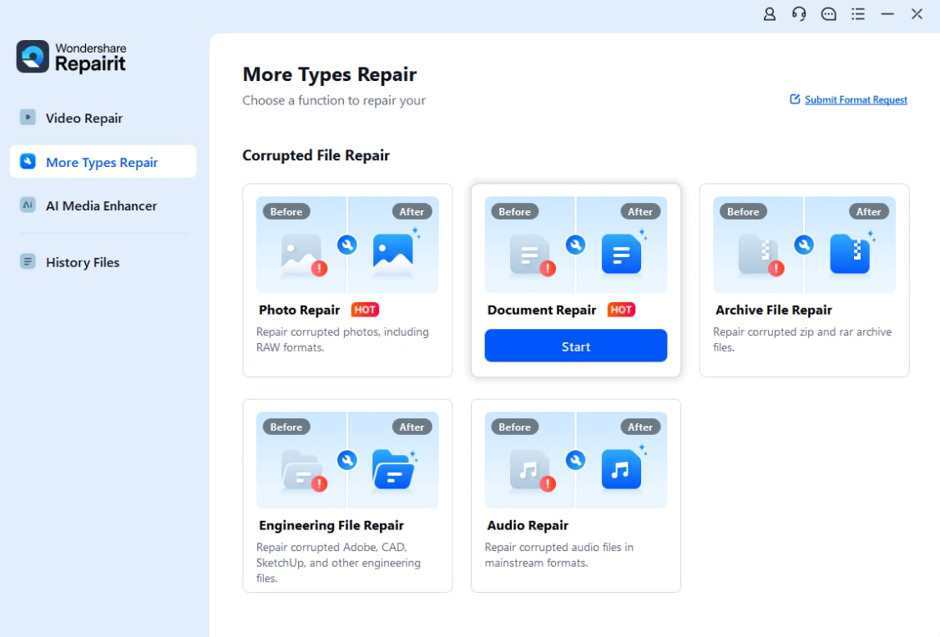
When the file is larger, more complex, or tied to a deadline, a desktop workflow is usually the better next step. You can choose Wondershare Repairit desktop version. It keeps the original file local, gives you more room to review the result, and fits better when the damaged document contains tables, attachments, or repeated revisions. That is especially useful for reports, project notes, and shared files that other people still need to edit.

Step-by-Step: Repair a Corrupted File

The process is intentionally direct: choose file repair, add the damaged file, and preview the repaired result before you trust it. That keeps the user focused on recovery instead of on technical file details.

This workflow is helpful because it reduces the risk of making the file worse. You work on a duplicate, let the tool inspect the damaged copy, and only then decide whether the recovered version is good enough to return to work. If the preview does not look right, you can stop there and try another version instead of burning time on repeated manual attempts.

For office files, the value is not only repair speed. It is also consistency. A clear sequence gives people a repeatable way to handle corrupted documents, spreadsheets, presentations, and PDFs without starting over from scratch. It also makes the handoff easier when a teammate needs to review the repaired copy after you are done.

Repair corrupted files step-by-step

Step 1: Add a copy of the damaged file

Always work on a duplicate. Keep the original untouched so you still have a fallback if the repair result is partial or if you later find a better version in backup. This single habit prevents most recovery mistakes.

repairitimage11.jpg

Step 2: Let Repairit analyze the file

Open the repair workflow and add the damaged copy. The tool inspects the file structure for you, which is useful when the document still exists but behaves as if it were broken. The goal is to get back a readable version without guessing at the internal format.

repairitimage41.jpg

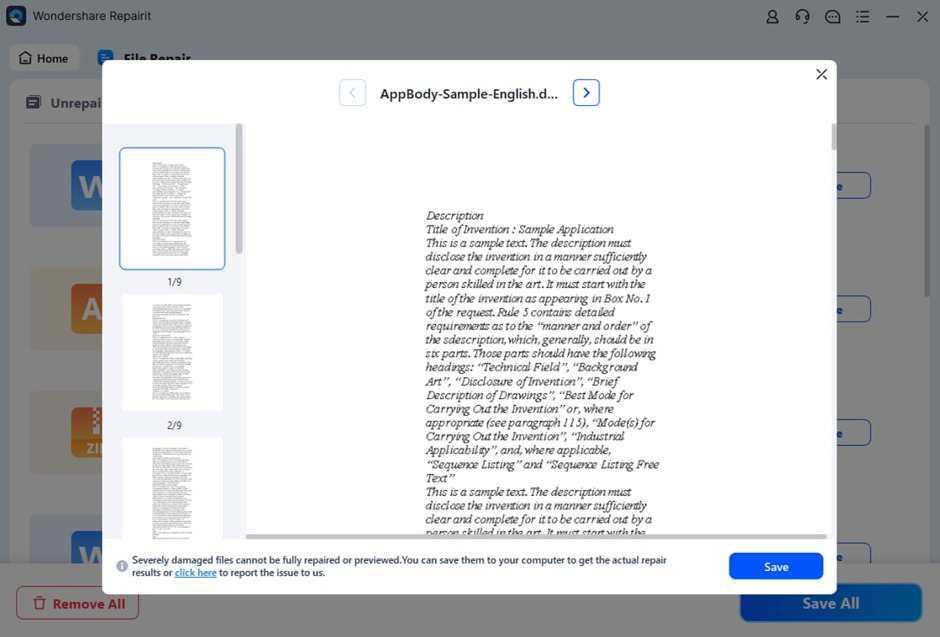
Step 3: Preview and save the repaired result

Review the output carefully before replacing the working copy. Check text, layout, tables, and any embedded content. If the file opens normally and the important parts are still intact, save it as a new clean copy and keep the source archive unchanged.

repairitimage21.jpg

Desktop vs Online File Repair

The right choice depends on urgency and file complexity. Online repair is good for a quick first check, while desktop repair is better when the file matters enough to justify a more controlled recovery process. The difference is less about technology and more about risk: smaller, simpler files can move fast, but larger working files deserve more care.

Online repair fits smaller files and short decision cycles. Desktop repair fits large, important, or repeatedly edited files because it gives you more control over the recovery workflow and keeps the local copy in your hands.

For teams, the practical rule is simple: use the browser path for speed, and use the desktop path when the file is too valuable to treat lightly.

Choose online restoration when the photo still has readable detail

Use caseDesktop repairRepairit Online
Large thesis, client project, or business fileBetter for heavier files, deeper preview, and local controlLess ideal if the file is large or needs more review
Need a fast browser check before a deadlineWorks well, but requires desktop setupBest fit for quick checks and short recovery cycles
Shared campus or office computerMay need permission, install time, or local storageConvenient when software installation is restricted

Conclusion

A corrupted file does not always mean the work is gone. The safer approach is to protect the original, repair a copy, and confirm the result before you replace anything in circulation.

gives that process a practical starting point when the file matters more than the time you would spend rebuilding it.

The practical goal is simple: do not wait for a meaningful image to become unusable before treating it as worth preserving. If the memory still matters, the photo deserves a chance to be saved.

Top Data Annotation Companies in the USA: 2026 Industry Guide

Modern enterprise artificial intelligence systems rely on massive volumes of meticulously labeled training data. Whether powering autonomous mobility, automated retail checkouts, or large language models, an algorithm’s real-world accuracy depends entirely on data quality. The global data annotation market continues its rapid expansion toward multi-billion-dollar valuations, driven by the demand for complex computer vision and multimodal training pipelines.

Choosing an experienced data labeling partner ensures strict quality assurance, scalable human-in-the-loop workflows, and rapid delivery timelines. Here is a curated evaluation of the leading data annotation companies serving the US market in 2026.

What Are Data Annotation Services?

Data annotation is the process of labeling raw assets—including images, video streams, audio, and text—into structured formats that machine learning models can interpret. This involves tasks such as drawing bounding boxes around vehicles, segmenting agricultural imagery, transcribing speech, or categorizing sentiment in conversational data.

High-performing enterprise teams partner with specialized data annotation companies to ensure their training sets maintain sub-pixel precision and strict statistical consistency.

Top Data Annotation Providers in 2026

1. Tinkogroup

Founded in 2016, Tinkogroup has built an established reputation as a precision-focused data preparation partner for enterprise AI initiatives across North America and Europe. Operating with dedicated in-house labeling teams, the company combines human expertise with flexible tooling integrations (including CVAT, Labelbox, and Datasaur). Tinkogroup maintains up to 99% annotation accuracy through structured multi-tier quality assurance.

  • Core Services: High-precision Computer Vision (polylines, keypoints, semantic segmentation), NLP and text categorization, data processing, and structured web research.
  • Key Strengths: Dedicated annotator pods, transparent pricing models (fixed-price and hourly), and a complimentary pilot testing program for enterprise validation.

2. Scale AI

Headquartered in San Francisco, Scale AI provides foundational data infrastructure for enterprise tech giants, research labs, and defense applications. Through its proprietary Scale Data Engine, the platform combines automated pre-labeling with large-scale human review networks.

  • Core Services: Multimodal annotation, 3D LiDAR labeling, LLM evaluation, and synthetic data generation.
  • Key Strengths: Massive enterprise scalability, advanced automation pipelines, and deep tooling ecosystems.

3. Label Your Data

Label Your Data offers comprehensive data labeling services for computer vision and NLP models, supported by multi-step QA workflows. The provider delivers secure data handling processes compliant with international security standards.

  • Core Services: Bounding boxes, video object tracking, named entity recognition (NER), and speech transcription.
  • Key Strengths: API integrations, clear per-object pricing tiers, and fast turnaround on standard annotation formats.

4. Keymakr

Specializing heavily in Computer Vision, Keymakr delivers full-cycle training data creation and annotation. Supported by their proprietary Keylabs workflow platform, they specialize in complex spatial datasets for autonomous systems and smart robotics.

  • Core Services: Polygon segmentation, 3D point cloud LiDAR labeling, video tracking, and custom dataset creation.
  • Key Strengths: Robust video tooling, specialized sensor labeling, and strong quality control frameworks.

5. Anolytics

Anolytics provides scalable, cost-effective data labeling for machine learning teams developing computer vision and text models. Their workflow models cater to high-volume image classification, e-commerce catalog structuring, and geospatial mapping.

  • Core Services: Image and video annotation, boundary labeling, satellite imagery processing, and content moderation.
  • Key Strengths: Competitive rates for large-scale routine data labeling and extensive offshore production capacity.

Key Criteria for Selecting a Data Annotation Partner

When evaluating external data labeling vendors, enterprise AI leaders focus on five essential operational factors:

  • Verification and QA Architecture: Look for multi-tiered review systems that implement consensus scoring, inter-annotator agreement tracking, and real-time accuracy benchmarks above 95%.
  • Domain Expertise: Ensure the provider has direct production experience handling your specific data modality, such as data annotation for path planning or complex NLP tokenization.
  • Data Security and Compliance: Verify strict adherence to international security frameworks such as ISO 27001, SOC 2, and GDPR.
  • Workforce Management: In-house or dedicated managed teams consistently provide higher labeling consistency and lower turnover than open crowdsourced labor pools.
  • Pilot Evaluation: Leading vendors offer free sample annotation runs to demonstrate accuracy, turnaround time, and guideline adherence before full contract deployment.

Emerging Trends in Training Data Operations

The data annotation sector continues to evolve alongside advances in foundational AI models:

  • Multimodal Pipelines: Modern models require unified labeling across multiple inputs—combining synchronized video, audio transcription, and sensor metadata within a single workflow.
  • Human-in-the-Loop Verification: AI-assisted pre-labeling accelerates production, but human domain experts remain essential for resolving complex visual ambiguities and edge-case exceptions.
  • Risk-Adjusted Quality Control: Enterprise teams are moving away from rigid sampling toward adaptive QA, automatically adjusting review rates based on task complexity and individual annotator reliability.

The Tech Stack a Two-Person Startup Actually Needs

Every founder has been there. You're two weeks into building something, and suddenly you've signed up for fourteen different apps. There's a project board you barely open, a note-taking tool nobody agreed on, and three overlapping ways to send messages. None of it talks to each other, and half of it's on a free trial that expires on Friday.

The temptation to over-tool is real, especially when every SaaS company on earth is targeting early-stage teams with slick onboarding flows. But when there are only two of you, the best tech stack is the one you'll actually use every day. Here's what that looks like in practice, broken down into the five slots that genuinely matter.

Detail of hands holding two smartphones, showcasing modern technology usage.

Email That Does More Than Send Messages

This sounds obvious, but your email provider is doing more heavy lifting than you think. Google Workspace or Microsoft 365 will give you a professional domain, shared inboxes, and enough storage to last your first year without thinking about it.

Pick one. Don't split it. If one founder lives in Gmail and the other in Outlook, you'll waste hours forwarding things back and forth. Agree early on a single provider and stick with it. The admin overhead of switching later is worse than compromising now.

A Shared Calendar You Both Trust

When your team is two people, missed meetings kill momentum fast. A shared calendar sounds basic, but it becomes the heartbeat of how you coordinate. Block time for deep work, flag investor calls, and mark deadlines where both of you can see them.

Google Calendar or Outlook Calendar will handle this fine. The key is making sure both founders actually put things in it. A calendar only works if it reflects reality, not just one person's version of the week.

One Place to Track Relationships

This is where most early teams get it wrong. You're emailing potential customers, talking to investors, following up with partners, and none of it lives in one place. Conversations fall through the cracks because they're scattered across inboxes, sticky notes, and half-remembered Slack messages.

You don't need a giant enterprise system for this. There are plenty of lightweight options among the best CRMs for early stage startups, and most of them do far more than a spreadsheet without the setup headache of an enterprise system. The point is to have a single source of truth for every relationship that matters to the business, whether that's a lead, a supplier, or a mentor you met at a conference last month.

Get this in place early. Rebuilding your contact history from scattered emails six months down the line is painful, and you'll lose things along the way.

Automation Glue to Connect the Gaps

Zapier, Make, or even basic built-in integrations will save you hours every week. The goal isn't to build some elaborate automation empire. It's to handle the small, repetitive tasks that eat into your day: logging form submissions, sending follow-up reminders, copying data between tools.

Start with one or two automations that solve an obvious pain point. A good first candidate is something like "when someone fills out our contact form, create a record in the CRM and ping us in our chat app." That alone removes a manual step you'd otherwise forget on a busy Tuesday.

A Single Home for Files

Dropbox, Google Drive, or OneDrive. Pick one. Share a folder structure. Done.

The mistake founders make is letting files live everywhere: some in email attachments, some on desktops, some in random Notion pages. When there are two of you, it takes about ten minutes to agree on a folder layout. Do it on day one and save yourself months of "where did that pitch deck go?"

Five Tools, Not Fifty

The pressure to adopt every new app is constant. Product Hunt will tempt you daily. But a two-person startup doesn't need a stack. It needs a spine: email, calendar, a CRM, automation glue, and shared files. Everything else is a distraction until you've outgrown these basics.

The founders who move fastest aren't the ones with the fanciest tools. They're the ones who picked five things, committed to them, and spent the rest of their time actually building.

How Teams Turn Video and Audio Recordings Into Searchable Notes

A recorded meeting usually feels useful right after it ends. Everyone remembers the discussion, the decisions, and the important points. The problem appears weeks later when someone needs to find one specific detail.

Maybe a product manager wants to confirm why a feature was postponed. Maybe a sales team needs the exact wording a customer used during an interview. Maybe someone remembers that an important decision was made, but nobody remembers which recording contained it.

The information still exists. It is just difficult to reach.

This is why many teams turn recordings into searchable text. A transcript does not replace the original video or audio. It creates another way to access the information inside those files.

A practical video and audio transcription workflow helps teams spend less time searching through recordings and more time using the information they already collected.

Why Recorded Information Becomes Difficult to Use

Most teams do not struggle because they lack information. They struggle because information is stored in formats that are difficult to search.

A one hour meeting recording may contain only a few sentences that matter. A customer interview may include one useful comment that influences a product decision. A training video may explain a process that someone needs months later.

Finding these moments by moving through a timeline is slow. People often remember the topic of a conversation but not the exact time when it happened.

Text changes this process. Once a recording becomes searchable, people can look for specific terms, review relevant sections, and return to the original file when they need more context.

The purpose of transcription is not to turn every recording into something people read from beginning to end. It is to make stored knowledge easier to find.

Turning Video Recordings Into Searchable Text

Video recordings often contain information that disappears after the first viewing. A meeting might be watched once, a product demonstration might be shared with one team, and an interview might stay untouched after it is completed.

The challenge comes later when someone needs to recover a specific detail.

A video to text converter can create a searchable version of the recording, allowing teams to locate important parts without manually watching the entire file again. A team can use a video to text converter to review long recordings, find relevant sections, and create notes based on the original conversation.

For example, a product team reviewing customer interviews may not need to watch every conversation again. They may first search the transcript to find repeated feedback, then return to the video to understand the speaker’s tone and the surrounding discussion.

The transcript helps people locate information. The original recording keeps the full context.

Working With Audio Recordings From Meetings and Interviews

Not every valuable conversation is captured as video.

Many teams collect information through audio files. These can come from customer interviews, podcasts, phone recordings, voice notes, or exported meeting recordings. The content may be useful, but finding a specific sentence inside a long audio file can be just as difficult as searching through video.

In these situations, teams often need to transcribe audio files and keep the written version connected to the original recording.

Audio transcription is especially useful when the main value is in the spoken conversation itself. A researcher may need to compare interview responses. A marketing team may want to review customer language. A manager may need to revisit a previous discussion before making a decision.

The transcript provides a practical reference, but unclear sections still need to be checked against the original audio. Names, numbers, and technical terms are easy places for mistakes to appear.

Keep the Original Transcript Separate From Team Notes

A transcript and a summary solve different problems.

The raw transcript keeps a record of the conversation. It allows people to check what was actually said when questions appear later. The working notes should focus on information that helps people move forward.

For example, after a product meeting, the transcript may contain the full discussion about different ideas, concerns, and possible solutions. The final team notes may only need the decision that was made, the person responsible for the next step, and the reason behind that decision.

Keeping these two documents separate prevents an important problem. Teams sometimes summarize a conversation too early and remove details that become useful later.

A customer interview is a good example. A short summary may mention that customers want a simpler workflow, but the original transcript may contain the exact words customers used and the situations that caused frustration. Those details can become valuable when creating product improvements or customer communication.

A useful habit is to keep the transcript, summary, and original recording connected. When someone needs more context, they can move from the written notes back to the source.

Review the Parts That Matter Before Sharing

Automatic transcription can save a large amount of time, but not every part of a recording has the same importance.

A small spelling mistake in a casual conversation may not matter. A wrong name, number, product term, or customer statement can create confusion if the transcript is later used for a decision or shared outside the team.

Most review work should focus on areas where accuracy affects the outcome.

For example, a sales team reviewing a customer call should pay attention to the customer’s requirements and specific feedback. A product team checking a meeting transcript should verify decisions and technical details. A researcher using interview transcripts should confirm quotations before publishing them.

The goal is not to manually correct every sentence. It is to make sure important information is reliable.

Common Problems Teams Face With Transcription

Transcription usually works well when the recording quality is clear, but real conversations are rarely perfect.

People speak at different speeds. Several speakers may talk at the same time. Some names, industry terms, or product names may not be recognized correctly. A poor microphone or background noise can also affect the result.

These issues do not make transcripts useless. They simply show where human review is needed.

When a sentence looks unclear, the safest approach is to check the original recording instead of guessing. A transcript should help people find information faster, not create false confidence about information that needs confirmation.

Speaker labels can also be useful for conversations with multiple people, but they should be reviewed before a transcript becomes an official record. Automated labels are helpful for navigation, but they are not always perfect.

Build a Simple Workflow Around Recorded Content

A transcription workflow does not need complicated systems or additional administrative work.

The most practical approach is usually simple. Keep the original recording, create a transcript, review the sections that will actually be used, and store the related files together.

The important part is consistency.

A team that records customer interviews every week will benefit from using the same naming style and storage method. A meeting from six months ago becomes much easier to find when the file name includes the project, date, and purpose instead of a name like Final Meeting Recording.

Over time, these small habits turn old recordings into a useful knowledge source instead of forgotten files.

When a Transcript Is Not Enough

Text makes recordings easier to search, but it cannot capture everything.

A video may show a product demonstration that requires visual explanation. An interview may include tone, hesitation, or reactions that change how a statement should be understood. A meeting may contain context that is difficult to represent in written form.

This is why the original recording should remain part of the workflow.

A transcript is most useful when people use it as a way to find information and then return to the source when accuracy matters.

Before publishing a quote, sharing customer information, or using a transcript for an important business decision, review the relevant section in the original recording.

Turn Existing Recordings Into Usable Knowledge

Many teams already have valuable information stored in recordings. The problem is that this information often stays hidden because finding it takes too much time.

A searchable transcript changes how people interact with recorded content. Instead of remembering when something happened, they can search for the topic and quickly return to the relevant moment.

This is useful for teams that regularly work with meetings, interviews, training materials, and customer conversations.

The value of transcription is not creating another file. It is making existing information easier to access when someone needs it.

Keep Human Judgment in the Workflow

A video and audio transcription process works best when automation handles the repetitive part and people handle the decisions.

A video to text converter online free can help create a searchable version of a recording quickly, while human review ensures that important information remains accurate.

The same principle applies to audio transcription. Tools can help teams process large amounts of spoken content, but the people who understand the conversation still decide what information matters.

The most reliable workflow is straightforward. Create a searchable transcript, check the sections that affect decisions, and keep the original recording available for reference.

Recorded conversations often contain knowledge that teams need later. A good transcription workflow simply makes that knowledge easier to find.

How Audio Management is Changing Police Investigations

Police investigations have always depended on audio, even before most departments thought of it as a distinct category of evidence. Emergency calls, witness interviews, suspect interrogations, radio traffic, jail calls, body-worn camera soundtracks, and surveillance captures all shape what investigators know and what they can prove. What has changed is the scale.

A modern case can generate hours of recorded material before an officer writes the first formal report. That creates both opportunity and pressure. Done well, audio management helps investigators move faster, preserve context, and reduce the risk of missing crucial details. Done poorly, it turns into a storage problem, a disclosure headache, and a source of avoidable error.

The shift matters because audio is not just supporting evidence anymore. In many cases, it is the timeline.

Metro Police officer on a motorcycle patrolling the streets of Nashville, TN.

From Supplementary Evidence to Investigative Core

For years, recorded audio often sat in silos. Dispatch kept 911 calls, detectives stored interviews separately, detention facilities managed inmate calls, and body-camera footage lived in another system altogether. Investigators had to pull fragments from each source and manually piece them together.

That approach no longer fits the reality of digital policing. Cases now involve multiple agencies, enormous volumes of media, and strict disclosure obligations. Audio management has moved closer to the center of investigative work because it helps answer three practical questions faster:

What happened first?

Timestamps across recordings can reconstruct events with surprising precision. A 911 call, a patrol radio transmission, and body-worn audio may each tell only part of the story, but aligned together they create a clearer sequence than witness recollection alone.

Who said what, and in what context?

Transcripts are useful, but they flatten meaning. Tone, interruption, hesitation, stress, and background noise often change how a statement should be interpreted. Good audio management keeps those layers accessible instead of burying them in disconnected archives.

What needs to be shared, reviewed, or protected?

Investigators, prosecutors, defense counsel, supervisors, and sometimes civilian oversight bodies all need access to different parts of the same record. Managing that access is now an operational requirement, not an administrative afterthought.

The New Demands on Investigators

Better audio collection has created a paradox: departments have more evidence than ever, but not necessarily more time to process it. Listening to hours of interviews or calls is labor-intensive. So is finding one name, one threat, or one contradiction buried in a long recording.

That is why audio management increasingly overlaps with workflow design. Investigators need systems that make recordings searchable, linkable to case files, and easy to review without compromising evidentiary integrity. They also need methods for handling sensitive material. In practice, a recording may contain a victim’s address, a juvenile’s identity, medical information, or the voice of a confidential source. Sharing the whole file without safeguards can create new risks.

This is where techniques such as transcription, speaker separation, metadata tagging, and anonymising investigative recordings become especially relevant. Not because they replace investigative judgment, but because they make it easier to circulate usable evidence while protecting privacy, complying with disclosure rules, and limiting unnecessary exposure of vulnerable people.

Why Audio Management Improves Case Quality

The most obvious benefit is speed, but the deeper advantage is consistency. When recordings are organized properly, investigators are less dependent on memory and less likely to overlook material that does not fit an initial theory.

Stronger timelines

A scattered case file invites gaps. Centralized audio lets investigators compare accounts against dispatch records, verify when officers arrived, and test whether witness descriptions line up with what was reported in real time. That can sharpen a charging decision or reveal that a promising lead is weaker than it first appeared.

Better interview analysis

Interviews are not just about what is admitted. They are about progression. Did a suspect change details after being confronted with evidence? Did a witness become more certain over time, or less? Reviewing audio in a structured way helps detectives spot those shifts, especially when several people are handling the same investigation.

More defensible disclosures

Courts and defense teams increasingly expect digital evidence to be produced in an orderly, reviewable form. If a department cannot locate key recordings quickly, document edits, or show how sensitive information was handled, even solid investigative work can come under pressure. Audio management supports the chain of custody in a practical sense: not only preserving the file, but preserving trust in how it was used.

The Privacy and Disclosure Balancing Act

This is where many agencies still struggle. The same recording may be highly valuable evidentially and highly problematic operationally. A child witness statement, for example, may need to be reviewed by multiple parties while also requiring careful restriction of identifying details. A public records request may capture material that cannot ethically or legally be released as-is.

Technology helps, but policy matters just as much. Departments need clear rules on retention, access permissions, redaction standards, and audit trails. Without that governance layer, even sophisticated tools can produce inconsistent outcomes.

What good practice looks like

The strongest agencies tend to focus on a few basics:

  • standard naming and tagging conventions for recordings
  • audit logs showing who accessed or edited files
  • processes for transcription and quality review
  • redaction protocols for protected identities and sensitive details
  • integration between audio systems and case management platforms

None of this is glamorous, but it is exactly what prevents avoidable mistakes when a complex case goes to court.

What Investigators Should Expect Next

Audio management is heading toward greater automation, but not full autonomy. That distinction matters. Tools can already surface keywords, identify speakers, flag probable sensitive information, and generate draft transcripts. Those capabilities save time, especially in high-volume units handling domestic abuse cases, narcotics investigations, or major incident reviews.

Still, automation works best as triage. A transcript can miss sarcasm. Speaker identification can falter in chaotic environments. Redaction suggestions may still require human review. The near future is not about replacing detectives with software; it is about reducing the manual burden so experienced investigators can spend more time interpreting evidence instead of hunting for it.

That is ultimately why audio management is changing police investigations. It is not merely a technical upgrade. It is a shift in how agencies treat one of their richest evidence sources: from something stored after the fact to something actively managed throughout the life of a case.

A detective adjusting a tape recorder during an investigation with photos spread on a table.

The Bigger Investigative Payoff

When audio is well managed, investigations become clearer, faster, and fairer. Investigators can test timelines more confidently, prosecutors can prepare disclosures more effectively, and departments can better protect the people whose voices end up in the record.

In an era of expanding digital evidence, that is not a minor operational improvement. It is a foundational capability.

Segmentation in Image Processing: How Machines Learn to See in Parts

Before an AI model can identify a tumor on a scan, steer a car around a pedestrian, or separate a product from its packaging in a photo, it first needs to break the image down into meaningful pieces. That process — segmentation in image processing — is one of the most fundamental techniques in computer vision, and understanding how it works helps explain why so much of modern AI depends on precise, human-driven data annotation.

What Segmentation Actually Means

At its core, image segmentation is the process of dividing a digital image into smaller, meaningful groups of pixels called segments. Rather than treating an image as one undifferentiated block of visual data, segmentation assigns labels to individual pixels so that specific objects, people, or regions can be identified and analyzed separately.

Think of a photo of a busy street. Without segmentation, a computer just sees a grid of color values. With segmentation, it can isolate the car, the pedestrian, the traffic light, and the road surface as distinct, labeled regions — each one something the model can reason about independently.

This matters because processing an entire image at once is computationally expensive and often unnecessary. By narrowing the model’s attention to relevant segments first, algorithms become faster, more accurate, and better suited to real-world applications like object detection.

The Three Main Types of Segmentation

Not all segmentation serves the same purpose. Broadly, it falls into three categories:

Semantic segmentation groups pixels according to their semantic class — every pixel belonging to “road,” “sky,” or “person” gets the same label, regardless of how many individual objects of that type appear in the image. This is useful when the model only needs to know what’s present, not how many distinct instances exist.

Instance segmentation goes a step further by distinguishing between individual objects of the same class. Instead of labeling all pixels as “person,” it separately identifies Person A, Person B, and Person C, even if they’re standing next to each other in the frame.

Panoptic segmentation is a more recent approach that combines the two, delivering both class-level understanding and individual instance separation in a single unified output. It’s increasingly the standard for applications that need a complete scene understanding, such as autonomous driving systems.

Common Techniques Used to Perform Segmentation

Several technical approaches exist for actually carrying out segmentation, each suited to different types of images and use cases:

  • Edge-based segmentation — identifies the boundaries of objects by detecting sharp changes in pixel intensity, useful for images with clear contrast between subject and background.
  • Threshold-based segmentation — separates pixels into groups based on intensity values, a simple but effective method for high-contrast images.
  • Region-based segmentation — groups pixels according to similarity in color, texture, or intensity within a defined area.
  • Cluster-based segmentation — uses algorithms to group pixels with similar characteristics into distinct clusters without requiring predefined boundaries.

More advanced projects increasingly rely on deep learning architectures to handle these tasks at scale, but even the most sophisticated models are only as good as the training data they learn from — which is where human annotation enters the picture.

Manual vs. Automated Segmentation

There are two general paths to producing segmented training data:

Manual segmentation relies on human annotators to label images by hand, applying semantic segmentation, instance segmentation, or other methods based on carefully defined project guidelines. This approach tends to produce the highest-quality ground truth data, particularly for complex or ambiguous images where automated tools struggle.

Automated segmentation uses machine learning algorithms to perform segmentation tasks with minimal human input. While faster, automated methods typically still require validation work to catch errors, especially in edge cases involving occlusion, poor lighting, or unusual object shapes.

In practice, most production-grade AI projects use a hybrid approach — automated pre-labeling followed by human review and correction — to balance speed with accuracy.

Where Segmentation Shows Up in Real Applications

Segmentation isn’t a theoretical exercise; it’s embedded in AI systems people interact with regularly:

  • Autonomous vehicles use segmentation to distinguish roads, lane markings, pedestrians, and other vehicles in real time.
  • Medical imaging relies on segmentation to isolate organs, lesions, or abnormalities in scans, supporting diagnostic accuracy.
  • Retail and e-commerce use it to separate products from backgrounds for catalog automation and visual search.
  • Agriculture applies segmentation to satellite and drone imagery to assess crop health and identify problem areas in fields.
  • Security and surveillance systems use it to isolate individuals or objects of interest within a monitored scene.

Why the Human Element Still Matters

Despite advances in automated tools, segmentation quality still hinges heavily on well-annotated training data. Models learn their boundaries from examples, and if those examples are inconsistent or imprecise, the resulting segmentation will inherit those same flaws — often in ways that are difficult to detect until the model is already in production.

This is precisely why experienced data annotation teams remain central to building reliable computer vision systems. Producing large volumes of accurately segmented images — whether through semantic, instance, or panoptic methods — requires trained annotators who understand both the technical requirements of the task and the nuances of the specific industry the data comes from, whether that’s automotive, healthcare, retail, or agriculture.

Final Thoughts

Segmentation is deceptively simple in concept but demanding in execution. Getting it right requires a clear understanding of which technique fits a given use case, the right balance between manual precision and automated efficiency, and — above all — consistently high-quality labeled data to train the underlying models. As computer vision applications continue to expand into new industries, the demand for accurately segmented datasets, and the skilled teams capable of producing them, will only continue to grow.

How to Check If a Domain Name is Available (and What to Do If It's Taken)

A name can feel finished before it is actually usable. The logo looks fine. The social handle is close enough. Then a quick domain check spoils it: the .com is registered, the name is premium, or the only free version sits on an extension nobody wanted.

That is why the domain should be checked before the name goes on ads, packaging, invoices, or launch emails. Early, it is a small naming issue. Later, it becomes a branding problem.

For a broad search across extensions, name.com offers more than 600 TLD options, from familiar choices such as .com to alternatives including .ai and .pro. That can make it easier to test a close variation when the first choice is taken, while transparent pricing and 24/7 technical support help you assess the next step without guesswork.

pexels-photo-6958452.jpeg

Why Checking Domain Availability Matters

An early domain name search protects the launch timeline. If the first choice is gone, there is still time to adjust the name, choose another extension, or rethink the brand before money has been spent around it.

It also protects credibility. A good domain is easy to remember, say, and type after someone hears it once. If customers cannot find the site later, the name is already working against the business.

Cost is the other reason. Finding a domain name taken after design work is finished can push people into bad choices: an awkward extension, a rushed rename, or an overpriced premium domain bought out of frustration.

How to Check if a Domain Name Is Available

The quickest way to check domain availability is with a domain availability checker. It gives a fast answer and often shows close variations, other extensions, and domain name alternatives.

A proper check should still look in more than one place:

  • Use a checker first for a quick result and nearby options.
  • Run a WHOIS or RDAP lookup to see registration status, registrar, and expiry date. These are public registration lookup systems, though owner contact details are often hidden because of privacy rules and GDPR.
  • Type the address into a browser, but treat that only as a clue. A blank page does not mean the domain is free.

A registered domain can show nothing. It may be parked, unused, badly redirected, or not connected to hosting. Before the name goes into a campaign plan, confirm it with a real domain name check.

What a Domain Name Check Actually Tells You

When you check domain name availability, the result usually lands in one of three places:

  • Available: the domain is open to register. Good names can disappear quickly.
  • Taken: the domain is already registered. It may still be parked, unused, or close to expiry.
  • Premium: the domain can be bought, but not at a normal registration price. Short, clean, brandable names often end up here.

So domain name availability is not always a simple yes or no. “Taken” does not always mean impossible. It means the next move needs more thought.

What to Do If the Domain Name Is Taken

The instinct is usually to chase the exact .com. Sometimes that is worth doing. Just as often, it slows the launch for a name that may never sell at a sensible price. A registered domain is a decision point, not a wall.

If you are searching for what to do if domain name is taken, start with the cheaper fixes first.

  • Try another extension. A .net, .org, .info, .shop, .co, .de, or .eu may work if it fits the audience. A German business can look natural on .de. A European project may consider .eu. The trade-off is habit: many people still type .com first. Some country extensions also have rules, such as .eu, requiring a presence in the EU or EEA.
  • Adjust the name. Add a descriptor, action word, or location. Northline could become Northline Studio, Try Northline, or Northline Berlin. Keep it easy to say. One hyphen can help readability. Several hyphens make a name look cheap.
  • Try to buy it. People do buy domains that are taken, but this is where the price can get emotional. A WHOIS lookup may show the expiry date, not the owner’s private details. Contact usually happens through an anonymized email, a registrar form, or a broker. Use escrow, and set a walk-away price before making an offer.
  • Wait and watch. A backorder is a request to register the domain if it becomes available. This can work, but expired domains often pass through grace and redemption periods before release.

Before paying serious money, check trademarks. The question is not only how to get a domain name that is taken. It is whether the name is safe to build a business around.

How to Choose Between Available Domain Names

Good available domain names are not just technically open. They need to survive real use.

The name should be short enough to remember and clear when spoken aloud. Digits create doubts: should the number be typed or spelled out? Hyphens do the same. Every extra explanation makes the domain weaker.

The extension should fit the market. A local German company can look credible on .de. A European brand may use .eu. A shop can sometimes carry .shop. For a broad international business, .com still has the advantage of being the version many users assume first.

Say the domain out loud once. If someone can type it without asking how it is spelled, it is probably usable.

Getting to a Name You Can Register

Finding a domain is rarely a straight line. Start with a proper check, read the result carefully, and do not treat a taken name as the end of the project. Sometimes the better answer is a different extension. Sometimes it is a cleaner variation. Sometimes it is walking away before the name becomes too expensive.

Availability moves all the time. A name that is open today can be gone tomorrow, and a parked domain may later appear in the aftermarket. Anyone trying to find available domain names should check early and keep a small shortlist instead of building the whole launch around one fragile choice.

The aim is not to win the perfect domain at any price. It is to choose a name people can remember, trust, and type without friction. Flexibility usually gets a business there faster than waiting for a domain that may never become available.

Transform Your Photos with Digital Facial Hair: A Complete Guide to Photo Enhancement Tools

Digital photo manipulation has evolved dramatically over recent years. What once required expensive software and professional skills now sits within reach of anyone with a smartphone. Among the most entertaining transformations? Adding facial hair to portraits.

The practice might sound frivolous at first glance. Yet these tools serve purposes beyond simple amusement. Historical recreations benefit from accurate period facial hair. Theater productions need promotional materials showing actors in character. Social media campaigns rely on eye-catching visual gimmicks.

Why Digital Facial Hair Enhancement Matters

Photography enthusiasts and casual users alike discover value in facial hair editing tools. The technology addresses several practical needs.

Costume designers preview looks before committing to physical makeup. Marketing teams test visual concepts without expensive photoshoots. Individuals explore potential style changes without growing actual facial hair for months.

The applications extend beyond personal use. Family historians restore and enhance old photographs. Content creators generate themed material for specific holidays or events. Professional photographers offer clients expanded portfolio options.

Understanding the Technology Behind Facial Enhancement

Modern facial recognition systems power these transformation tools. Algorithms identify key facial landmarks with remarkable precision. The software maps nose position, mouth corners, and chin contours.

Machine learning models trained on thousands of images understand how facial hair naturally appears. The technology considers lighting conditions, skin tone, and face angle. Sophisticated rendering ensures additions blend seamlessly with existing features.

Processing happens in seconds rather than hours. Cloud-based systems handle the computational heavy lifting. Users receive results without downloading massive software packages or possessing technical expertise.

Popular Applications for Mustache Photo Editing

Social media drives much of the demand for these tools. Platforms reward novel, shareable content. A well-executed facial hair transformation generates engagement and conversation.

Holiday cards present another common use case. Families create themed portraits for various celebrations. November health awareness campaigns particularly benefit from mustache-themed imagery.

Professional contexts increasingly embrace these technologies. Casting directors visualize actors in period roles. Authors create character reference sheets for book covers. Game developers prototype character designs before committing artist resources.

Educational projects gain visual interest through historical figure recreations. Students bring textbook personalities to life. Teachers make lessons more engaging with humorous adaptations of famous portraits.

Choosing the Right Tool for Your Needs

Numerous platforms offer facial hair editing capabilities. Selection depends on intended use, desired quality, and technical comfort level.

Mobile applications prioritize convenience and speed. Desktop software provides more precise control and higher resolution outputs. Web-based tools split the difference, offering accessibility without installation requirements.

Free versions typically include basic features with occasional advertisements or watermarks. Premium subscriptions unlock advanced options like custom styling, batch processing, and commercial usage rights.

For those seeking straightforward results, you can easily add mustache to photo using dedicated online platforms that streamline the entire process with intuitive interfaces and instant previews.

Step-by-Step Enhancement Process

The transformation process follows a consistent pattern across most platforms. Begin by selecting a clear, well-lit photograph. Front-facing angles yield the best results, though profile views work with advanced tools.

Upload the image to your chosen platform. The system analyzes facial structure and positioning. Most tools display detected features for verification before proceeding.

Browse available styles ranging from subtle stubble to elaborate handlebar designs. Preview options show how each style appears on your specific photo. Adjust size, color, and position to achieve the desired effect.

Fine-tune the result using available controls. Modify opacity for a more natural appearance. Rotate or shift placement to align with facial contours. Some platforms allow texture adjustments to match skin characteristics.

Export the final image in your preferred format and resolution. Higher quality outputs suit printing and professional use. Compressed versions optimize for web sharing and faster loading times.

Advanced Techniques for Realistic Results

Achieving convincing results requires attention to subtle details. Lighting consistency separates amateur edits from professional-grade work. Facial hair should reflect the same light source as the original photograph.

Color matching proves critical for believability. Natural facial hair rarely presents as a single uniform shade. The best results incorporate subtle color variations and highlights that complement existing hair tones.

Scale and proportion dramatically affect realism. Oversized additions appear cartoonish. Undersized elements look unconvincing. Study reference images to understand appropriate sizing for different facial structures.

Edge treatment distinguishes polished work from obvious edits. Harsh boundaries scream artificial manipulation. Feathered edges and varied density create natural transitions between added elements and skin.

Common Challenges and Solutions

Poor source image quality limits potential outcomes. Low resolution photos lack detail necessary for seamless integration. Blurry or heavily compressed images exaggerate artificial elements.

Extreme angles complicate the enhancement process. Three-quarter views require careful positioning to maintain perspective. Profile shots demand specialized techniques to avoid flat, pasted-on appearances.

Skin texture mismatches reveal digital manipulation. Smooth, filtered facial hair contrasts jarringly with natural skin pores and texture. Advanced tools address this through texture overlay features.

Color space differences between the original photo and added elements create visual discord. Converting both to the same color profile ensures consistency. According to industry technology experts, attention to these technical details separates professional results from amateur attempts.

Creative Applications Beyond Basic Enhancement

The technology enables imaginative projects beyond straightforward additions. Composite images place historical figures in modern contexts. Themed party invitations feature guests in period-appropriate styling.

Businesses leverage these tools for branding campaigns. Seasonal promotions benefit from playful employee photos. Product launches gain attention through unexpected visual hooks.

Artists use facial hair manipulation as a starting point for broader transformations. The technology integrates with other editing tools for comprehensive image overhauls. Digital art projects incorporate elements as texture sources or compositional components.

Genealogists enhance damaged or incomplete historical photographs. Missing or faded details receive careful reconstruction. Families gain clearer connections to ancestors through restored imagery.

Privacy and Ethical Considerations

Photo manipulation raises important questions about consent and representation. Always secure permission before altering images of other people, particularly for public distribution.

Commercial use demands heightened caution. Model releases and usage rights prevent legal complications. The Federal Trade Commission provides guidelines regarding manipulated imagery in advertising contexts.

Platform terms of service govern acceptable use. Most prohibit deceptive or malicious applications. Creating misleading content or impersonating others typically violates community standards.

Transparency about digital manipulation maintains trust. Clearly identifying enhanced images prevents misunderstanding. Entertainment contexts allow more flexibility than news or documentary applications.

Future Developments in Photo Enhancement Technology

Artificial intelligence continues advancing at a remarkable pace. Next-generation tools will offer even more realistic results with less manual adjustment. Real-time video enhancement already emerges in experimental platforms.

Augmented reality integration promises interactive experiences. Users might preview facial hair styles before committing to actual grooming changes. Virtual try-on features could revolutionize personal care product marketing.

Accessibility improvements will democratize advanced capabilities. Simplified interfaces require less technical knowledge. Voice commands and gesture controls may replace traditional editing workflows.

Customization options will expand beyond preset styles. Users might upload reference images for exact replication. Machine learning could generate entirely novel styles based on described preferences.

Maximizing Results with Supporting Edits

Facial hair additions work best as part of comprehensive editing. Background adjustments draw attention to the subject. Lighting corrections ensure consistent illumination across all elements.

Color grading unifies the overall aesthetic. Applying subtle filters helps added elements blend naturally. Vignetting focuses viewer attention on facial features.

Complementary adjustments enhance the transformation. Hairstyle modifications maintain stylistic consistency. Wardrobe changes complete period-appropriate looks. Contextual elements support the overall narrative.

Proportional editing maintains believability. Facial hair changes affect perceived face shape. Subtle adjustments to other features preserve natural appearance. Balance prevents any single element from dominating the composition.

Learning Resources and Community Support

Online communities share techniques, styles, and inspiration. Forums dedicated to photo editing offer troubleshooting assistance. Video tutorials demonstrate advanced methods step by step.

Template libraries provide starting points for common projects. Style collections showcase possibilities and spark creativity. User-generated content demonstrates real-world applications across diverse contexts.

Practice remains the most effective learning method. Experimentation reveals tool capabilities and limitations. Comparing results against professional work identifies areas for improvement.

Feedback from other users accelerates skill development. Constructive criticism highlights overlooked details. Collaborative projects expose alternative approaches and techniques.

Digital facial hair enhancement represents just one facet of modern photo editing capabilities. The technology continues evolving, offering increasingly sophisticated results accessible to users at all skill levels. Whether for professional projects, creative exploration, or simple entertainment, these tools open new possibilities for visual expression and communication.

Business Software Integrations That E-Commerce Teams Are Prioritizing in 2026

E-commerce integration work looks different in 2026 because software is gaining the ability to act. Traditional integrations moved records between applications after a predictable trigger. AI agents can interpret a request first and then decide which connected system should handle the next step. That shift changes what teams need from their software stack.

The shift is visible across fulfillment, customer service, inventory, and order management. A shipping automation platform, for example, depends on accurate order and inventory data if it is expected to make useful decisions without constant employee input. Similar requirements apply to AI-first support tools and other applications that act on live commerce data rather than simply displaying it.

As these workflows become more autonomous, e-commerce teams are paying closer attention to how their systems communicate and where human approval still belongs. Insights from Shipduo helped inform this operational perspective, alongside broader developments in agentic commerce, AI-first applications, cloud infrastructure, and cybersecurity. The priority for 2026 is increasingly clear: integrations need to support faster automation without weakening control over business data or system access.

Two professionals collaborating using laptops and communication software in a business setting.

Integrations Are Becoming Agent-Ready

AI agents have moved into a more operational phase this year. New commerce protocols are being developed around software that can discover products and carry a transaction forward with less human input. At the same time, NIST launched an AI Agent Standards Initiative in February 2026 with a focus on secure interoperability. For e-commerce teams, the practical implication is straightforward. Business systems increasingly need interfaces that software agents can use reliably instead of interfaces designed only for conventional application-to-application syncing.

Agent-ready integration also raises the standard for API design. An agent needs enough structured context to determine what an action means before executing it. Clear error responses become more valuable because autonomous software must know when to stop instead of repeatedly attempting a failed operation. E-commerce teams evaluating integrations in 2026 should therefore examine the behavior behind the connector rather than treating the presence of an API as proof that the systems can work well together.

Operational Data Needs a Reliable Source

AI-driven commerce depends heavily on current operational data. A product recommendation loses value when the underlying inventory record is old. Automated customer support becomes risky when the application cannot see a recent order change. The same problem appears when an agent tries to answer a delivery question using information that updated several hours earlier.

This is giving real-time synchronization more weight. Older integrations often relied on scheduled batch updates because a short delay had limited consequences. AI-first applications create a stronger need for current context because they may make an immediate decision from the information available at that moment. Event-driven connections are useful here because a change can be passed to another system soon after it occurs instead of waiting for the next scheduled sync.

Teams should also define which application owns each important record. Two systems that can overwrite the same field without a clear authority rule can create difficult data conflicts. AI makes those conflicts harder to diagnose because an automated action may occur before an employee notices the disagreement. A clean integration architecture gives each system a defined role and records changes well enough that another application can determine where the current value originated.

Shipping Integration Is Moving Closer to Commerce Logic

Fulfillment software used to receive an order near the end of the purchase process. That boundary is becoming less distinct. Shipping information can influence the customer experience before checkout finishes because delivery expectations depend on data from operational systems. A useful integration therefore has to connect the commercial promise with what fulfillment can actually execute.

This becomes particularly relevant when merchants use several fulfillment locations. Available inventory may be physically closer to the customer at one location, but another location may be better able to meet the required delivery date. Software can make a better routing decision when inventory information and shipping logic are connected early enough in the process. The resulting integration is more sophisticated than sending a completed order to a warehouse after payment.

Returns create the same need in reverse. An incoming return can affect inventory availability before the item is physically ready for resale. Refund activity may also need to reach customer records quickly so an AI support system does not act on outdated information. E-commerce teams are therefore treating shipping integration as part of a larger operational data flow rather than a final connector added after the storefront is complete.

AI-First Apps Need Controlled Cloud Context

The rise of AI-first applications is changing cloud integration architecture. These applications are designed around model-driven interactions from the beginning instead of adding a chatbot to conventional software. Their usefulness depends on access to business context. From a technical perspective, giving them broad access to every connected system would be easy, but it would create unnecessary exposure.

A stronger design gives the AI application only the context required for the current task. The same principle applies to actions. An agent that needs to check an order should not automatically gain authority to issue a refund. If higher-risk action becomes necessary, the workflow can require additional authorization before the connected application accepts it. This keeps AI capability separate from unrestricted system privilege.

Cloud architecture also needs better observability as these workflows become more autonomous. Teams need to know which agent initiated an action and what system accepted it. They should be able to reconstruct the context that led to an important automated decision. This is especially useful when an outcome appears valid in the final record, but the process used to reach it was wrong. Research published in 2026 on agentic commerce has reinforced the value of examining the action sequence rather than judging an automated system only by its final result.

Detailed view of a computer screen displaying code with a menu of AI actions, illustrating modern software development.

Cybersecurity Is Becoming Part of Integration Architecture

Agentic software expands the attack surface because an AI system can receive untrusted content and still possess legitimate access to business tools. NIST highlighted indirect prompt injection in 2026 research on agent hijacking. An attacker may place malicious instructions inside content that an agent later processes. If that agent can call connected business systems with broad privileges, a content-level attack can become an operational security incident.

This is why identity and authorization are becoming integration concerns rather than separate security work performed afterward. Joint cybersecurity guidance published in May 2026 recommends limiting an agent's privileges and restricting the scope of its actions. Temporary credentials can further reduce exposure. E-commerce teams should know which machine identity is making each request and give that identity only the permissions required for its defined task.

Human approval remains useful at high-impact decision points. Automation can prepare an action and gather the context needed to support it. A person can authorize execution when the financial or customer consequence crosses a defined threshold. This does not weaken AI automation. It creates a safer boundary between routine machine work and decisions that carry greater downside.

The integration priorities that are emerging in 2026 indicate a shift toward a different software architecture for e-commerce. Connections need current data and clearer authority. AI agents need structured ways to interact with business systems. Cloud services need auditable access instead of unrestricted context. Shipping software needs deeper connections with the commercial workflow.

Your Customers Are Messaging You on WhatsApp. Your Odoo System Has No Idea.

Here is a scenario playing out in thousands of businesses right now. A customer places an order, then messages on WhatsApp asking when it will ship. The support agent has to stop, open Odoo separately, search for the order, then manually type a reply. Multiply that by fifty messages a day, and an entire team's time is being burned on work that should take zero manual effort.

This is not a small inefficiency. It is a structural gap between where customers actually communicate and where business data actually lives.

Detailed macro of smartphone screen showcasing popular app icons like WhatsApp.

The Problem: WhatsApp and Odoo Are Not Talking to Each Other

Most businesses running Odoo have built a solid operational backbone: sales, invoicing, inventory, and customer records, all in one place. But the moment a customer reaches out on WhatsApp, that system goes silent.

  • Support staff reply from a personal or shared phone, disconnected from the actual order record
  • Order updates get typed out manually, one customer at a time
  • Payment reminders are sent late, or not sent at all, because nobody remembered to follow up
  • Delivery status has to be checked and relayed by hand, every single time
  • There is no record of the conversation anywhere inside Odoo itself

None of this is a staffing problem. It is a systems problem, and it is costing businesses real time, real errors, and real customers.

Why This Gap Is More Expensive Than It Looks

WhatsApp is not a side channel anymore. It is where customers expect a response first.

  • WhatsApp message open rates sit between 95 and 98 percent, compared with just 20 to 25 percent for email
  • Customers typically respond within one to two minutes on WhatsApp, versus several hours for email
  • Active WhatsApp Business accounts have grown to roughly 284 million in 2026, up sharply from around 200 million the year before

When a business cannot respond on this channel with the speed customers expect, the cost shows up in slower payments, delayed deliveries flagged as complaints, and support tickets that should never have existed in the first place.

What Businesses Are Actually Losing Without This Connection

Break the daily cost down, and the picture becomes clear:

  • Wasted staff hours. Every manual WhatsApp reply is time a team member could have spent on higher-value work.
  • Delayed payments. Without automatic reminders, overdue invoices sit unpaid longer than they should.
  • Missed order updates. Customers left wondering about shipping status contact support instead of finding out automatically, doubling the workload.
  • No conversation history. When a WhatsApp chat lives only on someone's personal phone, the business loses that record the moment the employee is unavailable or leaves.
  • Inconsistent responses. Different agents reply differently, with no standard tied to the actual order data.

Every one of these problems has the same root cause: WhatsApp and Odoo are operating as two separate systems instead of one.

The Fix: Connect WhatsApp Directly to Odoo

The solution is not hiring more support staff or asking the team to work faster. It is removing the manual step entirely by connecting WhatsApp to Odoo at the system level, so messages fire automatically from real business events.

This is exactly what Elsner Technologies' WhatsApp Business Integration module for Odoo 19 was built to do. Rather than treating WhatsApp as a separate tool, it plugs directly into the modules already running the business, Sales, Invoicing, Inventory, and Contacts, and turns WhatsApp into an automated extension of Odoo itself.

Here is what changes once it is in place:

  • Order confirmations send themselves. The moment a sales order is confirmed, the customer receives a WhatsApp message with the order number, item summary, and total, with zero manual input.
  • Payment reminders go out on time, every time. Invoice and overdue payment reminders are sent automatically, with a direct download link, so customers never have to log into a portal.
  • Delivery updates happen in real time. Customers get notified the moment a shipment is dispatched or delivered, including tracking details.
  • All conversations live inside Odoo. A unified WhatsApp inbox means support and sales teams can view, filter, and respond without switching tools or relying on someone's personal phone.
  • A 24/7 chatbot handles the routine questions. Order tracking, payment status, and return requests get answered instantly, day or night, only escalating to a human when it actually needs one.
  • Bulk messaging is built in. Promotions, announcements, and follow-ups can go out to segmented customer lists directly from Odoo.

Why This Is a System, Not a Workaround

A lot of businesses try to solve this problem with a separate messaging app bolted on the side. That approach tends to create a second disconnected system instead of fixing the original one.

The advantage of a native Odoo integration is that it removes the gap entirely rather than shifting it somewhere else. Setting this up correctly does involve real technical groundwork, configuring the Meta WhatsApp Cloud API, mapping business events to message triggers, and testing across environments before going live. This is the kind of work that falls under proper Odoo development services, and getting it right the first time is what prevents missed webhooks, delayed messages, or Meta compliance issues down the line.

What to Check Before You Buy Any WhatsApp-Odoo Tool

Not every integration on the market solves the full problem. Before choosing one, confirm it covers:

  • Official Meta API usage — Unofficial methods risk account suspension entirely
  • Full trigger coverage — Order confirmations, payment reminders, and delivery updates, not just one notification type
  • A true unified inbox — Not a redirect to an external app
  • A working chatbot layer — So routine queries do not eat into support hours
  • Straightforward setup — Clear configuration steps rather than a vague integration promise

The Bottom Line

The businesses winning on customer experience right now are not the ones with more support staff. They are the ones who have removed the manual step between WhatsApp and their core system entirely.

If your team is still typing out order updates, chasing payment reminders by hand, or losing WhatsApp conversations the moment an employee logs off, the gap is not a staffing issue. It is a missing connection between two systems that should already be talking to each other.

For Odoo 19 users, closing that gap takes one module, not a rebuild. Elsner Technologies' WhatsApp Business Integration turns the channel your customers already prefer into a fully automated extension of the system you are already running.

The Most Effective Ways to Secure Your Business Building

Running a commercial facility requires constant attention to perimeter safety and internal asset protection. Physical threats, unauthorized access attempts, and break-ins create significant financial stress for company owners. Building an effective defense strategy involves combining structural barriers, smart surveillance, and modern digital monitoring tools. Taking proactive steps creates a safer work area for staff members and protects valuable assets around the clock. Proper safety measures reduce total insurance risks and give business leaders peace of mind during non-business hours.

photo-1462206092226-f46025ffe607

Centralizing Camera Oversight Across Locations

Surveillance camera installations form a core pillar in modern business defense strategies. High-definition camera systems using cloud vms options provide managers with seamless streaming access across mobile and desktop interfaces. Security personnel monitor real-time video feeds from distant facilities without needing localized recording racks.

Clear camera coverage deters property vandalism and offers evidence when incidents occur. Placing cameras near unloading docks, reception areas, and storage rooms secures sensitive assets. Proper camera angles leave zero blind spots around building perimeters.

High-resolution cameras capture critical details like vehicle license plates during nighttime hours. Storing video footage off-site prevents physical tampering or local drive destruction during a burglary attempt. Modern video setups give administration teams full oversight across multiple commercial properties through a single central dashboard.

Smart Site Design and Perimeter Security

Site planning forms the baseline defense for any commercial facility. Physical barriers, clear boundary markers, and strategic entry points guide visitor flow where security teams can monitor activity. Effective layout planning creates natural visual lines that discourage intruders before they approach doors.

Proper security layout relies on elements that deliver physical deterrence and clear site visibility simultaneously. Applying these architectural choices provides staff with better oversight of external parking zones and main entrances. Landscaping adjustments, such as trimming tall shrubs near windows, can prevent attempts at hidden entry.

Key perimeter elements include:

  • Heavy-duty fencing along outer boundaries
  • Clear line-of-sight lighting near all entrance doors
  • Reinforced gates with keycard access control points
  • Warning signage placed visible at perimeter fences

Implementing Advanced Access Control Systems

Traditional metal keys present serious risks if lost or copied by former employees. Modern electronic access control platforms solve this issue by issuing digital badges, mobile credentials, or biometric scans. Management teams track door usage in real time and restrict entry based on specific work shifts.

Updated security frameworks replace local server hardware with cloud platforms to manage door credentials remotely. Facility managers gain live data feeds and automatic software updates across multiple office locations without site visits. Digital access cards permit quick revocation when staff members leave the company.

Key features of modern access control:

  • Automated credential revocation for offboarded staff
  • Scheduled door locks for weekend hours
  • Detailed access logging for audit trails
  • Mobile phone unlocking capabilities for authorized personnel

Adopting Flexible Video Platform Architecture

Upgrading legacy video equipment to software platforms allows enterprise networks to scale effortlessly. Modern surveillance infrastructure relies on internet connectivity rather than local digital video recorders. This shift allows security leads to add new camera feeds instantly as business operations expand.

Industry research projects cloud video surveillance adoption to pass 60% of the US commercial market by 2027. Forward-looking organizations switch to software-driven management systems to accelerate operational efficiency. Centralized administrative tools reduce IT overhead while keeping video feeds accessible.

Modern video management platforms integrate smoothly into wider IT ecosystems. IT departments manage network permissions and video retention policies alongside regular software applications. System administrators adjust camera retention settings depending on legal requirements for different facilities.

Merging Physical Security Tools with Cybersecurity Protocols

Connected security hardware creates new entry points for digital network attacks. Smart locks, security cameras, and automated alarms connect directly to local networks, requiring strict cyber hygiene. IT teams must treat physical security hardware with the same rigor applied to corporate servers.

Top-performing organizations close potential security gaps by pairing physical access controls with cyber threat monitoring protocols. Combining these disciplines gives security leads a single unified view of operational events. Unified monitoring helps security teams detect physical breach attempts coordinated alongside digital attacks.

Regular firmware patching prevents unauthorized network intrusion through connected cameras. Strong password policies and network segmentation keep physical security data separate from primary business networks. Technical teams conduct frequent vulnerability scans across all connected cameras and access points.

Intelligent Threat Detection and Alarm Reduction

Traditional alarm systems often generate frustrating false triggers from passing wildlife or weather events. Modern surveillance systems integrate artificial intelligence algorithms to distinguish actual human threats from routine background movement.

Surveillance setups powered by AI algorithms record up to a 90% drop in false alarm incidents. Security teams focus attention on actual threat responses rather than chasing false alerts. Lower false alarm rates prevent expensive municipal fines for unnecessary emergency dispatches.

Automated alerts notify off-site managers immediately when suspicious activity occurs after business hours. Rapid response times reduce property damage and help law enforcement intercept trespassers quickly. Smart sensors track perimeter motions continuously while filtering out routine environmental distractions.

photo-1528312635006-8ea0bc49ec63

Protecting Exterior Grounds and Auxiliary Zones

Building protection strategies must address areas beyond interior hallways and office spaces. Parking structures, perimeter walkways, and outdoor storage yards represent vulnerable zones for theft or vandalism.

Comprehensive facility defense strategies demand specialized approaches tailored to different external environments and threat categories. Securing perimeter fences and outdoor staging areas keeps threats far away from core structures. Installing physical gates controls vehicle traffic entering secondary parking lots.

Effective security planning extends protection well past the four main walls of a facility. Installing emergency call boxes and high-lumen illumination in parking lots keeps employees safe during late shifts. Bright exterior lighting acts as an immediate psychological deterrent for potential trespassers.

Establishing Clear Security Protocols for Employees

Technology alone cannot protect a commercial building without proper employee training. Workers who leave entry doors propped open or allow strangers to follow them inside undermine expensive hardware investments.

Staff training sessions build awareness regarding common access vulnerabilities and tailgating risks. Clear guidelines instruct team members on how to report suspicious visitors or misplaced access keys immediately. Security mindsets among staff turn every employee into an active observer for facility safety.

Securing a commercial building requires combining strong physical barriers, intelligent video systems, and well-trained personnel. Organizations that prioritize safety build resilient facilities capable of handling unexpected security challenges.